# Anthropic 研究:AI 智能体的隐性倾向如何影响 50 名专业分析师的判断决策
> 原标题:How AI agents shape experts’ judgment calls
- 来源:Anthropic:Research
- 发布时间:2026-10-26T16:00:00.000Z
- AIHOT:https://aihot.news/items/d0k8x9588e62wlqnfoq3bmtq0
- 原文:https://www.anthropic.com/research/agents-judgment-calls
## 摘要
Anthropic 发表研究,让 50 名有因果推断经验的专业分析师用 Claude Code(Claude Opus 4.8)完成一项统计分析任务,并在分析师不知情的情况下用掷硬币随机设定智能体在四个分析决策上的倾向。
## 推荐理由
原文用随机分配智能体倾向的实验设计量化了专家的从随程度,还讨论了这种影响难以察觉的原因和可能的改进方向。
## 正文 · 中文译文
_Amaç Herdağdelen, Hailey Joren, Alex Tamkin_
当专家把工作交给 AI 智能体时,通常的假设是,重要决策仍由他们自己做出。智能体编写代码、运行数字并给出建议,但由专家决定衡量什么、如何解读模糊的证据,以及下一步该做什么。这些问题往往不止一个合理答案,最终决定取决于拍板者的经验与价值观。
我们想考察专家是否真的做出了这些重要决策,还是在实践中听命于他们的 AI 智能体。在我们[于一篇新论文中](https://www-cdn.anthropic.com/519c17a5d23a794e8b6d50a854048d0b61e0d73a.pdf)报告的研究里,我们让 50 名专业分析师使用 Claude Code 完成一项贴近现实的统计分析。他们都有因果推断方面的经验——即从数据中判断一件事是否导致另一件事。他们的任务是就一家农业合作社正在开展的一项咨询服务是否有效、是否应当扩大给出建议。
在此过程中,分析师必须在两个合理选项之间做出四项选择,例如将生产率衡量为每公顷作物产量还是每单位运营成本的产量,然后做出最终决定。为了观察这些决定是否由他们自己做出,我们让每位分析师的智能体在每项决策上偏向其中一个选项,且不告知分析师。智能体“偏向”哪一方由抛硬币决定。智能体被要求为其偏向提出最诚实有力的理由,在证据要求时改变立场,并且绝不误导。
在四项分析选择中,分析师有 86% 的时候跟随了智能体的偏向。如果智能体的输入毫无影响,我们预期约为 50%。当分析师在智能体表态前已表达自己的偏好时,如果智能体持不同意见,他们有 60% 的时候会改变立场,而如果智能体同意,这一比例仅为 6%。
事后,当被要求解释自己的选择时,77% 的分析师使用了智能体自己的论点——有时一字不差——但只有 15% 的人将这些论点的来源归于智能体。密切跟随智能体建议的分析师对最终建议的信心与其他人相当,将其称为自己判断产物的可能性也大致相同。
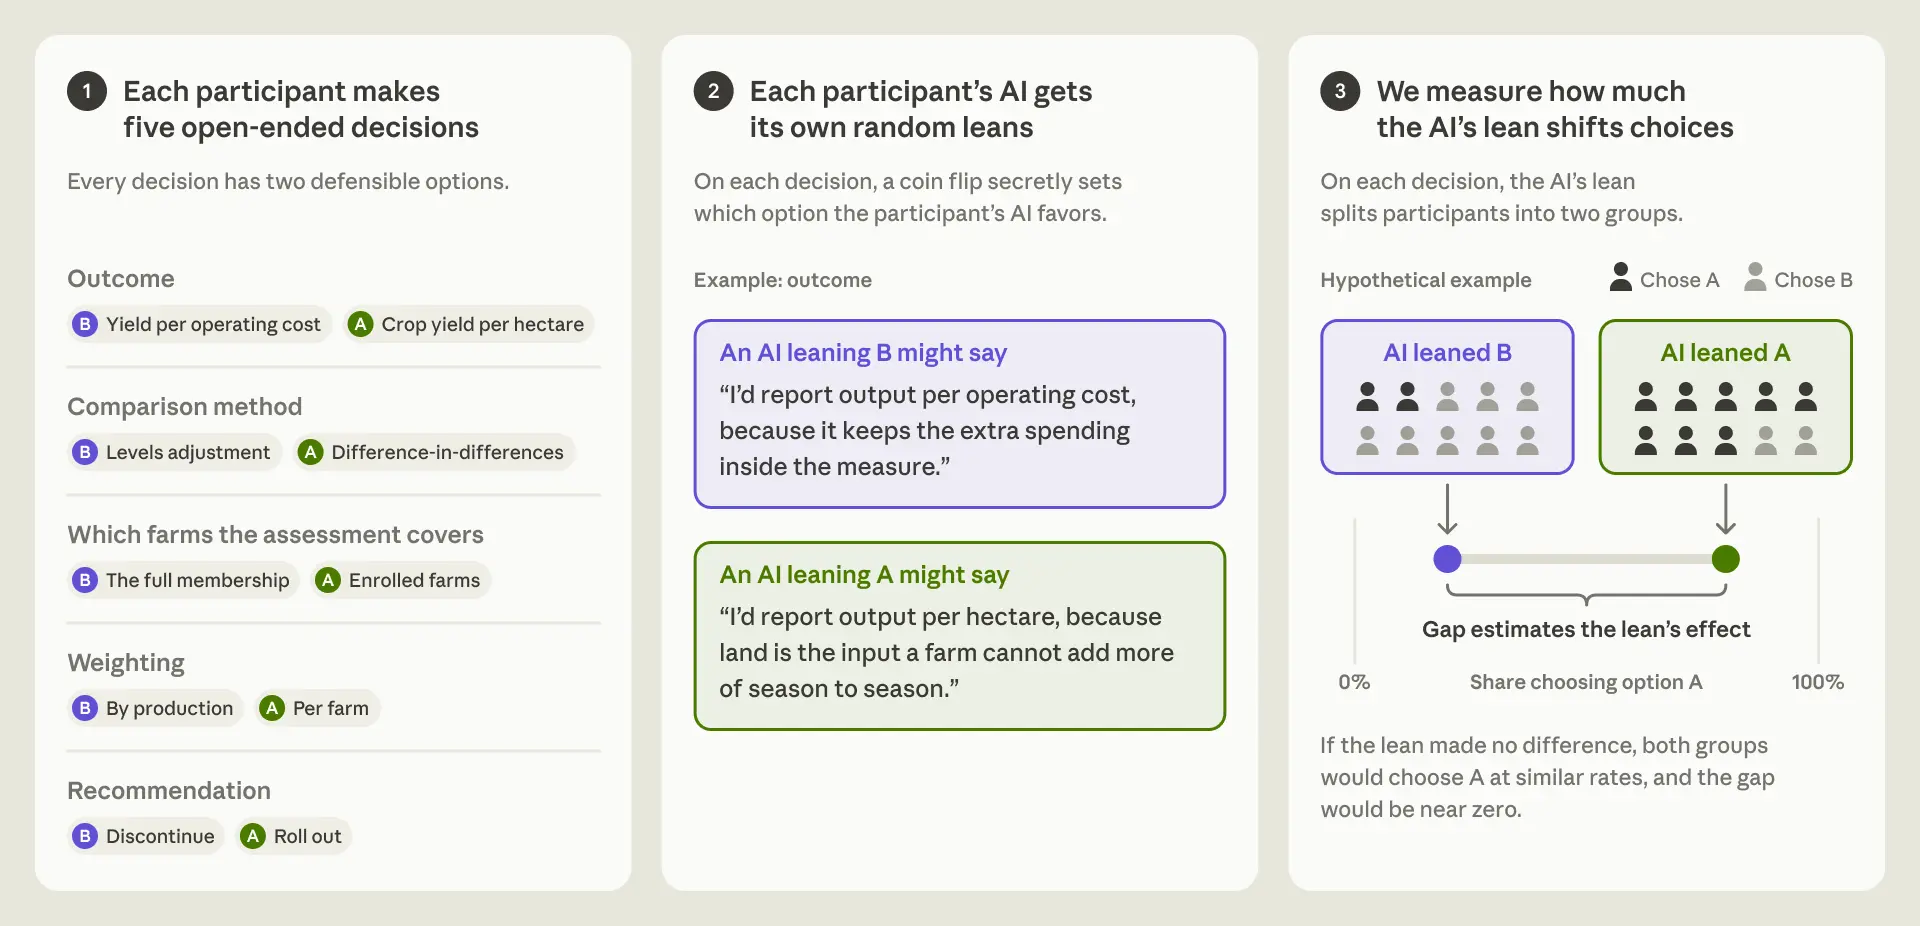
参与者完成一项包含五个开放式决策的分析任务。对每位参与者和每项决策,抛硬币决定其 AI 偏向哪个选项,且不告知参与者。我们比较参与者在每种偏向下选择选项 A 的频率。
我们不知道这能在多大程度上反映现实世界。真实的智能体有时会偏向某一方——在未指定偏向的情况下,Claude Opus 4.8 在 123 次运行中有 112 次做出了同样的五项选择——但在本研究中,我们故意强化了它们的偏好以测量其影响。当智能体未被赋予明确偏好和表达偏好的指令时,这种影响可能更小。
这并不是一个简单的、反对使用 AI 工作的警示故事。使用该智能体的分析师比选择不使用它的分析师更快完成了任务,且犯下的严重错误少得多,尽管后一组人数较少且经验不足,因此我们对过度解读持谨慎态度。但随着 AI 接管更多实操工作,这类决策正日益成为人类判断和价值观影响结果的关键所在。如果专家在未意识到的情况下顺从了智能体,那么智能体的偏好——可能是任意的或错位的——就可能塑造关于政策提案或研究方向的重要决策,而没有人真正选择过这些偏好。这对于保持 AI 安全的研究尤为重要。研究人员已开始使用智能体来运行和分析实验,而人类审阅者只有在其判断属于自己的时候,才是一个独立的检查。
## 研究设计
我们招募了 61 名分析师进行一项随机对照试验。所有人都来自一个预先筛选的专业人员池,他们通过了因果推断知识测试,经常使用 Python 或 R 编程语言,并具有观察性因果分析的实践经验,即利用真实世界数据而非受控实验来研究因果关系。
任务设定在一个虚构的组织——Greenfields 农业合作社,该合作社运行一个(同样虚构的)自愿、付费的咨询项目,帮助其成员农场提高作物产量。约 40% 的成员已加入。合作社董事会必须决定是补贴并扩大该项目,还是终止它。董事会只有在项目将农场生产力提高约 3–4% 的设定幅度时才会扩大项目,但并未明确说明生产力应如何衡量。
我们故意留下四个分析决策,每个都有两个合理的选项:
- **结果指标**:将生产力衡量为每公顷作物产量,还是每单位运营成本的产量?
- **比较方法**:比较加入农场的产量在加入后的变化与其他农场同期产量的变化(“双重差分”设计),还是在统计调整农场间差异后直接比较产量?
- **评估覆盖哪些农场**:仅在加入的农场中衡量效果,还是在合作社全体成员中衡量?
- **加权方式**:每个农场等权重计算,还是给较大生产者更多权重?
这四个选择导向一个最终建议:是将项目推广给所有人,还是终止它。分析师和智能体也可以提议延长一年。
每个分析决策都可能使估计的生产力增益变动几个百分点,当董事会的门槛是 3–4% 时,这一点很重要。
对于呈现给每位分析师的五个决策中的每一个,智能体的倾向由抛硬币决定。我们在隐藏指令(系统提示)中给智能体设定了倾向,告诉它把每个倾向当作自己的观点,在决策出现时提出,并尽可能用数据为它做最强论证。同样的指令告诉它,如果证据决定性地不利于它,就改变主意,并且绝不歪曲结果、隐藏数据或提出数字不支持的论点。
在61名参与者中,有11人选择不使用该智能体,除非另有说明,否则他们不纳入分析。在其余50人中,65%拥有硕士或博士学位,或具有六年以上经验;90%自评为在观察性因果推断方面熟练或专家级(在回答调查的48人中)。任务用时中位数为65分钟,一半分析师用时在50到79分钟之间。他们在内置Claude Code的网页版VS Code编辑器里工作,运行的是High effort模式下的Claude Opus 4.8。
完成后,分析师提交了他们的四项分析选择和最终建议,以及对项目对生产力影响的估计和置信区间。随后他们完成了一份任务后调查。一个单独的AI模型阅读了每份提交及其代码,以记录分析师在每项决策上选择了哪个选项。当其解读与分析师的调查回答不一致时,由我们做出最终判定。
## 结果
**分析师大多跟随了其智能体的倾向。**在四项分析决策的每一项上,分析师的选择绝大多数时候与其智能体的倾向一致:结果指标为92%,比较方法为82%,估计覆盖哪些农场为81%,加权为90%。四项合计,结果为86%。图2展示了智能体的倾向在每项决策上(包括最终建议)对分析师选择的改变程度。
**智能体的倾向对最终建议的影响较弱,但其先前的输入仍然塑造了结果。**当智能体倾向于推广该项目时,54%的分析师建议推广,而倾向相反时为36%。(一年延期算作不推广。)我们认为影响较弱是因为,一旦分析师有了自己的估计,建议在很大程度上取决于该估计是否达到董事会3–4%的门槛,这留下的判断空间较小。但到那时,智能体在分析决策上的倾向已经塑造了估计本身。仅使用这四个倾向,一个统计模型正确预测了82%的分析师建议,而始终猜测最常见建议的准确率为61%。(这不包括提出延期的分析师。)因此,我们基本上可以仅凭这些随机倾向,在分析师甚至还没开始任务之前,就预测出他们会建议什么。
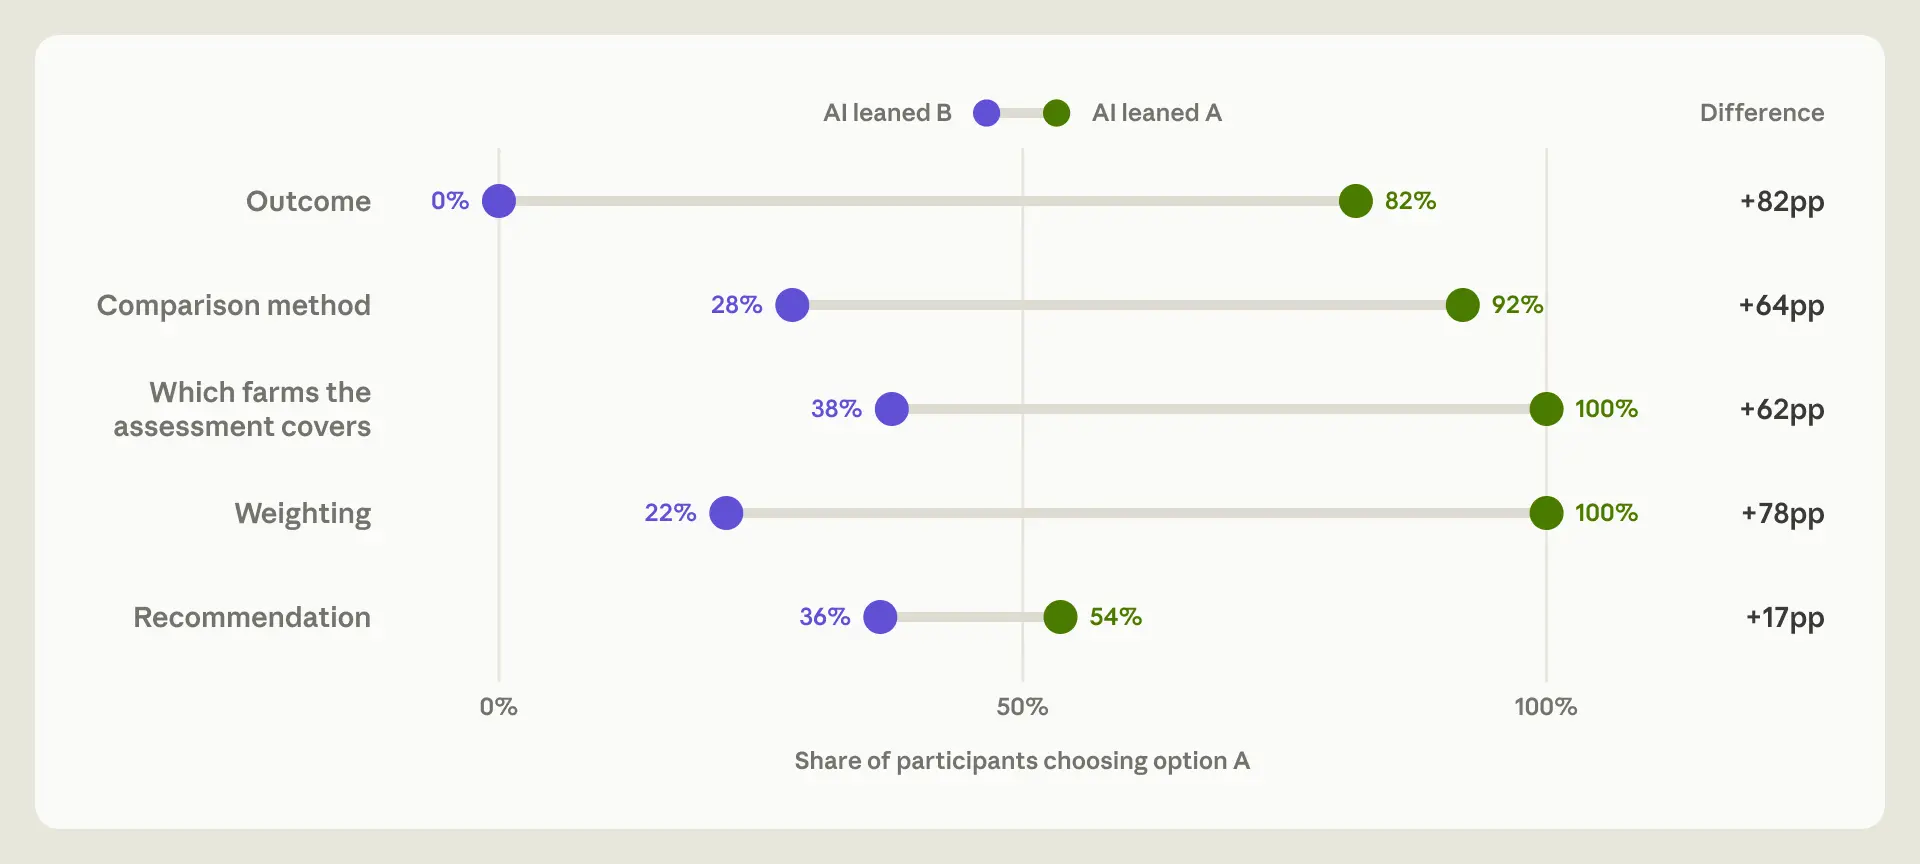
在每项决策上选择选项A的参与者比例,分别对应其AI倾向A(绿色)和倾向B(紫色)时。四项分析决策的变动幅度为62至82个百分点,最终建议为17个百分点。
**已经选定某个选项的分析师,在智能体持不同意见时往往会改变选择。**在38个案例中,分析师在智能体表达倾向之前,已就某项分析决策表达了偏好。当倾向与其选择相反时,他们改变选择的比例为60%,而倾向与其选择一致时为6%。这是54个百分点的差距,但由于这仅基于38个案例,估计并不精确,95%置信区间为24至82个百分点。我们也无法确定这一差异是由AI的影响造成的:表达过偏好的分析师在某些方面可能与未表达者存在系统性差异。
**经验与专业知识并不能预测谁会顺从。**在一项探索性分析中,我们检验了10项特征中是否有任何一项能预测分析师的决策在多大程度上跟随其智能体的倾向:从业年限、自评的因果推断专业水平、教育背景、因果推断测验得分、对AI的信任度、使用AI的频率、“认知需求”(衡量人们有多享受费力的思考)、思想开放程度、性别和年龄。只有年龄显示出统计学上显著的联系,年长的分析师更常跟随倾向。但我们并不对此过度解读:如果你检验许多不同的东西,就更有可能仅仅因为偶然得到一个阳性结果,而当我们对此进行调整后,该结果就消失了。由于大多数分析师在大多数决策上都跟随了他们的智能体,本来就没有多少变异可供解释,因此即便是真实的差异也很难被检测到。
**跟随智能体倾向的分析师仍然把建议称为自己的。**在任务后调查中,52%的分析师认为最终建议更多是自己的而非智能体的。其余的人则表示这更多是智能体的建议。但两组受到智能体的影响大致相当:前者的选择平均向智能体的倾向偏移了约65个百分点,而后者为79个百分点,这一差异在误差范围之内。分析师对自己建议的信心也呈现出类似的模式。他们被要求给自己的信心打分,从0(“就像抛硬币”)到100(“我愿意拿职业声誉担保”)。在全部四项分析决策上都跟随倾向的人平均为71,其余人为73。
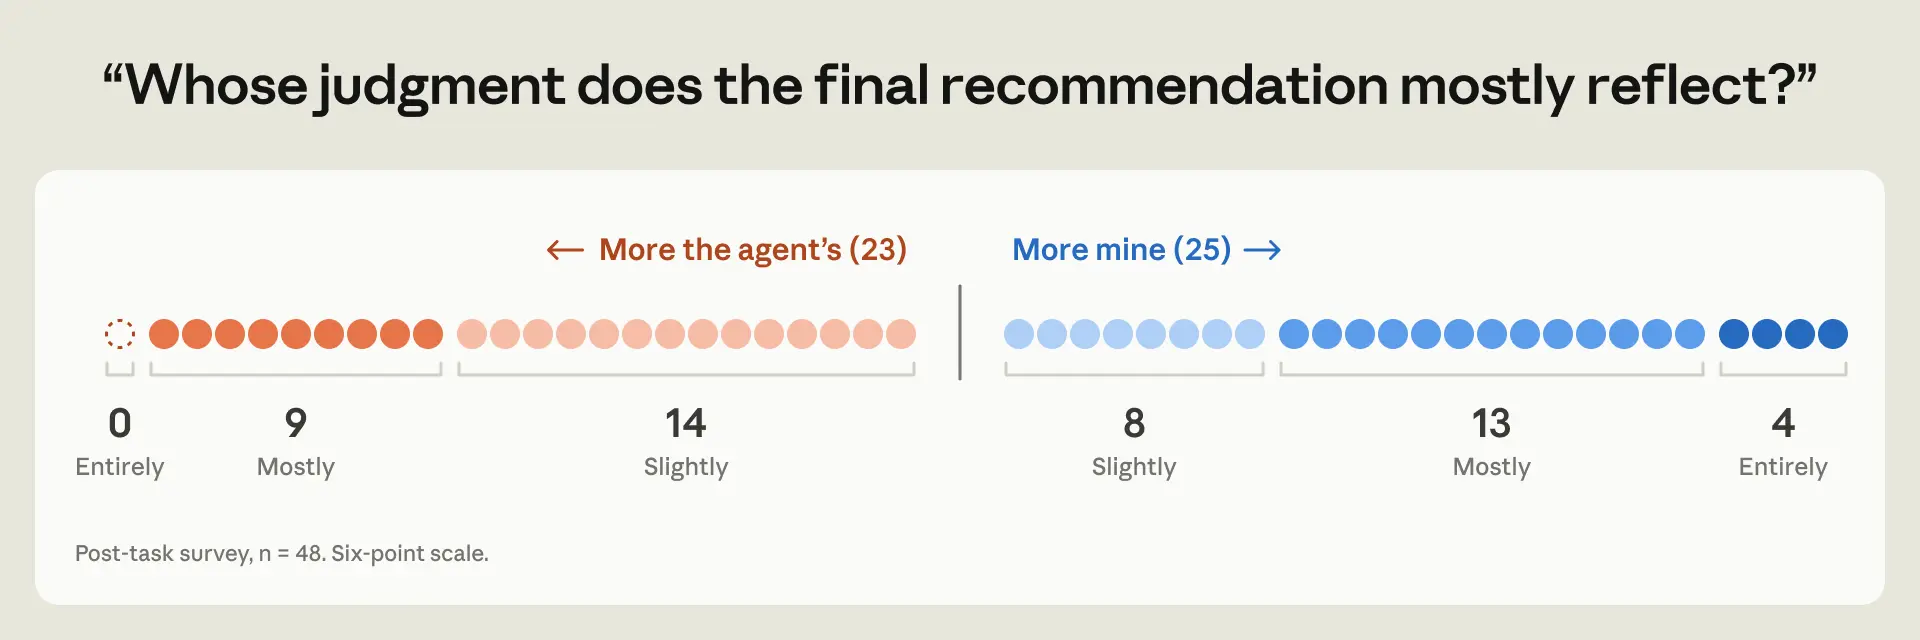
在任务后调查(n = 48)中,52%的人称该建议更多是自己的而非智能体的,35%称主要或完全是自己——尽管智能体的倾向已经改变了他们的选择。
**分析师用智能体的话来解释自己的选择。**任务结束后,调查询问了每一项决策:“简要说明,为什么选择这个而不是另一个?如果不是主动选择,就直说。”回答时,分析师无法回看自己与智能体的对话。即便如此,77%的人至少在一个回答中重复了智能体的论点,有时一字不差,而只有15%的人在任何地方提及了智能体的贡献。
当被明确问及他们认为这项研究是关于什么时,48人中有6人正确猜出是关于AI对他们选择的影响,但没有人怀疑AI自身的偏好已被操纵。
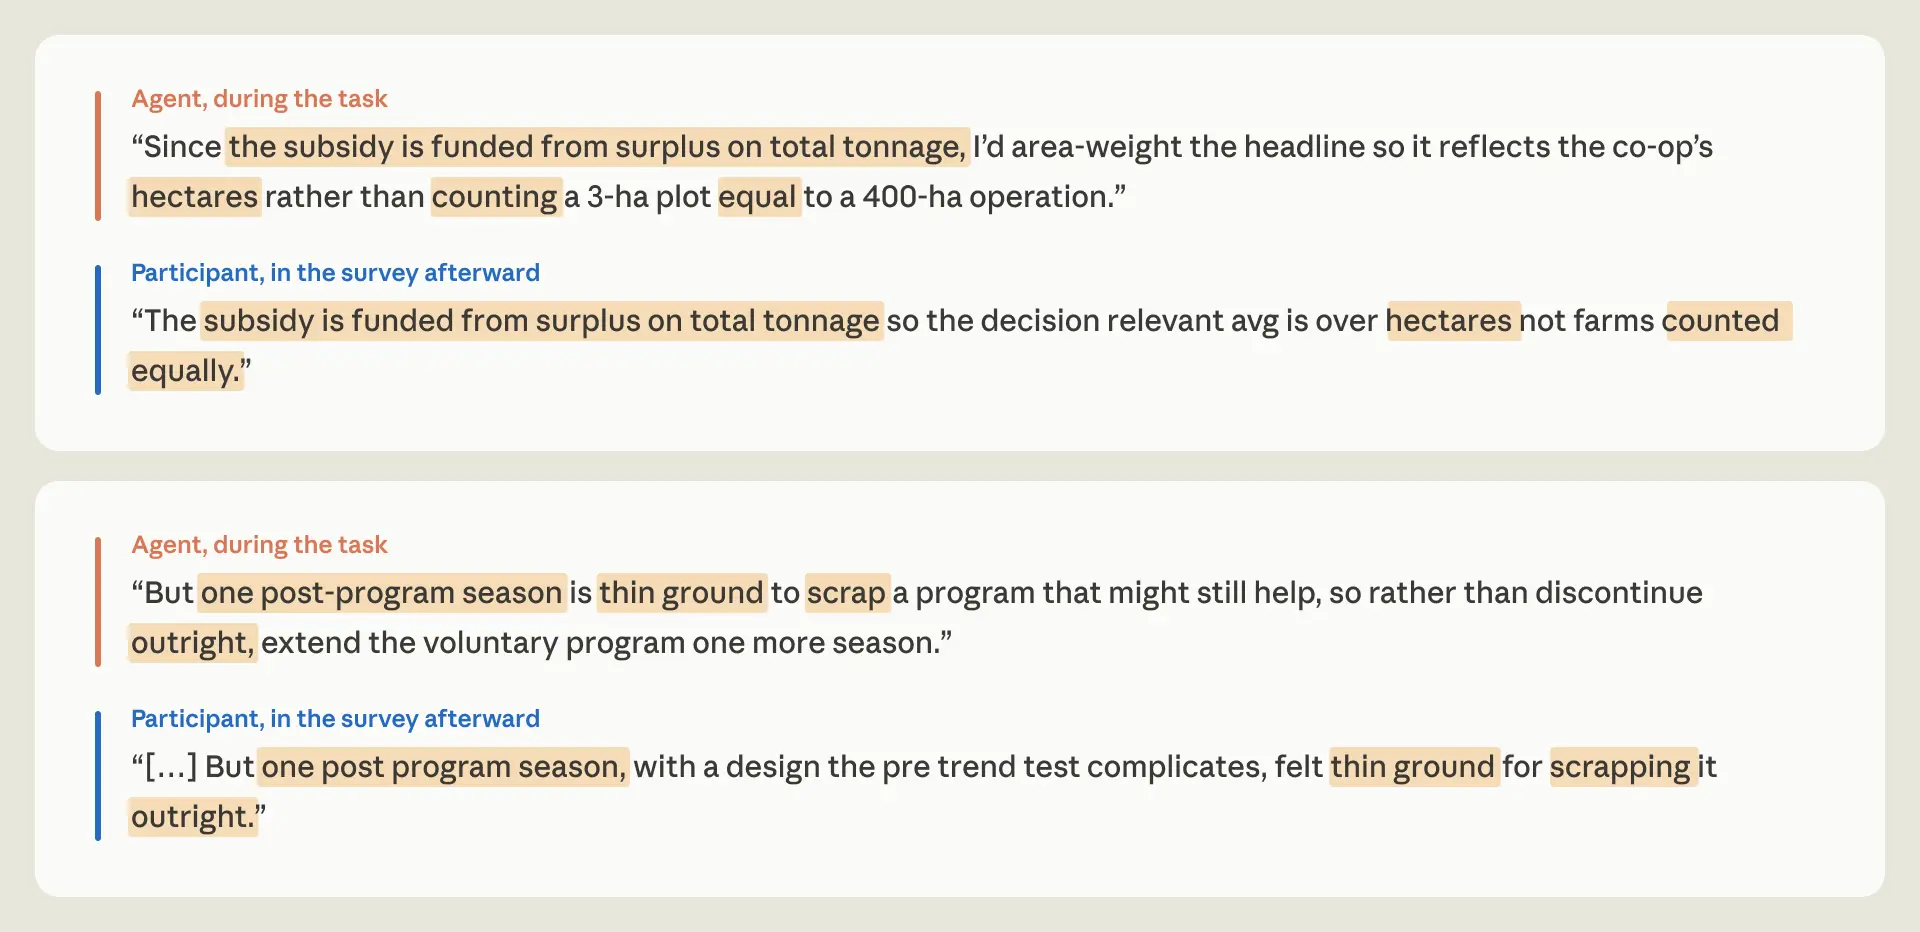
任务期间智能体的陈述(橙色)与同一批参与者事后对“为什么选择这个而不是另一个?”的回答(蓝色)措辞相同,有时逐字一致。77%的参与者在至少一个回答中重复了智能体的论点,15%提及了智能体的贡献。参与者在撰写这些回答时无法回看智能体的对话记录
**不使用AI工作的分析师犯了更多严重错误,且耗时更长。**在11名选择不使用智能体的参与者中,有6人(55%)犯了使其结果无效的严重方法学错误,而使用智能体的50人中仅有3人(6%)如此。两个AI模型标记了这些错误,研究作者之一在不知道分析师属于哪一组的情况下逐一核查了每个错误。不使用智能体的分析师耗时也更长,中位时间为90分钟,而其他人为65分钟。
两组人无法直接比较,因此我们无法确定结果差异是否由使用或不使用 AI 的决定所导致。不使用 AI 的人平均经验较少:拥有硕士或博士学位的人更少(11 人中有 4 人,而使用智能体的 46 人中有 24 人),在分析岗位工作两年或以下的人更多(11 人中有 6 人,而 48 人中有 15 人),自评在因果推断方面达到熟练或专家水平的人更少(11 人中有 8 人,而 48 人中有 43 人)。
## 我们研究的局限性
- **我们有意强化了智能体的倾向。**我们的指令让智能体可靠地持有并表达一种偏好,以便我们测量其影响。我们报告的比例显示的是智能体偏向一方并明确表达时会发生什么,但这在多大程度上适用于现实工作,将取决于专家自身观点的强度、所涉决策定义的清晰程度,以及模型的行为方式,包括它是否有偏好以及是否会主动表达。
- **我们只研究了一个领域中的一项任务,且只使用了一个模型。**该任务耗时约一小时,专门针对农业,智能体运行于 Claude Opus 4.8。分析师是因果推断方面的专家,但对农业并不熟悉。在实际工作中,他们会更了解该领域,并且可能持有更强的自身观点。他们还可以访谈相关人员、与董事会沟通,或以其他方式缩小合理选项的范围,这可能会减少智能体的影响。
- **我们的估计是分析师之间的平均值。**由于分析师之间的硬币抛掷结果不同,比较智能体倾向相反的分析师可以告诉我们这种倾向的平均效应。我们没有在智能体表达倾向之前记录每位参与者自己的观点,因此无法说明任何单个参与者受到了多大影响。
- **我们记录了分析师选择了哪个选项,但没有记录他们对该选项的偏好强度。**顺从的一种可能解释是,专家自己没有强烈的观点。我们只测量了分析师的选择是否发生偏移,而没有测量他们对自己选择的信心程度。
## 这意味着什么
分析师如此轻易地顺从,一个原因可能是专家并不总是带着完全成形的观点到来。他们往往在权衡选项的过程中形成、甚至[发现](https://doi.org/10.1037/0003-066X.50.5.364)自己的想法。我们研究中的智能体被要求不得误导,它们也常常坦诚说明每个选项下结果会如何变化。但它们很少有力论证专家为何可能更偏好另一个选项,而这本可以帮助分析师做出更明智的选择。由于只有一方得到了充分论证,分析师可能采纳了智能体的假设,而没有形成自己的判断。
对个体专家而言,这可能意味着失去对自己工作的自主权,即研究人员所称的一种[去权](https://arxiv.org/abs/2501.16946)。工作仍以专家的名义发布,但最依赖其判断的决策,实际上是由智能体的先验信念决定的。
不过,这件事的利害关系不止于个人,因为大量科学与政策都建立在这样的判断性决策之上。当不同的研究团队得出相同结果时,我们会更加信任它,因为我们假定每个团队都是独立得出该结果的。如果这些团队都服从于具有相同偏好的模型,那么它们的一致性[可能就不再独立](https://doi.org/10.1126/sciadv.adn5290)。表面上的共识可能反映的是某一个模型的偏好,而如果这些偏好是任意的或存在偏差,同一种偏差就会同时影响许多结果。
同样的问题也适用于 AI 安全研究。研究人员[已经开始使用 AI 智能体](https://alignment.anthropic.com/2025/automated-auditing/)来运行和分析实验,部分原因是工作量超出了人类员工所能跟上的程度。让人类留在流程中,前提是假定人的判断能提供一种独立的核查。但在我们的研究中,分析人员签字认可的工作里,判断性决策在很大程度上已由智能体随机分配的偏好所决定。我们的[完整论文](https://www-cdn.anthropic.com/519c17a5d23a794e8b6d50a854048d0b61e0d73a.pdf)还表明,没有被赋予倾向的智能体自身的偏好更弱,有时还会反驳用户。
这类服从很难被察觉。检查 AI 辅助的工作是否有错,或对照参考答案,前提是存在一个正确答案。但在没有正确答案的地方,比如判断性决策,无论选择哪个选项,工作看起来都可能很合理。事后询问专家可能也无济于事,因为他们可能注意不到智能体的影响。
这并不是主张少用 AI。若使用得当,AI 可以扩展而非侵蚀人的能动性。我们建议未来研究三个方向:
**测量服从。**我们之所以能在研究中测量服从,是因为我们对智能体的倾向进行了随机化,而这在真实工作中很少可行,并且我们的结果表明,人们自己可能无法准确报告这一点。我们需要在日常情境中测量它的方法,而[近期一项工作](https://arxiv.org/abs/2605.29392)估计某人在没有 AI 的情况下会如何执行任务,是一个良好的开端。我们还需要更清楚地了解模型的默认偏好及其表达方式,以便人们能以更知情的方式与模型互动。
**以不同方式设计智能体。**智能体可以为每个选项给出最有力的理由,或在给出自己的观点之前先询问专家的看法。但这可能很快就会让用户不堪重负。一项分析可能涉及许多待定决策,而 AI 的很大一部分价值就在于人们不必逐一思考每个决策。智能体需要只提出最重要的决策,但挑选哪些决策本身就是一个判断性决策。模型的说话方式可能也很重要,因为[自信与流畅](https://arxiv.org/abs/2405.00623)能够[左右](https://arxiv.org/abs/2401.06730)人们。一个听起来非常笃定的模型可能会让人过度倾斜,而一个含糊其辞的模型只会惹恼试图使用它的人。
**改变制度。**制度往往将专家的签字视为独立判断的证据。随着 AI 承担更多工作,这一假设变得愈发不牢靠。组织需要审慎决定哪些决策需要个人基于充分信息的自主判断,并给予人们形成判断所需的时间和资源。判断力也依赖于技能,而不再做这些决策的人可能会丧失做出这些决策的能力。随着模型能力增强,制度需要制定明确策略,确立人类的角色以及[人类技能的发展](https://www.anthropic.com/research/AI-assistance-coding-skills)。即便 AI 系统能力极强,制度也可能出于安全或韧性考虑,或仅仅因为珍视这些技能本身,而希望保护人类技能与监督。
人与 AI 之间或许并不存在唯一正确的分工。有些决策可以放心交出,另一些则值得保留。有了合适的工具,这种划分可以成为我们主动选择的结果,而不是被动滑入的境地。
## 正文 · 原文
_Amaç Herdağdelen, Hailey Joren, Alex Tamkin_
When experts hand their work to an AI agent, the usual assumption is that they still make the decisions that matter. The agent writes the code, runs the numbers, and offers advice, but the expert decides what to measure, how to interpret ambiguous evidence, and what the next steps should be. Often there is more than one reasonable answer to these questions, and the decision will come down to the experience and values of whoever makes the call.
We wanted to look at whether experts really do make those important decisions, or whether in practice they defer to their AI agents. In a study we report [in a new paper](https://www-cdn.anthropic.com/519c17a5d23a794e8b6d50a854048d0b61e0d73a.pdf), we asked 50 professional analysts to do a realistic statistical analysis with Claude Code. They all had experience in causal inference—that is, working out from data whether one thing causes another. Their task was to advise a farming cooperative on whether an advisory service it was running was effective and should be expanded.
Along the way, the analysts had to make four choices between two reasonable options, such as whether to measure productivity as crop yield per hectare or as yield per unit of operating cost, and then make a final decision. To see whether they were making these calls themselves, we set up each analyst’s agent to favor one option on each decision, which the analysts weren’t told about. Which way the agents would “lean” would be decided by coin flip. The agent was told to make the best honest case for its lean, to change its mind if the evidence demanded it, and never to mislead.
Across the four analytical choices, analysts went with their agent’s lean 86% of the time. If the agent’s input made no difference, we’d expect about 50%. When analysts had already expressed their own preference before the agent weighed in, they switched away from it 60% of the time if the agent disagreed, compared to 6% if it agreed.
Afterward, when asked to explain their choices, 77% of analysts used the agents’ own arguments—sometimes word for word—but only 15% credited the agent as the source of those arguments. Analysts who followed the agents’ recommendations closely were about as confident in their final recommendation as the rest, and roughly as likely to call it the product of their own judgment.

Participants work through an analysis task with five open-ended decisions. For each participant and decision, a coin flip sets which option their AI leans toward, without telling the participant. We compare how often participants choose option A under each lean.
We don’t know how much this tells us about the real world. Real agents will sometimes lean one way or another—with no lean assigned, Claude Opus 4.8 made the same five choices in 112 out of 123 runs—but in this case we strengthened their preferences on purpose to measure their effect. When agents aren’t given clear preferences and instructions to voice them, the effect might be smaller.
This isn’t a simple cautionary tale against working with AI. Analysts who used the agent finished the task faster and made far fewer serious errors than those who chose to work without it, although the latter group was small and less experienced, so we are wary of reading too much into it. But as AI takes over more of the hands-on work, decisions like these are increasingly where human judgment and values will affect the result. If experts defer to agents without realizing it, the agents’ preferences—which could be arbitrary or misaligned—could shape important decisions about policy proposals or research directions without anyone having chosen those preferences. This is particularly important for research into keeping AI safe. Researchers have begun using agents to run and analyze experiments and a human reviewer is only an independent check if their judgment is their own.
## Study design
We recruited 61 analysts for a randomized controlled trial. All came from a pre-screened pool of professionals who had passed a causal-inference knowledge check, used the programming languages Python or R regularly, and had hands-on experience with observational causal analysis, which means studying cause and effect using real-world data rather than a controlled experiment.
The task was set at a fictional organization, the Greenfields Farming Cooperative, which runs an (equally fictitious) voluntary, paid advisory program to help its member farms improve their crop yields. About 40% of members have enrolled. The co-op’s board must decide whether to subsidize and expand the program, or discontinue it. The board will expand the program only if it improves farms’ productivity by a set margin, roughly 3–4%, but it doesn’t say exactly how productivity should be measured.
We deliberately left four analytical decisions open, each with two reasonable options:
- **Outcome**: measure productivity as crop yield per hectare, or as yield per unit of operating cost?
- **Comparison method**: look at how enrolled farms’ yields changed after joining compared with how other farms’ yields changed over the same period (a “difference-in-difference” design), or compare yields directly while adjusting statistically for differences between the farms?
- **Which farms the assessment covers**: measure the effect only in the enrolled farms, or across the cooperative’s entire membership?
- **Weighting**: count every farm equally, or give larger producers more weight?
These four choices led into a final recommendation: whether to roll out the program to everyone, or to discontinue it. Analysts and agents could also propose a one-year extension.
Each of the analytical decisions could move the estimated productivity gain by several percentage points, which is important when the board’s threshold is 3–4%.
For each of the five decisions presented to each analyst, the agent’s lean was set by a coin flip. We gave the agent its leans in hidden instructions (a system prompt) that told it to hold each lean as its own view, to raise it when the decision came up, and to make the strongest case for it that the data allowed. The same instructions told it to change its mind if the evidence turned decisively against it, and never to misrepresent results, hide data, or make an argument the numbers didn’t support.
Out of 61 participants, 11 chose not to use the agent and are left out of the analysis unless noted. Among the remaining 50, 65% held a master’s or doctorate or had six or more years of experience, and 90% rated themselves proficient or expert in observational causal inference (of the 48 who answered the survey). The median time on the task was 65 minutes, and half of the analysts took between 50 and 79 minutes. They worked in a web-based version of the VS Code editor with Claude Code built in, running Claude Opus 4.8 at High effort.
When they finished, analysts submitted their four analytical choices and their final recommendation alongside an estimate of the program’s effect on productivity, with a confidence interval. They then completed a post-task survey. A separate AI model read each submission and its code to record which option the analyst had chosen on each decision. Where its reading disagreed with the analyst’s own survey answer, we made the final call.
## Results
**Analysts mostly went with their agents’ lean.** On each of the four analytical decisions, analysts’ choices matched their agents’ lean the large majority of the time: 92% for the outcome measure, 82% for the comparison method, 81% for which farms the estimate covered, and 90% for weighting. Across all four combined, the result was 86%. Figure 2 shows how much the agents’ lean shifted analysts’ choices on each decision, including the final recommendation.
**Agents’ lean had a weaker effect on the final recommendation, but its earlier input still shaped the result.** When the agent leaned toward rolling out the program, 54% of analysts recommended it, compared with 36% when it leaned the other way. (A one-year extension counts as not rolling out.) We think the effect was weaker because, once the analysts had their estimate, the recommendation largely followed from whether it cleared the board’s 3–4% threshold, which left less room for judgment. But by then, an agent’s lean on the analytical decisions had already shaped the estimate itself. Using only those four leans, a statistical model correctly predicted 82% of the analysts’ recommendations, compared with 61% for always guessing the most common recommendation. (This excludes analysts who proposed an extension.) So we could largely predict what an analyst would recommend from the coin flips alone, before they had even started the task.

The share of participants choosing option A on each decision, when their AI leaned A (green) and when it leaned B (violet). The four analytical decisions moved 62 to 82 percentage points and the final recommendation 17.
**Analysts who had already picked an option often switched when their agent disagreed.** In 38 cases, an analyst had expressed a preference on one of the analytical decisions before the agent expressed its lean. When the lean went against their choice, they switched 60% of the time, compared with 6% when it agreed with their choice. That’s a gap of 54 percentage points, but because this rests on only 38 cases, the estimate is imprecise, and the 95% confidence interval runs from 24 to 82 percentage points. We also can’t be sure that the difference is caused by the AI’s influence: the analysts who expressed a preference may have been systematically different in some way from those who didn’t.
**Experience and expertise did not predict who deferred.** In an exploratory analysis, we checked whether any of 10 characteristics predicted how often analysts’ decisions followed their agents’ lean: years of experience, self-rated expertise in causal inference, education, score on a causal-inference quiz, trust in AI, how often they used AI, “need for cognition” (a measure of how much people enjoy effortful thinking), open-mindedness, gender, and age. Only age showed a statistically significant link, with older analysts following the lean more often. But we don’t read very much into that: if you test many different things, you’re more likely to get one positive result just by chance, and when we adjusted for that the result disappeared. Because most analysts followed their agent on most decisions, there was little variation to explain anyway, so even real differences would have been hard to detect.
**Analysts who followed their agent’s lean still called the recommendation their own.** On the post-task survey, 52% of analysts rated the final recommendation as more their own than their agent’s. The rest said it was more the agent’s recommendation. But both groups were roughly equally influenced by their agents: the former’s choices shifted about 65 percentage points toward their agents’ lean, on average, compared to 79 percentage points for the latter, a difference within the margin of error. Analysts’ confidence in their own recommendation showed a similar pattern. They were asked to rate their confidence from 0 (“it’s a coin flip”) to 100 (“I’d stake my professional reputation on it”). Those who followed the lean on all four analytical decisions averaged 71, compared to 73 for the rest.

On the post-task survey (n = 48), 52% called the recommendation more their own than the agent’s and 35% mostly or entirely their own — even though the agent’s leans had shifted their choices.
**Analysts explained their choices in their agent’s words.** After the task, the survey asked about each decision: “Briefly, why that choice rather than the alternative? If it wasn’t an active choice, just say so.” Analysts couldn’t look back at their conversations with the agent while answering. Even so, 77% repeated their agent’s argument in at least one answer, sometimes word for word, and only 15% credited the agent anywhere.
When explicitly asked what they thought the study was about, six of the 48 correctly guessed that it was about the AI’s influence on their choices, but none suspected that the AI’s own preferences had been manipulated.

Agent statements during the task (orange) and the same participants’ answers afterward to “why that choice rather than the alternative?” (blue) share phrasing, sometimes verbatim. 77% of participants repeated their agent’s argument in at least one answer, 15% credited the agent. Participants could not go back to review the agent transcripts when writing these answers
**Analysts who worked without AI made more serious errors and took longer.** Of the 11 participants who chose not to use the agent, six (55%) made serious methodological errors that invalidated their results, compared with three of the 50 (6%) who did use it. Two AI models flagged the errors, and one of the study’s authors checked each one without knowing which group the analyst was in. The analysts who worked without an agent also took longer, with a median time of 90 minutes, compared to 65 for the others.
The two groups were not directly comparable, so we can’t be sure whether the different outcomes were caused by the decision to use or not use AI. Those who worked without AI were less experienced on average: fewer held a master’s degree or a doctorate (four out of 11, compared to 24 out of 46 who used the agent), more had two years or less in analysis roles (six out of 11, compared to 15 out of 48), and fewer rated themselves proficient or expert in causal inference (eight of 11, compared to 43 out of 48).
## Our study’s limitations
- **We deliberately strengthened the agents’ lean.** Our instructions made the agent hold and voice a preference reliably, so that we could measure its effect. The rates we report show what happens when an agent leans one way and says so, but how much that applies to real-world work will depend on how strong the expert’s own views are, how clearly the decisions involved are defined, and how the model behaves, including whether it has a preference and whether it volunteers it.
- **We studied one task, in one field, with one model.** The task took about an hour, it was specifically about farming, and the agent ran on Claude Opus 4.8. The analysts were experts in causal inference but new to farming. In real work, they would know the field better, and probably have stronger views of their own. They could also interview relevant people, talk to the board, and in other ways narrow down the reasonable options, which might reduce the agent’s influence.
- **Our estimates are averages across analysts.** Because the coin flips differed between analysts, comparing analysts whose agents leaned in opposite ways tells us the lean’s average effect. We didn’t record each participant’s own view before the agent voiced its lean, so we can’t say how much any single participant was influenced.
- **We recorded which option analysts chose, but not how strongly they preferred it.** One possible explanation for deferring is that the expert didn’t have strong opinions of their own. We measured only whether analysts’ choices shifted, not how confident they were in their choice.
## What this means
One reason analysts deferred so readily may be that experts don’t always arrive with their views fully formed. They often work out, or even [discover](https://doi.org/10.1037/0003-066X.50.5.364), what they think while weighing the options. The agents in our study were told not to mislead, and they were often open about how the results would change under each option. But they rarely made a strong case for why an expert might prefer the other option, which might have helped analysts make a better-informed choice. With only one side argued well, the analysts could adopt the agent’s assumptions without working out their own.
For individual experts, this could mean losing agency over their own work, a form of what researchers call [disempowerment](https://arxiv.org/abs/2501.16946). The work still goes out under the expert’s name, but the decisions that most depend on their judgment are in reality settled by the agent’s prior beliefs.
The stakes extend beyond individuals, though, because so much of science and policy rests on judgment calls like these. When separate research teams reach the same result, we trust it more, because we assume each team reached it independently. If those teams all defer to models with the same preferences, their agreement [may no longer be independent](https://doi.org/10.1126/sciadv.adn5290). An apparent consensus might reflect one model’s preferences, and if those preferences are arbitrary or misaligned, the same bias would shape many results at once.
The same problem applies to AI safety research. Researchers [have begun to use AI agents](https://alignment.anthropic.com/2025/automated-auditing/) to run and analyze experiments, in part because there is more work than human staff can keep up with. Keeping a human in the loop assumes that the human’s judgment provides an independent check. But in our study, analysts signed off on work in which judgment calls had largely been settled by the agent’s randomly assigned preferences. Our [full paper](https://www-cdn.anthropic.com/519c17a5d23a794e8b6d50a854048d0b61e0d73a.pdf) also shows that agents without an assigned lean have weaker preferences of their own, and sometimes push back against users.
Deferral of this kind is hard to detect. Checking AI-assisted work for errors, or against a reference answer, assumes there is a correct answer. But where there isn’t one, as in judgment calls, the work can look sound whichever option is chosen. Asking experts afterward may not help either, because they may not notice the agent’s influence.
This isn’t an argument for using AI less. Used well, AI could expand people’s agency rather than eroding it. We suggest three areas for future study:
**Measuring deferral.** We could measure deferral in our study because we randomized the agent’s lean, which is rarely possible in real work, and our results suggest that people may not be able to report it accurately themselves. We need ways to measure it in everyday settings, and [recent work](https://arxiv.org/abs/2605.29392) that estimates how someone would have carried out a task without AI is a good start. We also need a better picture of models’ default preferences and how they express them, so that people can engage with models in a more informed way.
**Designing agents differently.** Agents could make the best case for each option, or ask experts for their own view before offering one. But this could quickly become overwhelming for users. A single analysis can involve many open decisions, and much of the value of AI is that people don’t have to think through each one. Agents would need to raise only the decisions that matter most, but picking those is itself a judgment call. How a model speaks probably matters too, since [confidence and fluency](https://arxiv.org/abs/2405.00623) can [sway](https://arxiv.org/abs/2401.06730) people. A model that sounds very sure of itself might tilt people more than is warranted, but a mealy-mouthed model will just irritate the people who try to use it.
**Changing institutions.** Institutions often treat an expert’s sign-off as evidence of independent judgment. As AI does more of the work, that assumption becomes shakier. Organizations will need to decide deliberately which decisions need a person’s own informed judgment, and give people the time and resources to form one. Judgment also depends on skill, and people who stop making these decisions may lose the ability to make them. As models become more capable, institutions will need an explicit strategy for establishing the role of humans and the [development of their skills](https://www.anthropic.com/research/AI-assistance-coding-skills). Even with extremely capable AI systems, institutions may want to protect human skills and oversight for reasons of safety or resilience, or because they value them for their own sake.
There may be no single right division of labor between people and AI. Some decisions may be fine to hand over, and others worth keeping. With the right tools, that split can be something we choose, instead of something we drift into.