# Google DeepMind 发布 Gemini 4 Carbon 前沿模型
> 原标题:Gemini 4 Carbon: Our next frontier model
- 来源:Google DeepMind:Blog
- 发布时间:2026-10-28T17:00:58.000Z
- AIHOT:https://aihot.news/items/fjeloaahylonpc0pv5tduusud
- 原文:https://deepmind.google/blog/gemini-4-carbon-our-next-frontier-model/
## 摘要
Google DeepMind 发布 Gemini 4 Carbon,定位为最强前沿模型,主打网络安全与长程智能体能力,在 SEC-bench Pro 88.2%、ExploitGym 54.8%、CWE-bench 71.0% 取得领先,并以 59 分登顶 Artificial Analysis Intelligence Index v5.0。
## 推荐理由
官方公布 Gemini 4 Carbon 的安全编码与长程任务成绩和定价,可据此外推其在网络安全防御场景的实际定位。
## 正文 · 中文译文
2026年10月28日
|
Gemini 4 Carbon 是我们最强的模型,具备最先进的网络安全能力和长时程能力。
* * *
* * *
您的浏览器不支持音频元素。
收听文章
\[\[duration\]\] 分钟
此内容由 Google AI 生成。生成式 AI 仍处于实验阶段
今天,我们宣布推出下一代前沿模型:Gemini 4 Carbon,这是我们最强的模型,具备最先进的网络安全能力和长时程能力。
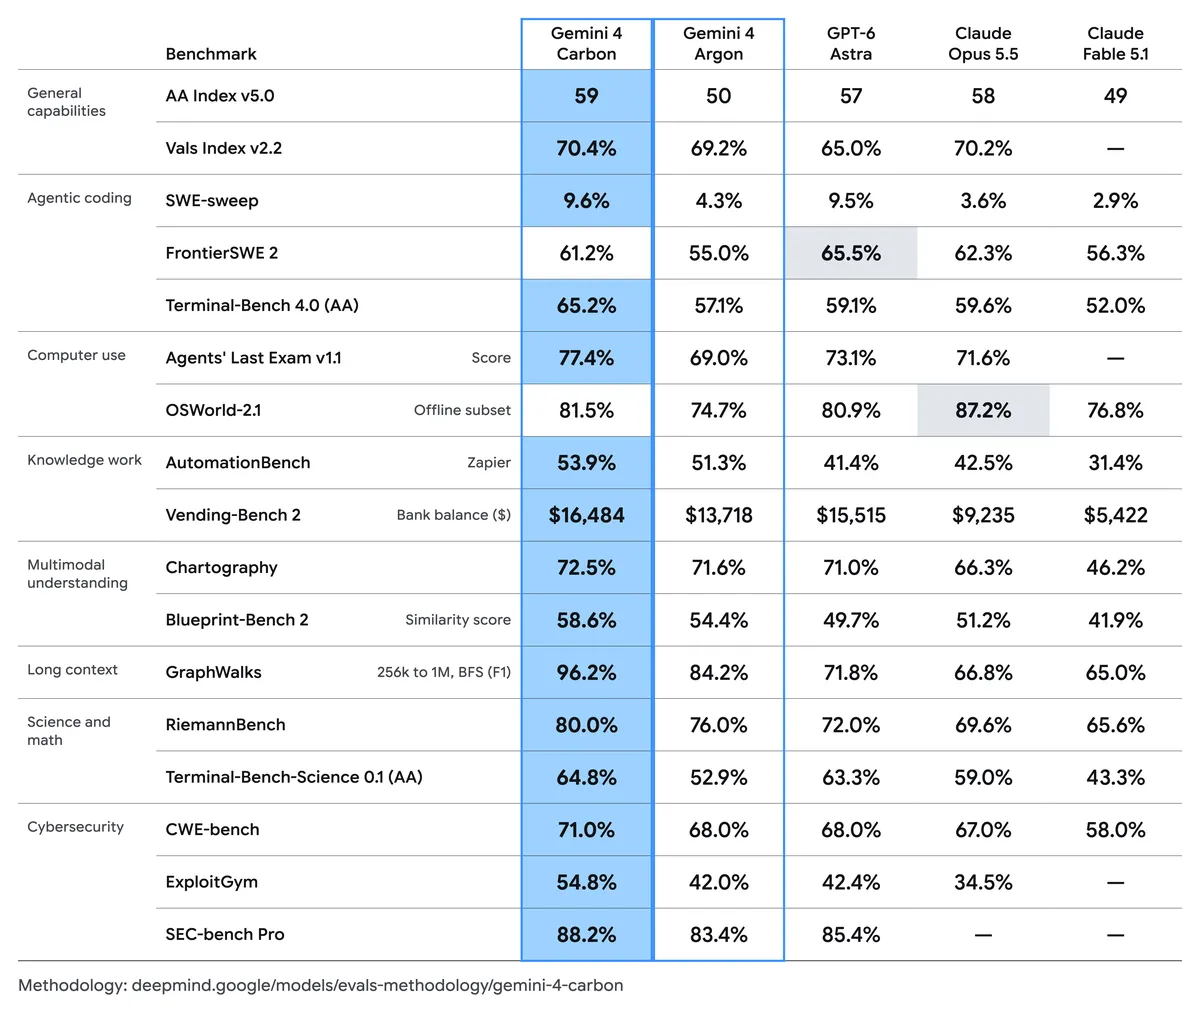
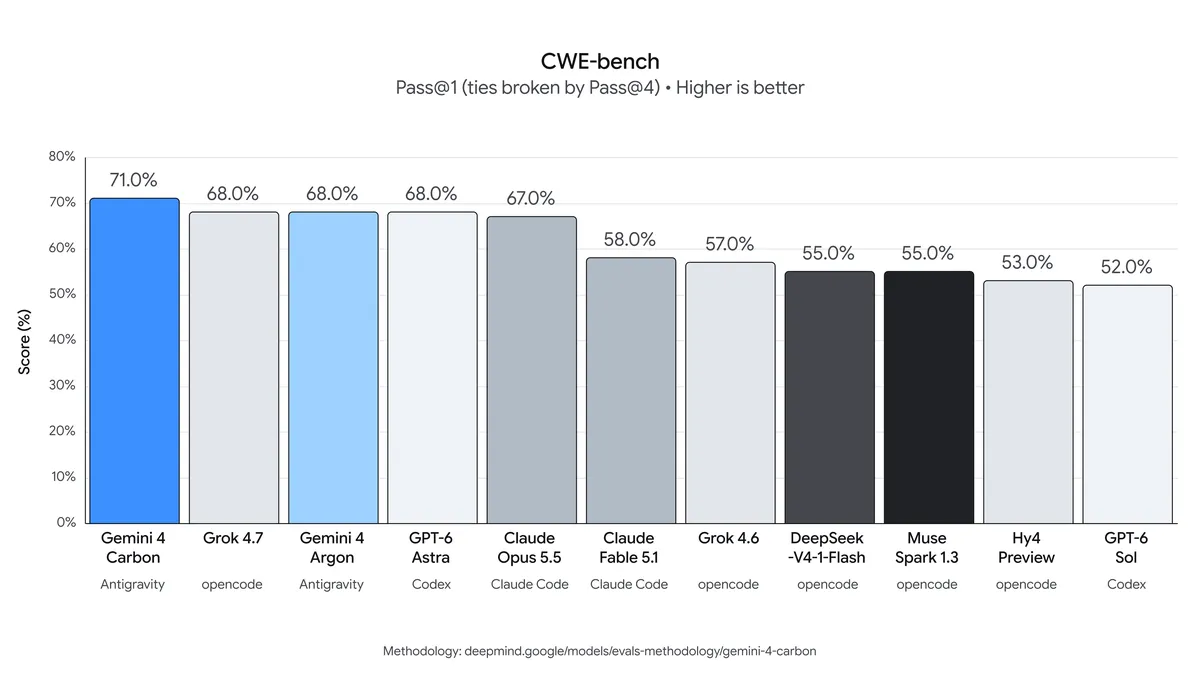
Carbon 在最近更新的 v5.0 [Artificial Analysis Intelligence Index](https://artificialanalysis.ai/evaluations/artificial-analysis-intelligence-index) 上以 59 分排名第一。它在编码和智能体任务以及网络安全防御关键的几项核心能力上均有显著提升,在漏洞发现 SEC-bench Pro(88.2%)、漏洞利用 ExploitGym(54.8%)和补丁修复 CWE-bench(71.0%)上均取得明显领先。在内部基准测试中,Carbon 在生成安全代码方面带来强劲提升,在我们自己团队的实时编码环境中,它表现出更低的对齐偏差和捏造率。
基于两周前发布的 [Gemini 4 Argon](https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-argon/),Carbon 展示了我们推进前沿的速度。我们的研究人员与模型携手并进,更快地提升能力,同时同步加强我们的防护措施。
我们采取审慎的发布方式,并积极参与美国政府自愿性的发布前模型测试流程。从本周开始,我们将向部分网络防御者提供 Carbon,并通过我们的 [Fairwind Program](https://deepmind.google/fairwind-program/) 逐步向更多可信合作伙伴开放访问。我们将继续收集反馈并迭代防护措施,随后尽快通过我们的产品界面向开发者、企业和消费者提供 Carbon。
Gemini 4 Carbon 将以与 Argon 相同的 introductory price 发布 [1](https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-carbon/?utm_source=deepmind.google&utm_medium=referral&utm_campaign=gdm&utm_content=#footnote-1) ,即每百万输入 token 2 美元、每百万输出 token 10 美元,缓存输入 token 按输入 token 价格的 95% 折扣计价。
## 提升编码与推理能力,应对高难度长时程任务
Carbon 旨在应对更困难、长时程的工程问题,专为持续性的智能体工作流而构建。在内部,我们的团队已看到 Carbon 连续运行数天,在遇到死胡同时仍能坚持推进,处理复杂的多步骤工程任务,例如在大型代码库和底层系统中对细微缺陷进行根因定位和修补。
基于用户反馈,我们专注于提升模型在多个领域的表现,包括编码、智能体和科学任务,以及全栈 Web 开发和多模态理解。随着 Web 开发中输出和产物的质量提升,Carbon 跃升 +89 elo 分,以第 4 名(1769 分)登上 [WebDev Arena](https://arena.ai/leaderboard/code/webdev)。
## 最先进的网络安全性能,助力构建安全系统
Gemini 4 Carbon 在网络安全能力上实现重大飞跃。它在网络安全防御全生命周期——漏洞检测、验证和修复——均达到最先进水平。
我们的团队已经在网络防御领域看到了显著收益。在内部基准测试中,Carbon 在生成安全代码方面的成功率相比 Argon 提升超过 2 倍。再举一个例子,Chrome 团队报告称,在生成高质量补丁时,Carbon 的表现比另一家实验室的大型前沿模型好 10 倍以上。我们领先的云安全平台 Wiz 也观察到,Carbon 在网络渗透测试基准上处于领先地位,而这是 [Wiz 的 Scan for Good](https://www.wiz.io/blog/scan-for-good-critical-ai-exposures) 计划的一项核心能力。
Carbon 在关键的外部基准测试中表现出色(评估时未启用防护措施):
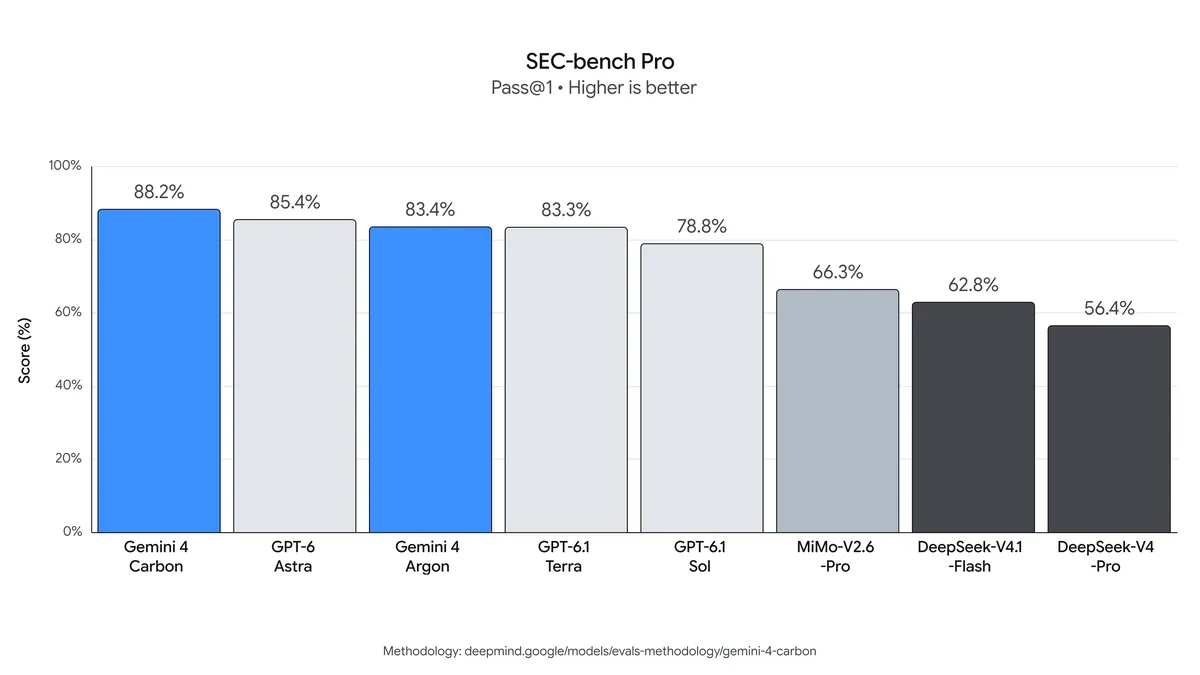
- **发现真实漏洞:** 网络安全防御的核心是发现真实漏洞。Carbon 在 [SEC-bench Pro](https://sec-bench.github.io/) 上达到了最先进的 88.2%,能够自主发现深藏于真实世界软件中的复杂缺陷。
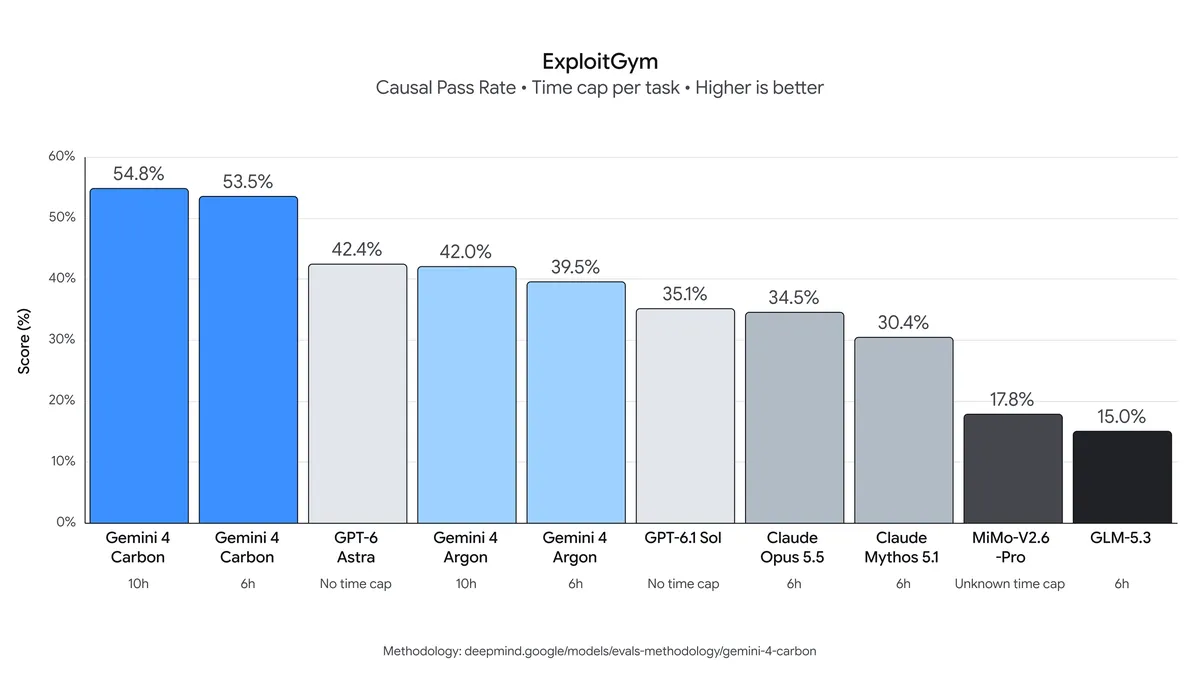
- **通过利用验证风险:** 为了确定哪些漏洞应优先修复或是否需要修复,网络防御者越来越依赖模型来检查哪些漏洞可被利用。Carbon 在流行的利用基准 [ExploitGym](https://github.com/sunblaze-ucb/exploitgym) 上创下新的最先进水平(54.8%)。
- **从根源修复:** 最终,在识别出漏洞之后,修复根本原因是网络安全防御生命周期中的关键一步。Carbon 在 Collinear 的 [CWE-bench](https://cwe-bench.com/#leaderboard) 上达到 71.0%,可将已验证的发现直接转化为可用的代码修复。
## 推进前沿模型的安全与保障
Gemini 4 Carbon 建立在与 Argon 相同的多层安全与保障体系之上——结合了模型训练、实时滥用防御、提示注入韧性和思维链监控。特别是在模型对齐方面,我们借助 Argon 取得了重大进展,并在我们的[安全与保障报告](https://storage.googleapis.com/deepmind-media/gemini/gemini_4_safety_report.pdf)中报告了其以对齐方式行事的倾向。借助 Carbon,我们挑战自己在对齐方面更进一步,并训练模型以正确方式响应复杂或高压任务。
- **减少捷径和漏洞利用:** 借助 Carbon,我们进一步减少了训练中的捷径尝试,同时确保高质量的编码性能。Carbon 将 Terminal-Bench 4.0 上的成功作弊降至 0.0%,作弊尝试降至 0.4%——同时整体准确率还有所提升。在与我们内部团队合作的实时编码环境中,我们观察到高严重性对齐警报下降了近 80%。
- **更高的透明度和诚实性:** 在我们的内部测试中,Carbon 将无依据声明相比 Argon 减少了约 2 倍。它会将方法学上的注意事项直接写入交付成果,或在暂缓操作时明确列出仍需完成的事项,而不是捏造或围绕缺失证据含糊其辞。
- **在模糊情况下改善与用户的协作:** Carbon 不会猜测或强行推进某条路径,而是先检索相关来源并向用户呈现差异,然后再采取行动——因此,用户应当会体验到与 Carbon 更好的协作体验。
- **贯彻到底而不越界:** Carbon 同时将越界行为减少了 26%,将服务不足减少了 29%,从而能够更可靠地端到端执行多步骤计划,同时尊重项目约束并严格保持在范围内。
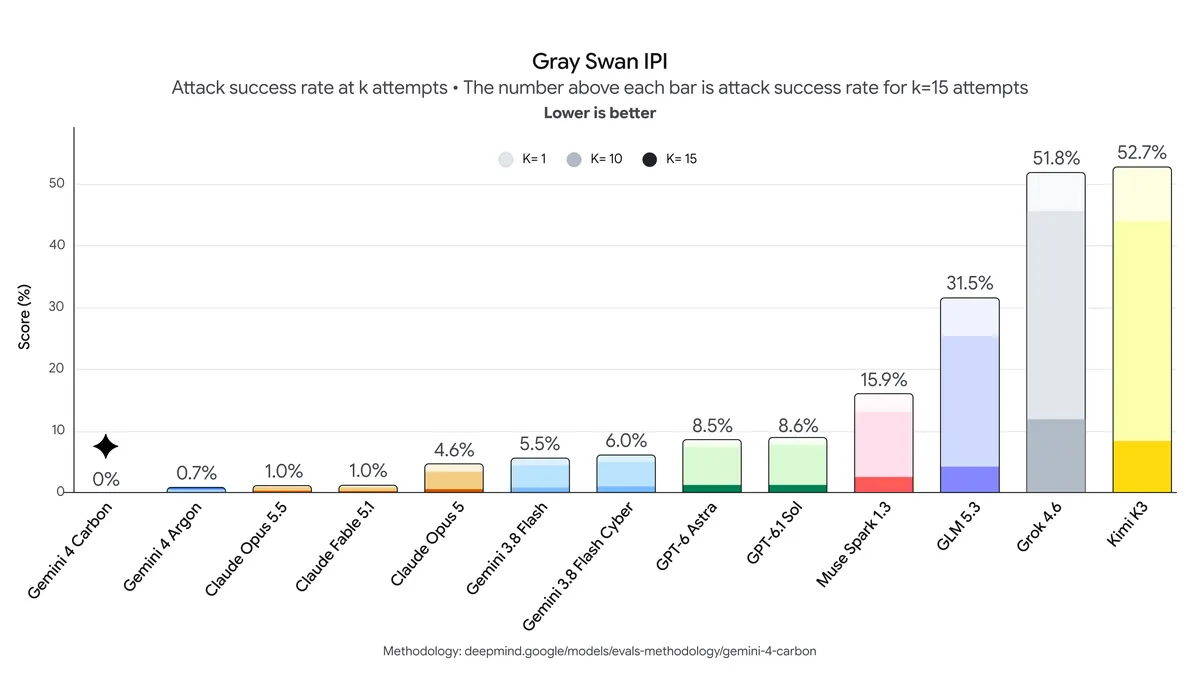
- **抵御提示注入:**此前 Argon 以仅 0.7% 的攻击成功率在 Gray Swan 的间接提示注入(IPI)基准测试中领先,而 Carbon 达到了 0.0%——抵御了每一次评估中的攻击尝试。
## 即将面向开发者、企业和消费者推出
要推动前沿向前发展,就需要快速行动,同时在部署上保持审慎。借助 Gemini 4 Carbon,我们的目标是在软件工程和网络安全防御领域实现有意义的飞跃,同时不牺牲安全性或可靠性。我们迫切希望看到首批网络安全防御者如何使用这一模型,并期待很快将 Carbon 带给开发者、企业和消费者。
## 正文 · 原文
Oct 28, 2026
|
Gemini 4 Carbon is our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
* * *
* * *

Your browser does not support the audio element.
Listen to article
\[\[duration\]\] minutes
This content is generated by Google AI. Generative AI is experimental
Today, we’re announcing the next frontier model: Gemini 4 Carbon, our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
Carbon ranks #1 on the recently updated v5.0 of [Artificial Analysis Intelligence Index](https://artificialanalysis.ai/evaluations/artificial-analysis-intelligence-index) at 59. It shows significant gains across coding and agentic tasks as well as across key capabilities critical for cybersecurity defense, landing a firm lead in SEC-bench Pro (88.2%) for finding vulnerabilities, ExploitGym (54.8%) for exploitation, and CWE-bench (71.0%) for patching. On internal benchmarks, Carbon drives a strong uplift in generating secure code, and in live coding environments with our own teams it shows reduced misalignment and fabrication rates.
Building on [Gemini 4 Argon](https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-argon/), which was launched two weeks ago, Carbon illustrates the pace at which we’re pushing the frontier forward. Our researchers and models are working hand in hand to advance capabilities faster, while strengthening our safeguards in tandem.
We're taking a deliberate approach to rollout and are actively engaged in the U.S. government’s voluntary process for pre-release model testing. Starting this week, we will make Carbon available to a subset of cyber defenders and will gradually phase access to additional trusted partners through our [Fairwind Program](https://deepmind.google/fairwind-program/). We’re continuing to gather feedback and iterate on guardrails before making Carbon available to developers, businesses, and consumers via our product surfaces as soon as possible.
Gemini 4 Carbon will launch at the same introductory price [1](https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-carbon/?utm_source=deepmind.google&utm_medium=referral&utm_campaign=gdm&utm_content=#footnote-1) as Argon at $2 per million input tokens and $10 per million output tokens, with cached input tokens priced at 95% off input token price.
## Improving coding and reasoning for challenging, long-horizon tasks
Designed to take on much harder, long-horizon engineering problems, Carbon is built for sustained agentic workflows. Internally, our teams have seen Carbon run for days to persist through dead ends to tackle complex, multi-step engineering tasks like root-causing and patching subtle bugs across large codebases and low-level systems.
Building on user feedback, we focused on improving model performance across a variety of domains, including coding, agentic, and scientific tasks, as well as full-stack web development and multimodal understanding. With improved quality of output and artifacts in web development, Carbon jumps +89 elo points to land at #4 (1769) on [WebDev Arena](https://arena.ai/leaderboard/code/webdev).

## State-of-the-art cybersecurity performance to help build secure systems
Gemini 4 Carbon delivers a significant leap in cybersecurity capabilities. It achieves state-of-the-art performance across the cybersecurity defense lifecycle — vulnerability detection, validation, and remediation.
Our teams are already seeing strong gains in cyberdefense. On internal benchmarks, Carbon achieves more than 2x uplift in success rate for generating secure code over Argon. As another example, the Chrome team has reported that Carbon performed more than 10X better than another lab's large frontier model when generating high quality patches. Wiz, our leading Cloud security platform, also observes Carbon leading on benchmarks for web penetration testing, a core capability for [Wiz's Scan for Good](https://www.wiz.io/blog/scan-for-good-critical-ai-exposures) initiative.
Carbon excels across key external benchmarks (evaluated without guardrails):
- **Finding real vulnerabilities:** Core to cybersecurity defense is finding real vulnerabilities. Carbon achieves a state-of-the-art 88.2% on [SEC-bench Pro](https://sec-bench.github.io/), autonomously uncovering complex flaws buried in real-world software.

- **Validating risk through exploitation:** To prioritize which vulnerabilities to remediate first or remediate at all, cyber defenders increasingly rely on models to check which vulnerabilities are exploitable. Carbon sets a new state-of-the-art on the popular exploitation benchmark [ExploitGym](https://github.com/sunblaze-ucb/exploitgym) (54.8%).

- **Patching at the root cause:** Ultimately after identifying the vulnerabilities, fixing the root cause is a critical step in the cybersecurity defense lifecycle. Carbon reaches 71.0% on Collinear’s [CWE-bench](https://cwe-bench.com/#leaderboard), turning validated findings directly into working code fixes.

## Advancing frontier model safety & security
Gemini 4 Carbon builds on the same multi-layered safety and security stack of Argon — combining model training, real-time misuse defenses, prompt-injection resilience, and chain-of-thought monitoring. In particular, we made significant strides in model alignment with Argon, and reported its propensities to behave in an aligned way in our [Safety and Security report](https://storage.googleapis.com/deepmind-media/gemini/gemini_4_safety_report.pdf). With Carbon, we challenged ourselves to go a step further on alignment, and trained the model to respond to complex or high-pressure tasks in the right way.
- **Reducing shortcuts and loophole exploitation:** With Carbon, we further mitigated shortcut attempts in training while ensuring high-quality coding performance. Carbon reduced successful cheating on Terminal-Bench 4.0 to 0.0%, with attempts to cheat dropping to 0.4% — all while improving overall accuracy. In live coding environments with our internal teams, we observed that high-severity misalignment alerts dropped by almost 80%.
- **Greater transparency and honesty:** In our internal testing, Carbon cuts unsupported claims by approximately 2x over Argon. It puts methodological caveats directly into the deliverable or withholds blocked actions with a clear list of what remains required, rather than fabricating or hedging around missing evidence.
- **Improved collaboration with the user in the face of ambiguity:** Rather than guessing or forcing a path forward, Carbon retrieves the relevant sources and surfaces discrepancies to the user before acting — as a result, users should observe a much better collaborative experience with Carbon.
- **Following through without overstepping:** Carbon simultaneously reduced overreach by 26% and under-service by 29% resulting in much more reliable execution of multi-step plans end-to-end while respecting project constraints and staying strictly within scope.
- **Resisting prompt injection:** While Argon previously led the Gray Swan’s Indirect Prompt Injection (IPI) Benchmark in prompt injection resistance with a very low 0.7% attack success rate, Carbon achieves 0.0% — resisting every evaluated attack attempt.

## Coming soon to developers, businesses, and consumers
Pushing the frontier forward requires moving fast while remaining deliberate about deployment. With Gemini 4 Carbon, our goal is to deliver meaningful leaps in software engineering and cybersecurity defense without compromising on safety or reliability. We’re eager to see how the initial cohort of cyber defenders use this model and we look forward to bringing Carbon to developers, businesses, and consumers soon.