# Anthropic 自研版本控制系统 Scion,五个月完成 monorepo 从 git 迁移
> 原标题:Redesigning source control at Anthropic
- 来源:Anthropic:Engineering
- 发布时间:2026-10-13T00:00:00.000Z
- AIHOT:https://aihot.news/items/fpyjwv3o9zwxc9zs7j1bmnw8i
- 原文:https://www.anthropic.com/engineering/redesigning-source-control
## 摘要
Anthropic 发布工程复盘,因 Claude 使日均合并代码量从 2026 年 5 月约 2,500 增至 9 月超 30,000,五个月内自研版本控制系统 Scion 并完全替代 git,同时推出代码评审工具 Antique。
## 推荐理由
Anthropic 自建版本控制系统 Scion 的完整复盘,给出面向智能体规模负载的设计原则、架构细节和实测收益,可迁移到其他大规模仓库场景。
## 正文 · 中文译文
在 Anthropic,编码不再是构建系统或进行研究的瓶颈。Claude 能够自主地在研究循环中迭代、对复杂程序进行微优化,并以我们前所未见的速度和规模从零开始构建新服务。如今的瓶颈,是为人类规模而构建的所有开发者基础设施:源代码控制、构建和 CI。
2026 年 5 月,Anthropic 平均每天合并约 2,500 个代码变更;截至 9 月,我们每天合并超过 30,000 个。我们预计这一增长速度短期内不会放缓;合并代码的潜在需求几乎是无限的,我们每消除一个瓶颈,都会立即带来代码产出量的进一步增长。
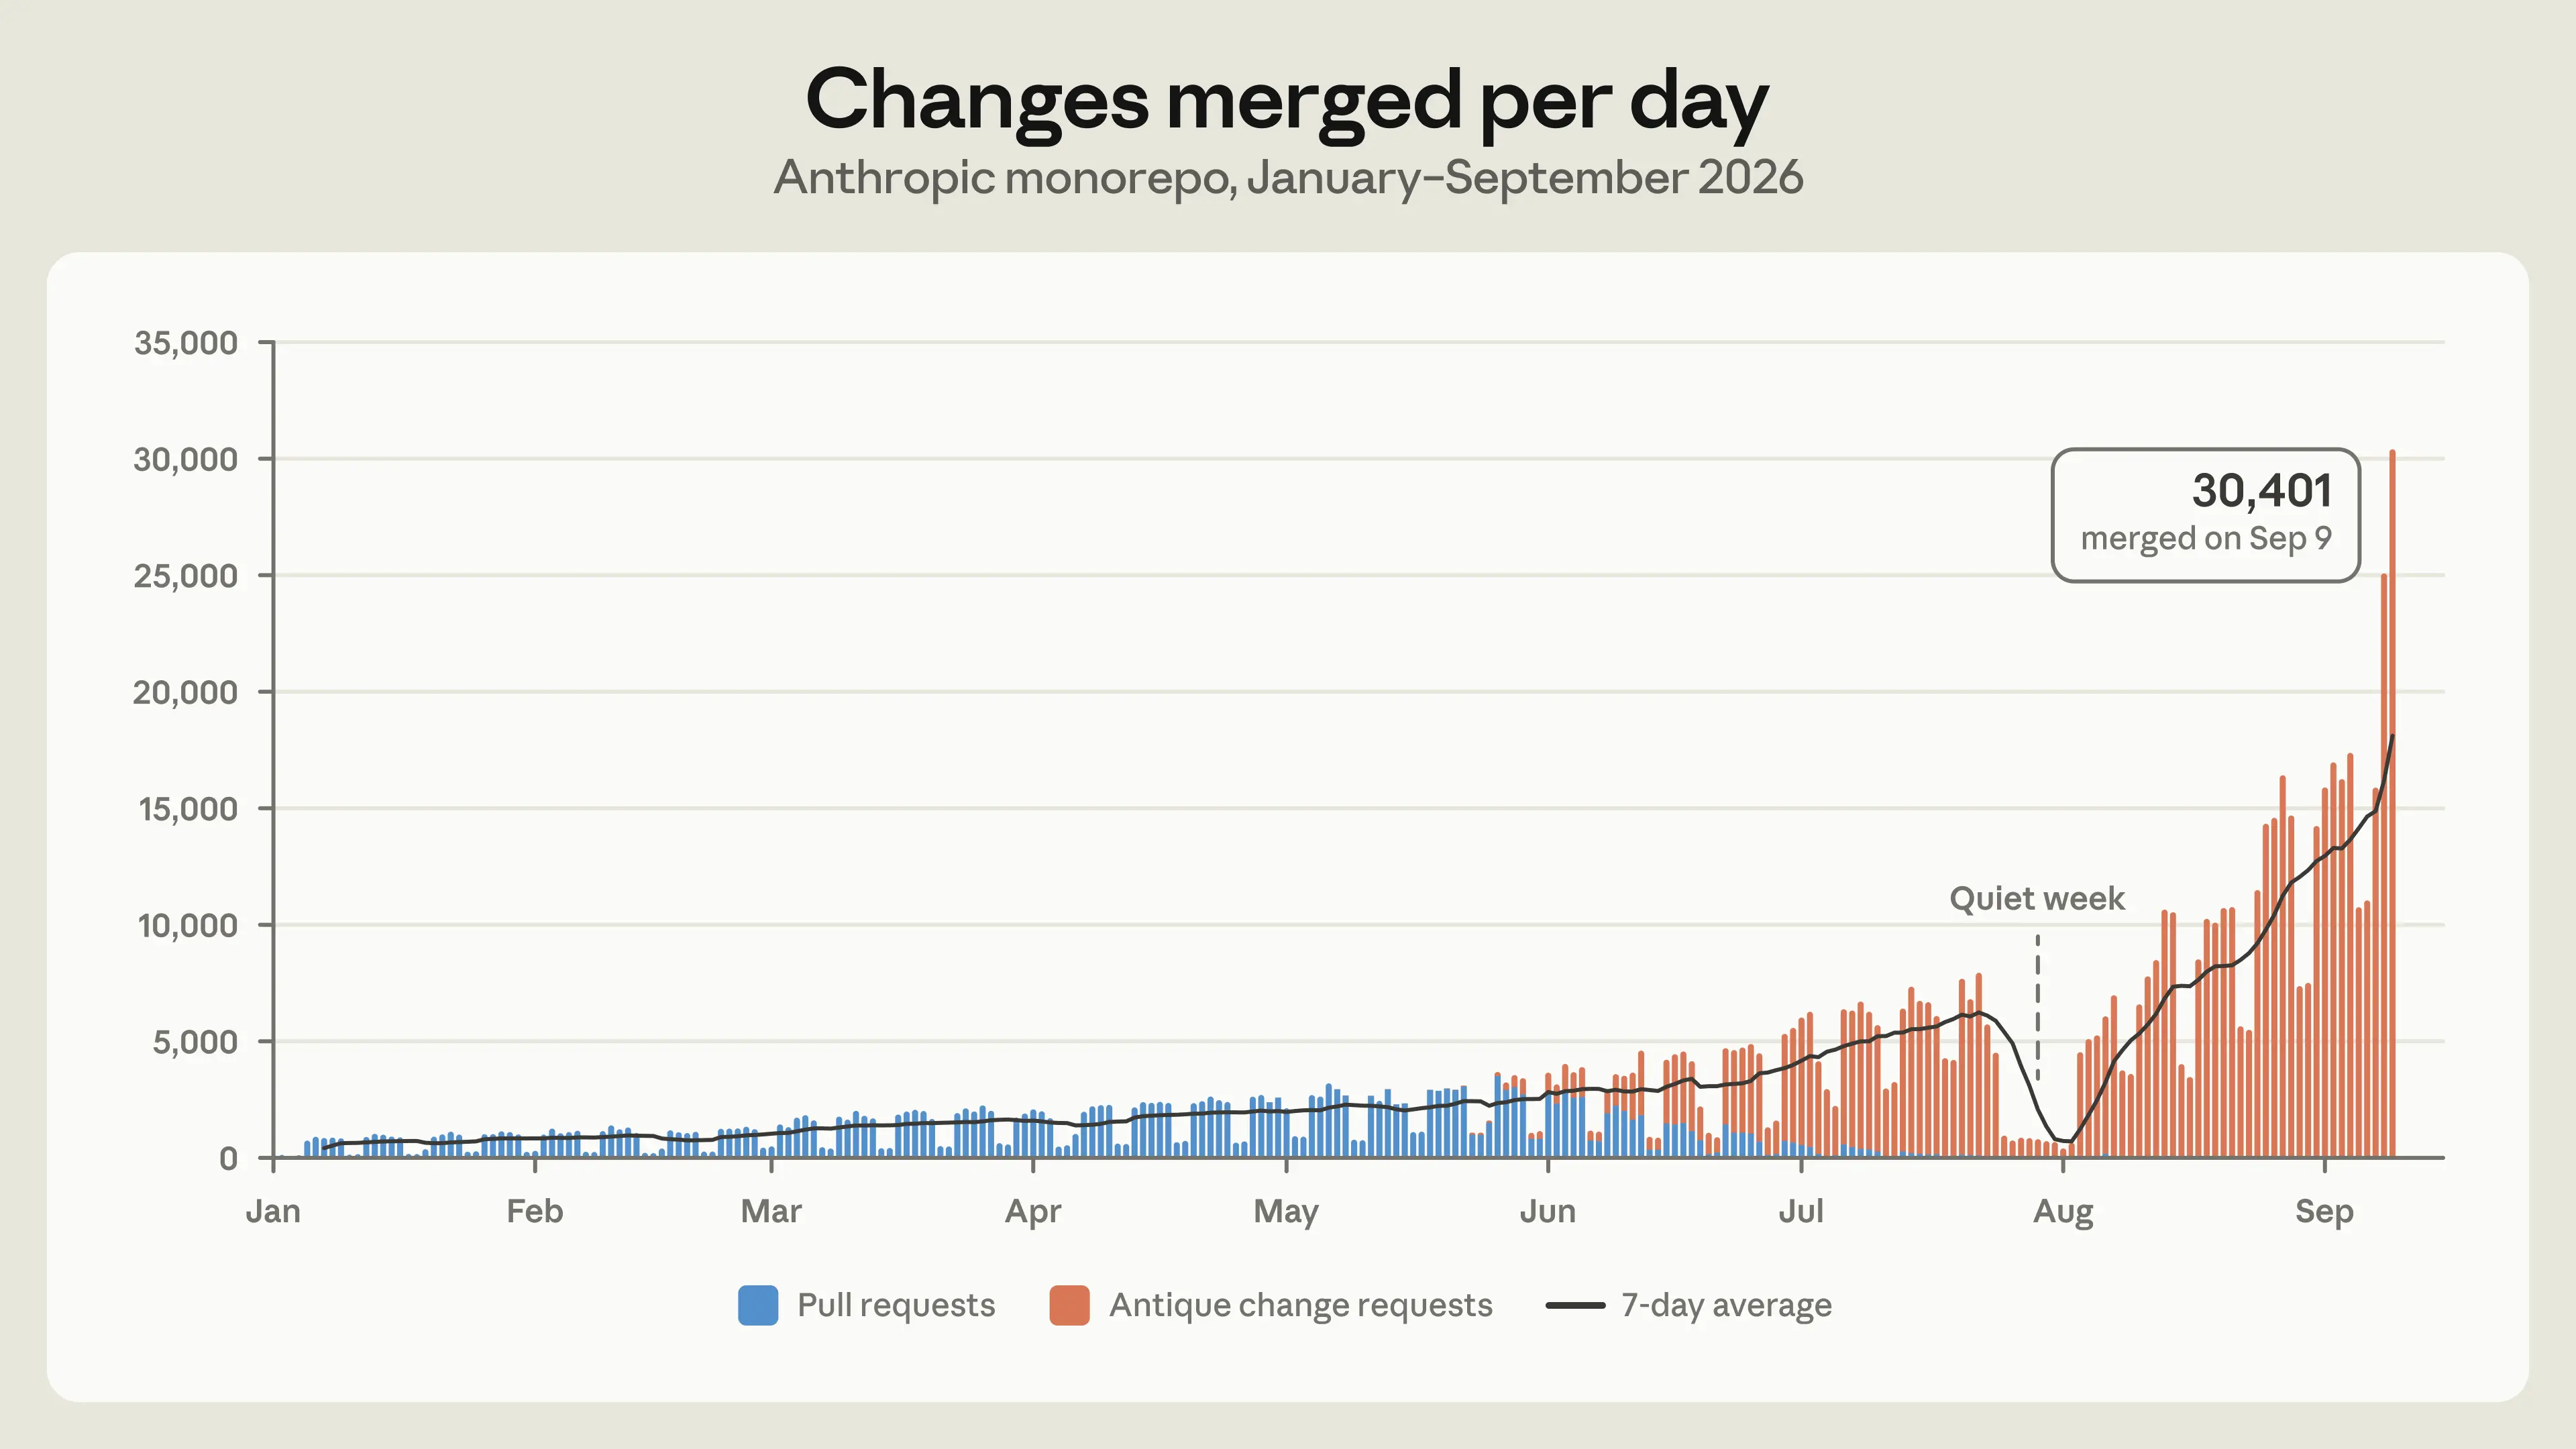
2026 年 1 月至 9 月,每天合并到我们 monorepo 的变更数。
为了支撑这一增长,我们构建了 Scion,一个内部版本控制系统,并在五个月内将我们的 monorepo 从 git 完全迁移过来。我们还在同一时期构建并上线了代码审查界面(名为 Antique)、代码搜索、丰富的源代码控制 IAM 系统、管理并落地大量已审查代码的新方法等等。在这篇文章中,我们将重点介绍我们具体是如何构建 Scion 的。这是一个有趣的案例研究:Claude 编写代码的能力既是让我们陷入这种处境的原因,_也是_我们能够快速构建高质量、可扩展系统来应对它的原因。
## 扩展我们的 monorepo
在探讨我们构建了什么之前,我们应该承认我们的工作负载有多么不寻常。不出所料,Anthropic 使用 Claude 编写软件的程度远超几乎所有其他公司,因此我们往往是第一个看到为人类规模构建的工具开始吃紧的地方。源代码控制只是其中一个例子。虽然我们预计近期内不会有太多组织遇到这些问题,但我们怀疑用不了多久,其他使用 AI 编码工具的人也会经历这些同样的压力点,这就是为什么我们想分享我们构建了什么以及学到了什么。
Git 是一个去中心化系统:每个克隆都是一个完整、自包含的仓库,可以计算差异、读取历史和 blame,并在完全离线的情况下检出任何修订版本。对于绝大多数仓库来说,这是正确的设计,也是 git 成为标准的重要原因之一。
随着我们的 monorepo 增长,它越来越不符合这一设计空间。仅我们主分支的历史就接近 100 GB,而_压缩后_的工作副本超过 25 GB。我们每天为 CI 执行约 2,500 万次代码检出,这还不算开发者环境、代理沙箱和研究任务。如果天真地获取,那将是每天超过 600 PB 的 git 流量。
Git 提供了处理仓库一部分的工具,例如浅克隆、稀疏检出和 promisor 远程。除此之外,还有针对大型 monorepo 的标准变通方案,例如内部 git 镜像和保存在 blob 存储中的仓库快照(种子)。这些我们都用过——在高峰期,我们运营了数百个内部 git 镜像来应对负载。这为我们争取了时间,但随着合并率的提高,它们变得越来越难以运营。种子在刷新之间离 main 的顶端越来越远,要让依赖历史(如 diff 和 blame)的操作在部分克隆上正常工作,需要越来越多的细心维护。
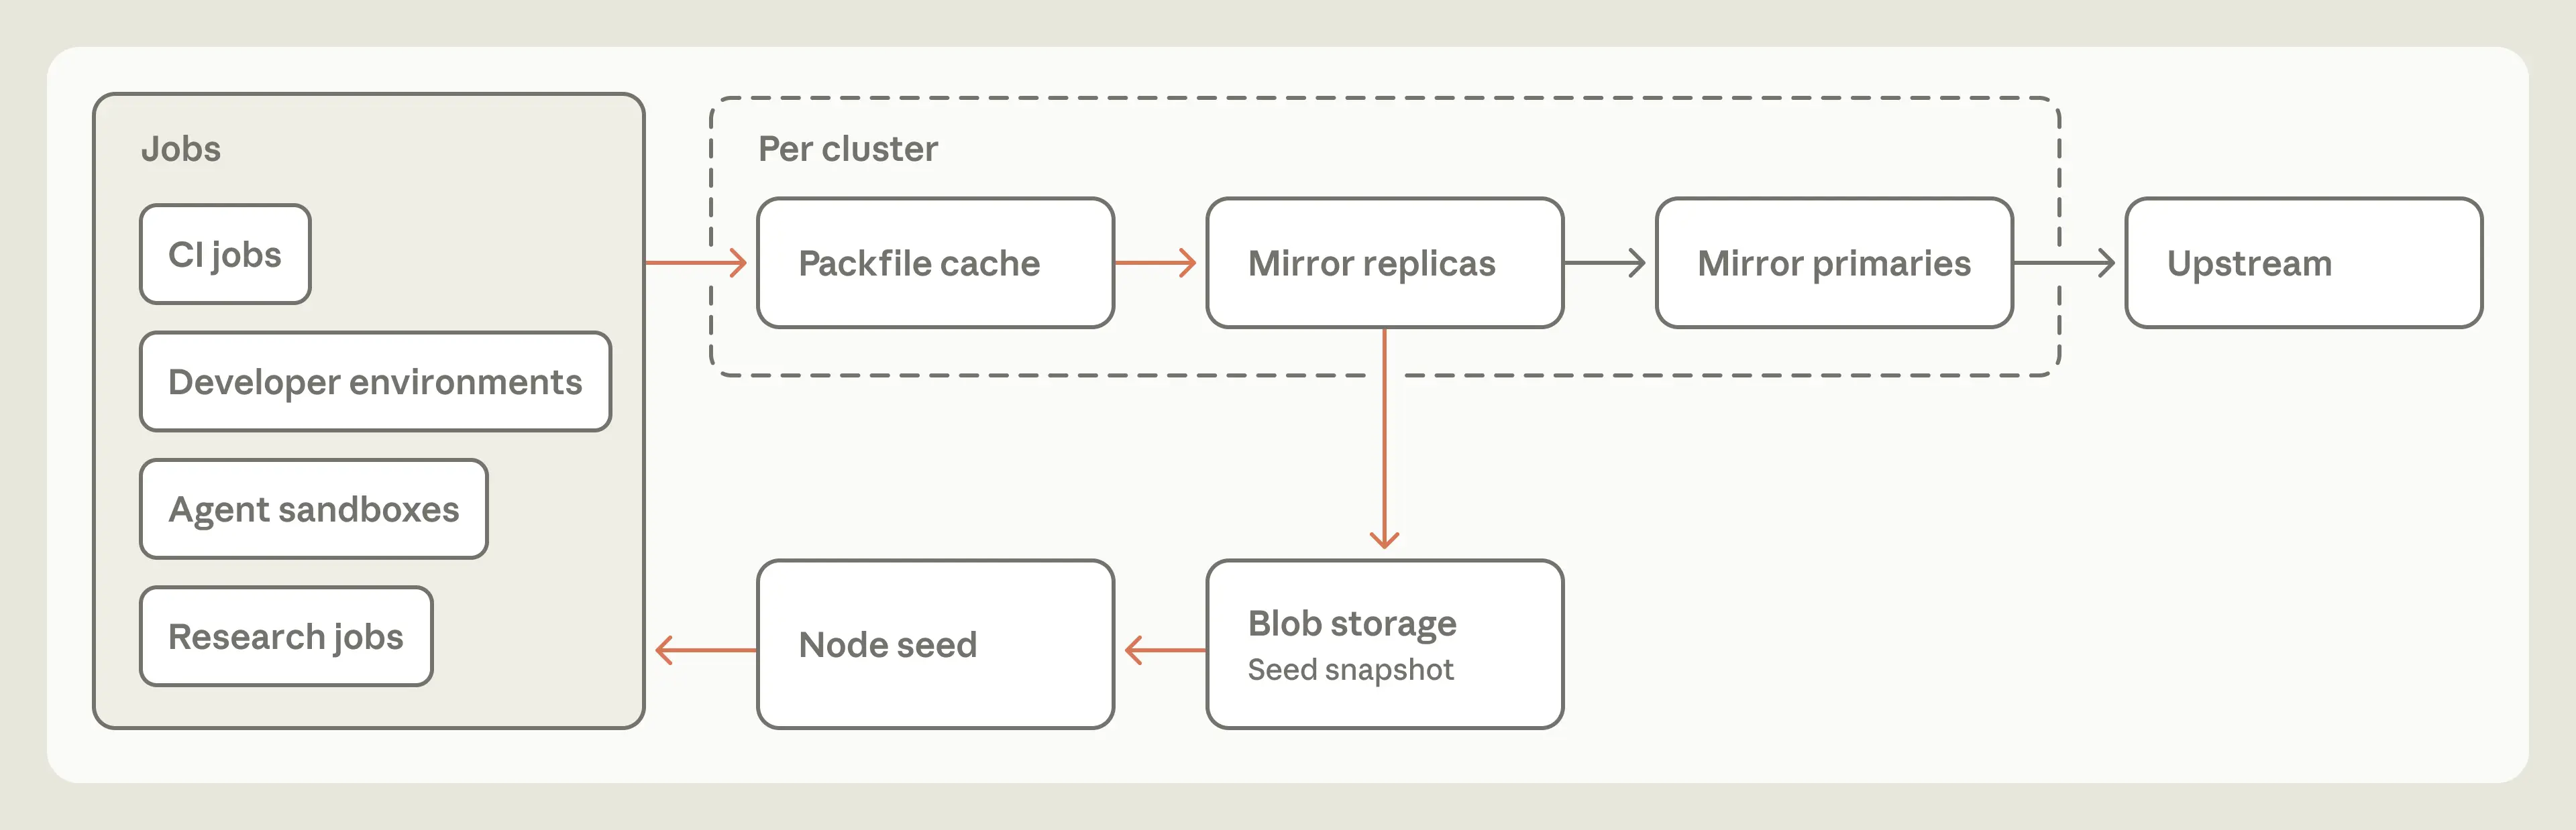
扩展 git 检出的典型设置。
退一步看,我们注意到,和大多数公司一样,我们把 git 当作一个集中式系统来使用,只有一份权威副本,但我们的客户端几乎都是按定义在线的 agent 和作业。那些让 git 在分布式、离线工作中表现出色的特性,反而随着仓库增长而严重削弱了我们的扩展能力。于是我们问自己:如果从一开始就考虑到 agent 始终在线这一事实来设计源代码控制,它会是什么样子?
## 面向 agent 规模的源代码控制原则
在 agentic 编码中,许多关于软件开发方式的常见假设正在演变。在构建 Scion 时,我们拥抱了这些变化,这让我们能够在几个核心原则上采取与 git 根本不同的方法。面向超大型 monorepo 的源代码控制已有先例,尤其是 Google 的 [Piper](https://en.wikipedia.org/wiki/Piper_\(source_control_system\)) 和 Meta 的 [Sapling](https://sapling-scm.com/),因此我们能够借鉴它们来之不易的经验来构建 Scion。我们的原则是:
**客户端始终在线。**Git 假设客户端离线工作,并且需要仓库的完整副本。由于我们的客户端几乎都是 agent 和作业,我们围绕一个始终可达的服务器来设计 Scion 的客户端和协议,让客户端在需要时获取数据。
**客户端-服务器不对称。**在 git 中,每个客户端都能成为功能完备的服务器。在 Scion 中,服务器负责回答关于文件历史和 blame 的问题、创建提交、执行合并和 rebase 等。客户端维护一个有界的本地对象缓存,将工作副本文件布局到磁盘上,监控文件系统变化,并为用户提供一种符合人体工程学的方式与服务器交互。它自身能计算的东西很少,但作为交换,它在本地需要的数据也少得多。
**一个全面的源代码控制服务可以驱动许多新颖的应用。**使用 git 时,一个需要对仓库提问的 CI 作业或工具——比如谁最后修改了某一行,或者两个提交之间有何关系——必须维护仓库的本地副本,或者寄希望于厂商特定的 API 能提供答案。使用 Scion 时,客户端使用的所有源代码控制查询也都通过 API 暴露出来,因此在许多情况下,作业根本不需要本地仓库。许多内部工具,比如我们自动化的 bisect 和 revert 流水线,如果没有这种廉价、可编程的源代码控制访问方式,就无法在规模上实用。
**一切都必须能够水平扩展。**在高峰期,我们运行着数百个 git 镜像,这严重消耗了容量,而且一旦仓库超出镜像的磁盘或内存限制,就无法再扩展。在 Scion 中,仓库的数据是分布式的,每个组件都可以独立扩展;任何地方都不存在仓库的完整物化副本,即使在服务器上也没有。不存在 packfile(git 的压缩对象包)的等价物,因此不需要进行仓库维护。
**提交必须廉价、增量且无锁。**在 git 中,你在本地提交,然后推送以分享你的工作。在 Scion 中,每次提交、变基或合并都发生在服务器上,因此无需推送,但每个操作都需要快速完成。创建提交并更新其下游数据结构的成本必须随变更的大小而扩展,而不是随仓库的整体大小,否则服务器将无法跟上。Scion 中的开发生命周期不鼓励使用 ref(指向提交的指针,如分支和标签),除了主 ref 或发布分支,因为每个服务器都必须达成一致的_全局_状态是一个迫在眉睫的扩展问题。
**工作副本是可选的,并且按设计是稀疏的。**因为我们的 monorepo 非常庞大,而且我们每天为 CI 检出代码数千万次,所以我们希望尽可能避免检出。使用 Scion,例如需要提交与其合并基之间差异的 CI 作业,可以向服务器请求它。写入也是如此:许多写入工作负载也可以跳过检出,完全通过 API 运行。Scion 的协议围绕稀疏检出(仅包含客户端请求的目录)和虚拟化检出(按需物化文件)展开,因此当作业确实需要磁盘上的文件时,客户端只需为实际读取的内容付费。
## Scion 如何工作
了解这些原则在构建 Scion 时如何在实际中结合在一起是很有帮助的。这些见解可以应用于其他源代码控制系统,或者更广泛地应用于软件开发生命周期的其他阶段。
### 数据结构
在 Scion 中,工作单元是“变更集”,即预写日志中的一个条目。变更集存储了你在 git 提交中预期的大部分内容。但是,git 提交存储指向树的指针,而变更集存储相对于其第一个父提交发生更改的文件列表,1 以及指向 blob 存储中压缩文件内容的内容寻址指针。变更集在服务器端创建,并立即可在所有地方使用。
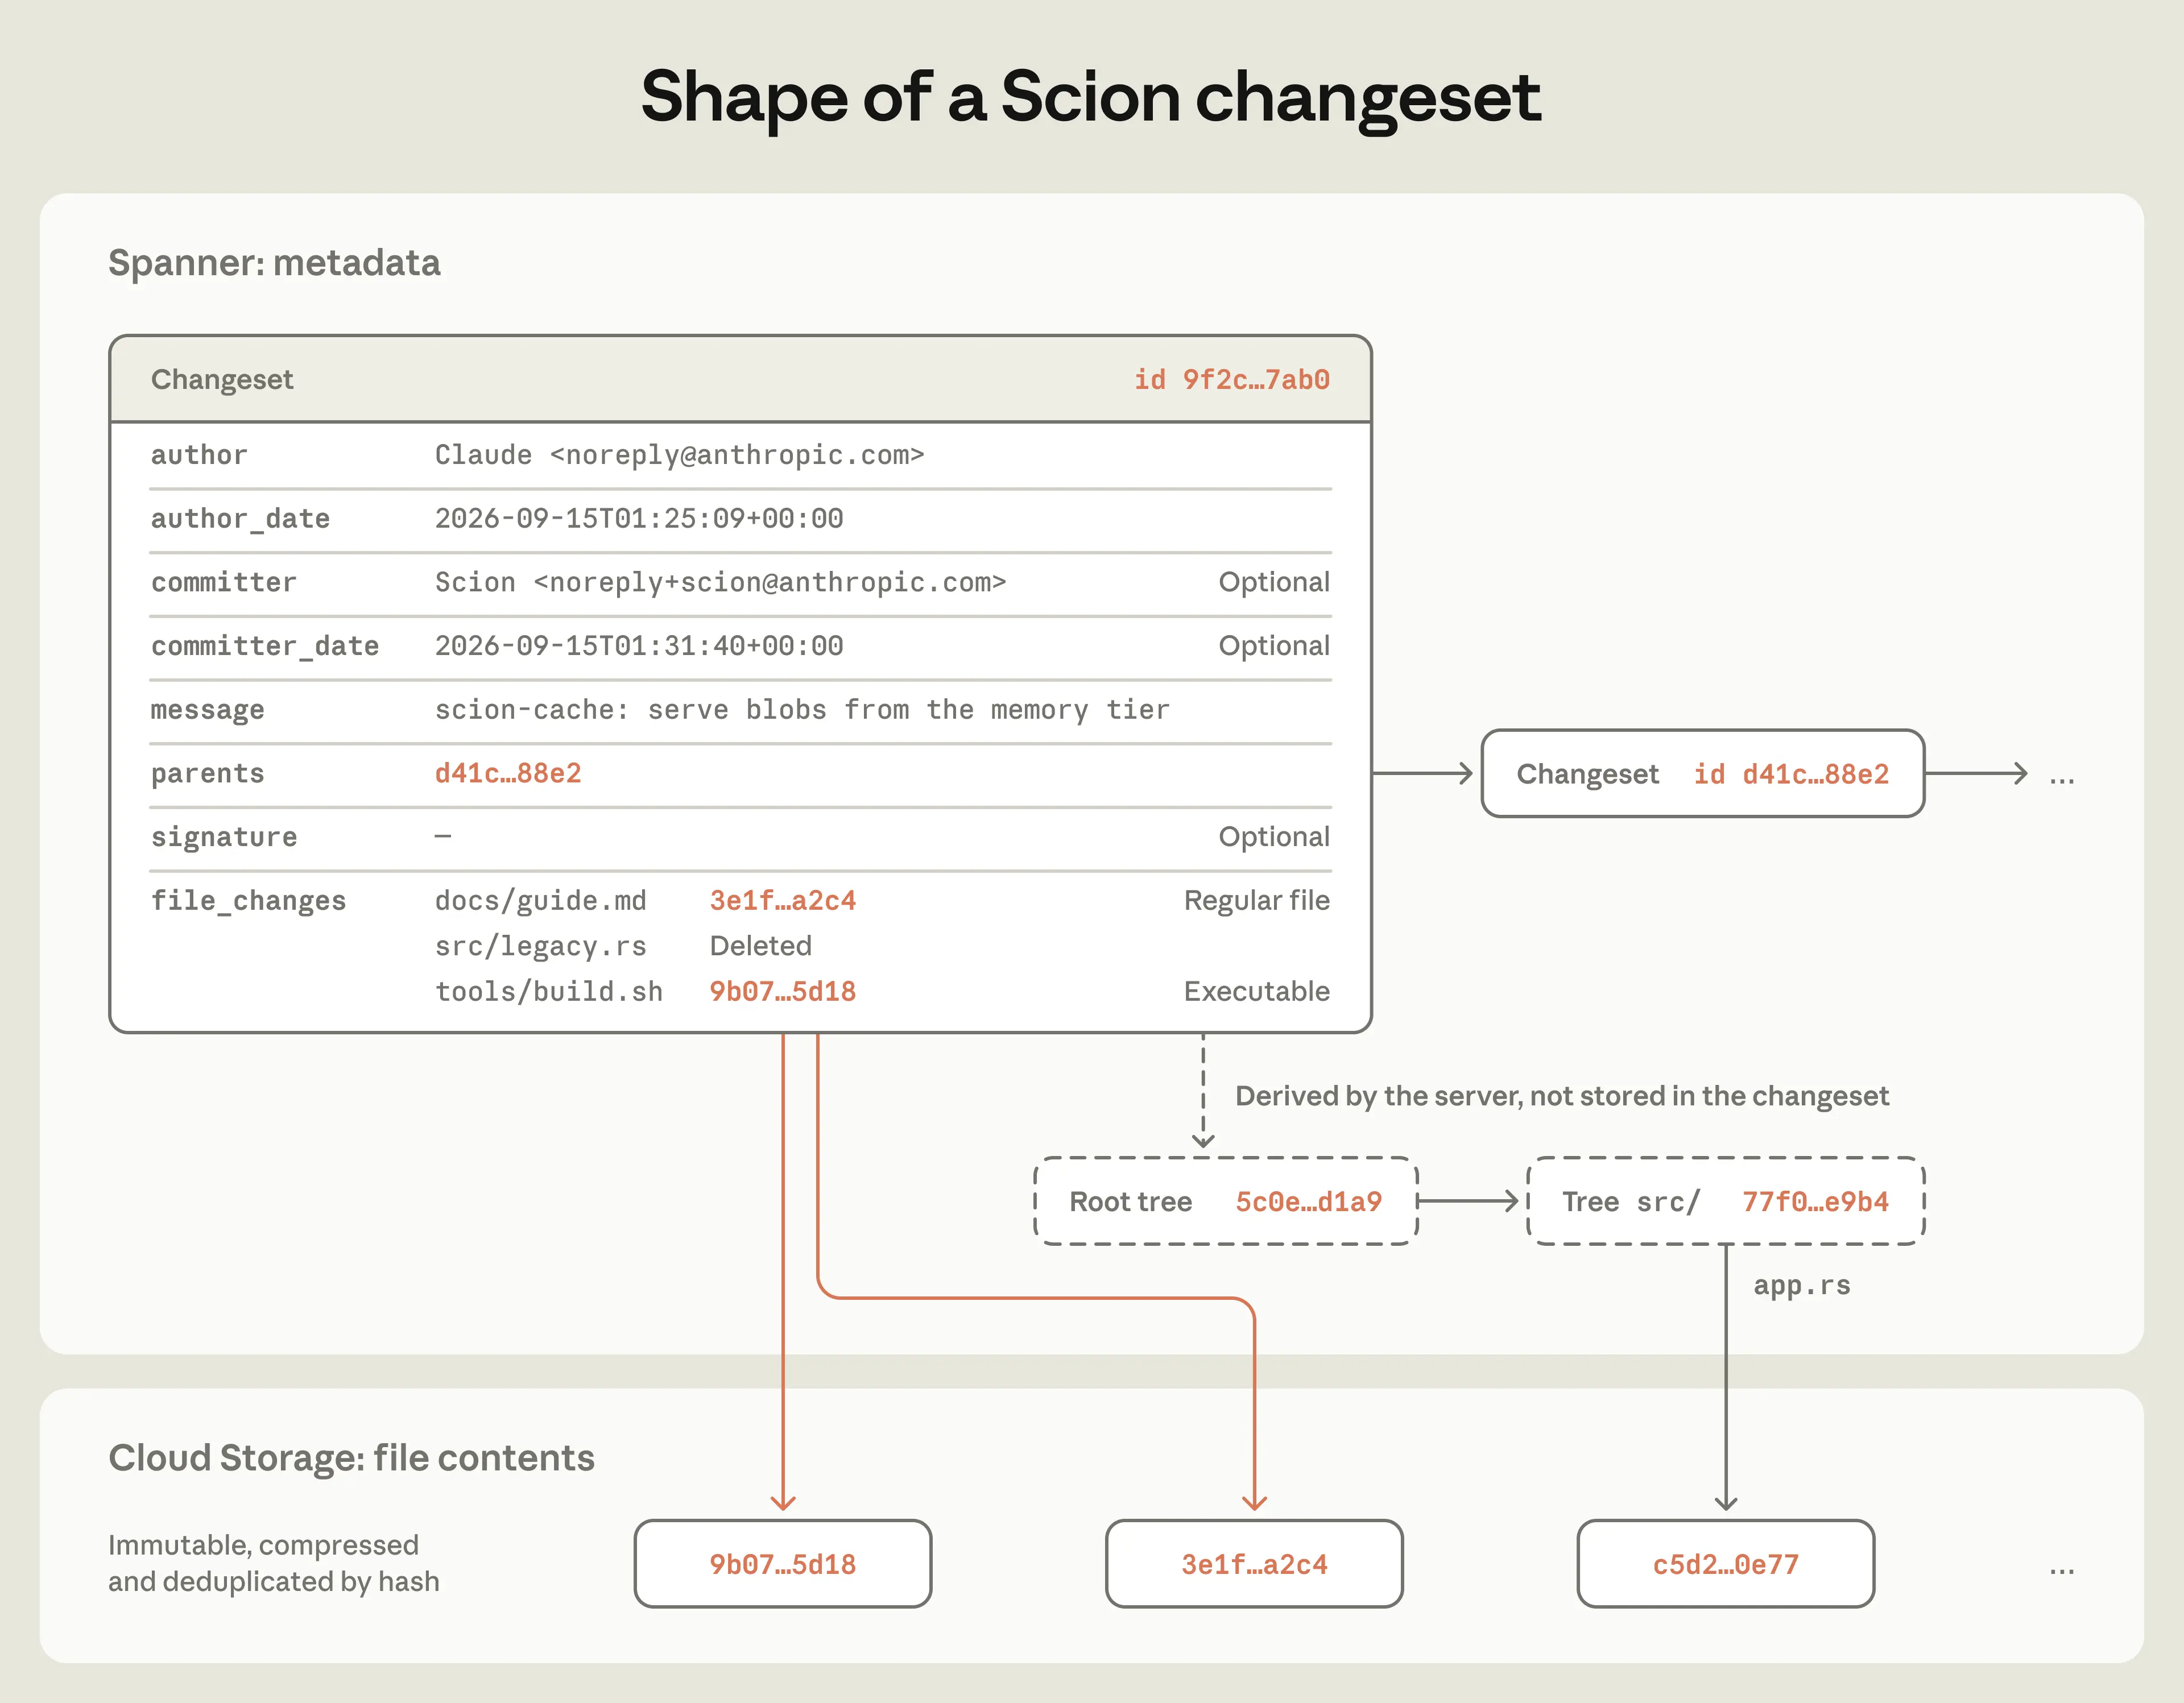
Scion 中变更集的形态。
这种结构使我们能够以非常高的吞吐量接受变更集,因为没有要接受的 packfile,没有锁定或跨服务器协调,也没有要移动的 ref。Scion 在技术上支持 ref,但由于创建和获取提交都不涉及它们,移动一个 ref 是对单个 Spanner 行的比较并交换,与创建变更集分开进行。
变更集只记录已更改的内容,因此仅凭它本身无法快速回答诸如谁最后编辑了一行或哪些提交影响了某个文件等问题。为了回答这些问题,Scion 从变更集构建额外的数据结构,包括用于文件追溯和路径历史的专用结构,以及用于提交图的跳表。我们将所有不直接属于变更集的内容称为“派生数据”,并通过一个通用机制计算所有这些数据。每种派生数据类型都是递归定义的,因此某个变更集的值是根据该变更集的父提交的值计算得出的。
这个机制有三个好处。首先,当新的数据结构能让某些操作更快时,我们可以轻松添加一种新的派生数据类型。其次,对于每种类型,我们可以选择是急切计算还是推迟工作,从而避免物化我们不需要的数据。第三,由于客户端永远看不到这些数据结构的内部细节,我们可以在不改变客户端的情况下对它们进行优化。随着系统的发展,我们已经多次添加了新的派生数据类型,例如用于执行复制检测或基于路径的文件搜索的新索引。
### 扩展 Scion
一小组 Scion 服务器为客户端所需的任何操作提供源代码控制 API,例如获取变更集、计算差异、查找合并基和获取 blob。所有源代码控制数据都是内容寻址的,因此一份数据一旦存储就永远不会改变,任何服务器都可以缓存它而无需与其他服务器核对。因此,这些服务器可以水平扩展,并且几乎不需要协调。它们本质上是大缓存,还可以即时计算派生数据并将结果写回 Spanner。
Scion 的众多消费者不再需要维护自己的本地仓库。获取和维护仓库过去对 CI 作业或需要询问源代码控制问题(特别是关于提交祖先和 blame)的工具来说是一项重大的维护负担。在迁移初期,在我们拥有自己的客户端、仓库格式或协议之前,Scion 只回答这些“元数据”查询。获取文件内容和物化工作副本是数据密集得多的操作,它们需要自己的设计。
Scion 的 scn 客户端在几个重要方面偏离了 git 的获取协议,因此适合高度可扩展的架构,所需的 CPU 比 git 服务器少得多。Scion 的协商不会告诉服务器客户端已经拥有什么;相反,它只对客户端想要的树和 blob 进行操作。从根树开始,客户端检查其本地存储中缺失的树并递归请求它们,然后对 blob 重复该过程。每个请求都是针对一个永不改变的特定对象,因此任何缓存都可以回答它,该架构与传统的分层缓存非常相似。该过程也很高效且可恢复,因为没有单一的几 GB 的 packfile 响应。稀疏甚至虚拟化的检出不需要特殊支持,因为客户端根本不会请求它不想要的树。
在集群中,客户端通过套接字与守护进程 scion-daemon 通信,该守护进程为整个节点存储对象。我们的大多数节点需要访问 monorepo,同一节点上的作业重用大多数相同的对象。每个守护进程从定期刷新的快照开始,然后只与其所在区域的树和 blob 缓存服务器(称为 scion-cache)通信。这些缓存服务器直接从内存中以守护进程将使用的磁盘格式流式传输对象,因此它们不需要花时间计算客户端缺失的对象或执行增量压缩。当缓存缺少某个对象时,它会询问权威的 scion-servers,后者根据需要从 Spanner 或云存储中读取。
scion-daemon、scion-cache 和 scion-server 在该协议下对完全相同的 RPC 作出响应,因此客户端无需了解缓存拓扑。理论上任意一层都可以与任意其他层通信,但我们严格强制分层,以隔离故障域。我们希望避免出现这样的情况:某个区域级 scion-cache 的故障压垮上游的 scion-server,进而拖垮整个系统。
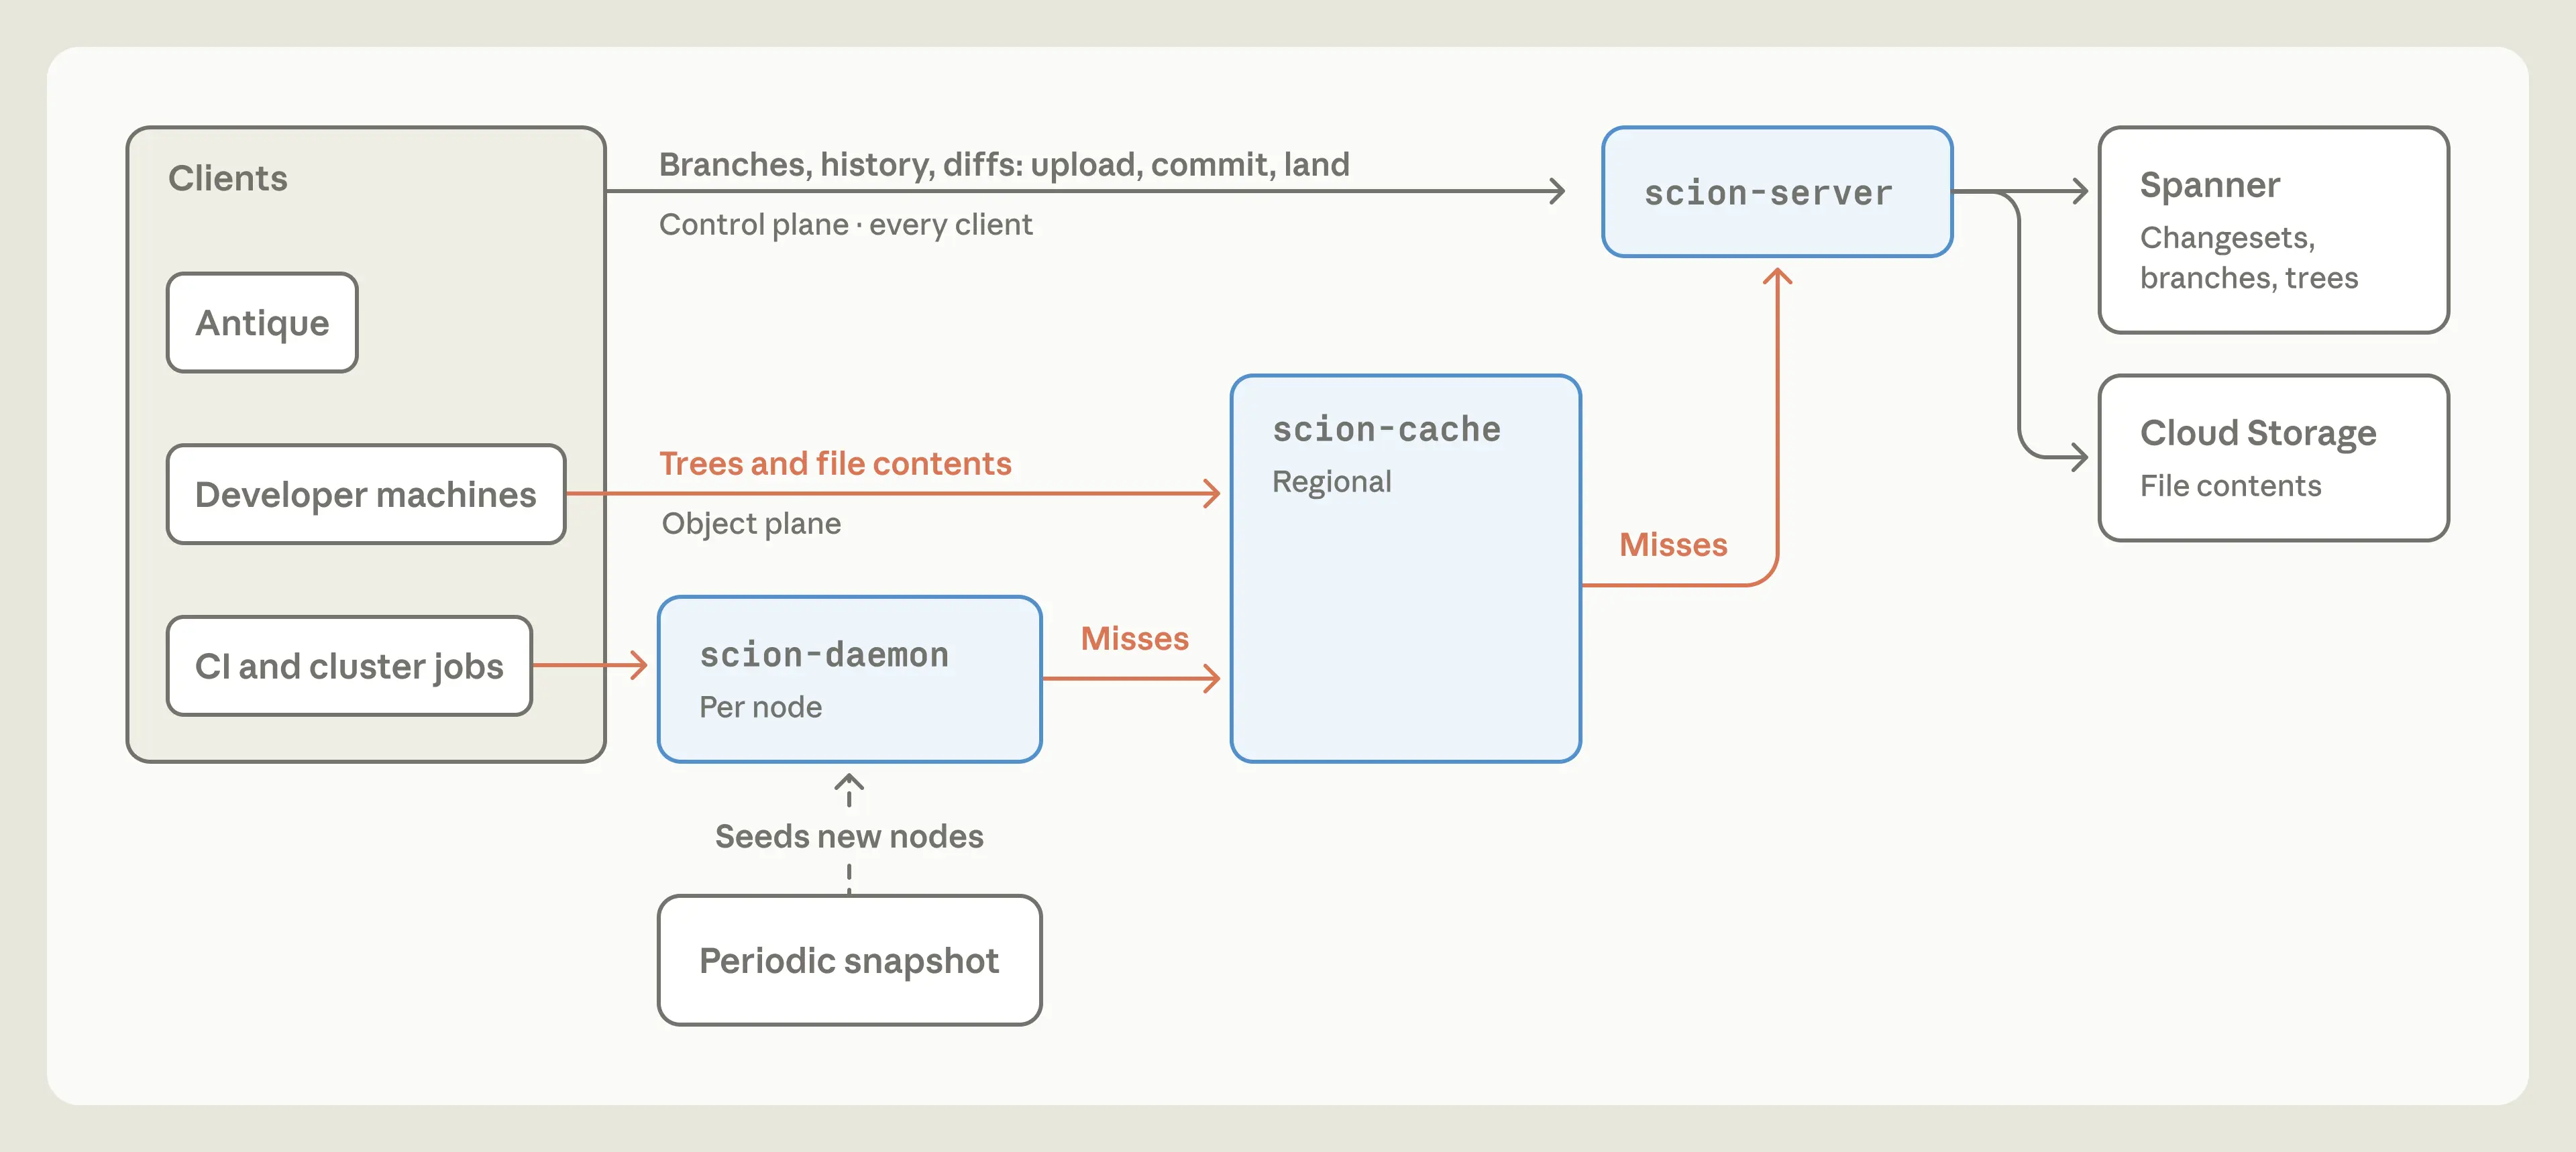
Scion 的检出架构。
该系统的每一层都保持超过 99% 的缓存命中率,且不需要长期存活的状态,因此按需扩容很容易。就 CPU 和内存需求而言,我们的 Scion 基础设施占用现在比之前的 git 镜像基础设施小 200 倍。CI 和研究任务检出代码的速度快了两个数量级(以秒计而非以分钟计),这在整个集群中释放了相当可观的容量;仅 CI 一项就实现了 25% 的 CPU 容量收益。客户端和缓存都不需要执行仓库维护,这简化了我们任务的生命周期管理。
## 构建 Scion 的经验教训
我们开始构建 Scion 的时间,大约与 [Claude Mythos Preview](https://www.anthropic.com/claude/mythos) 和 [Claude Tag](https://www.anthropic.com/news/introducing-claude-tag) 在内部可用相同。这两个版本的发布既放大了对 Scion 的需求 ,也显著加快了我们构建它的速度。
这里有一个特别引人注目的例子。今年早些时候,我们基本上是以手写方式把 git-to-Scion 摄取流水线的第一版做成了一个原型。我们本以为它不错——直到我们拿到了 Claude Mythos Preview 的一份早期内部快照。我们让它重写整个东西,在没有任何进一步指示的情况下,它产出的版本内存占用减少了 20 倍、速度快了 4 倍,同时保留了围绕摄取顺序和数据结构的全部隐式不变量。
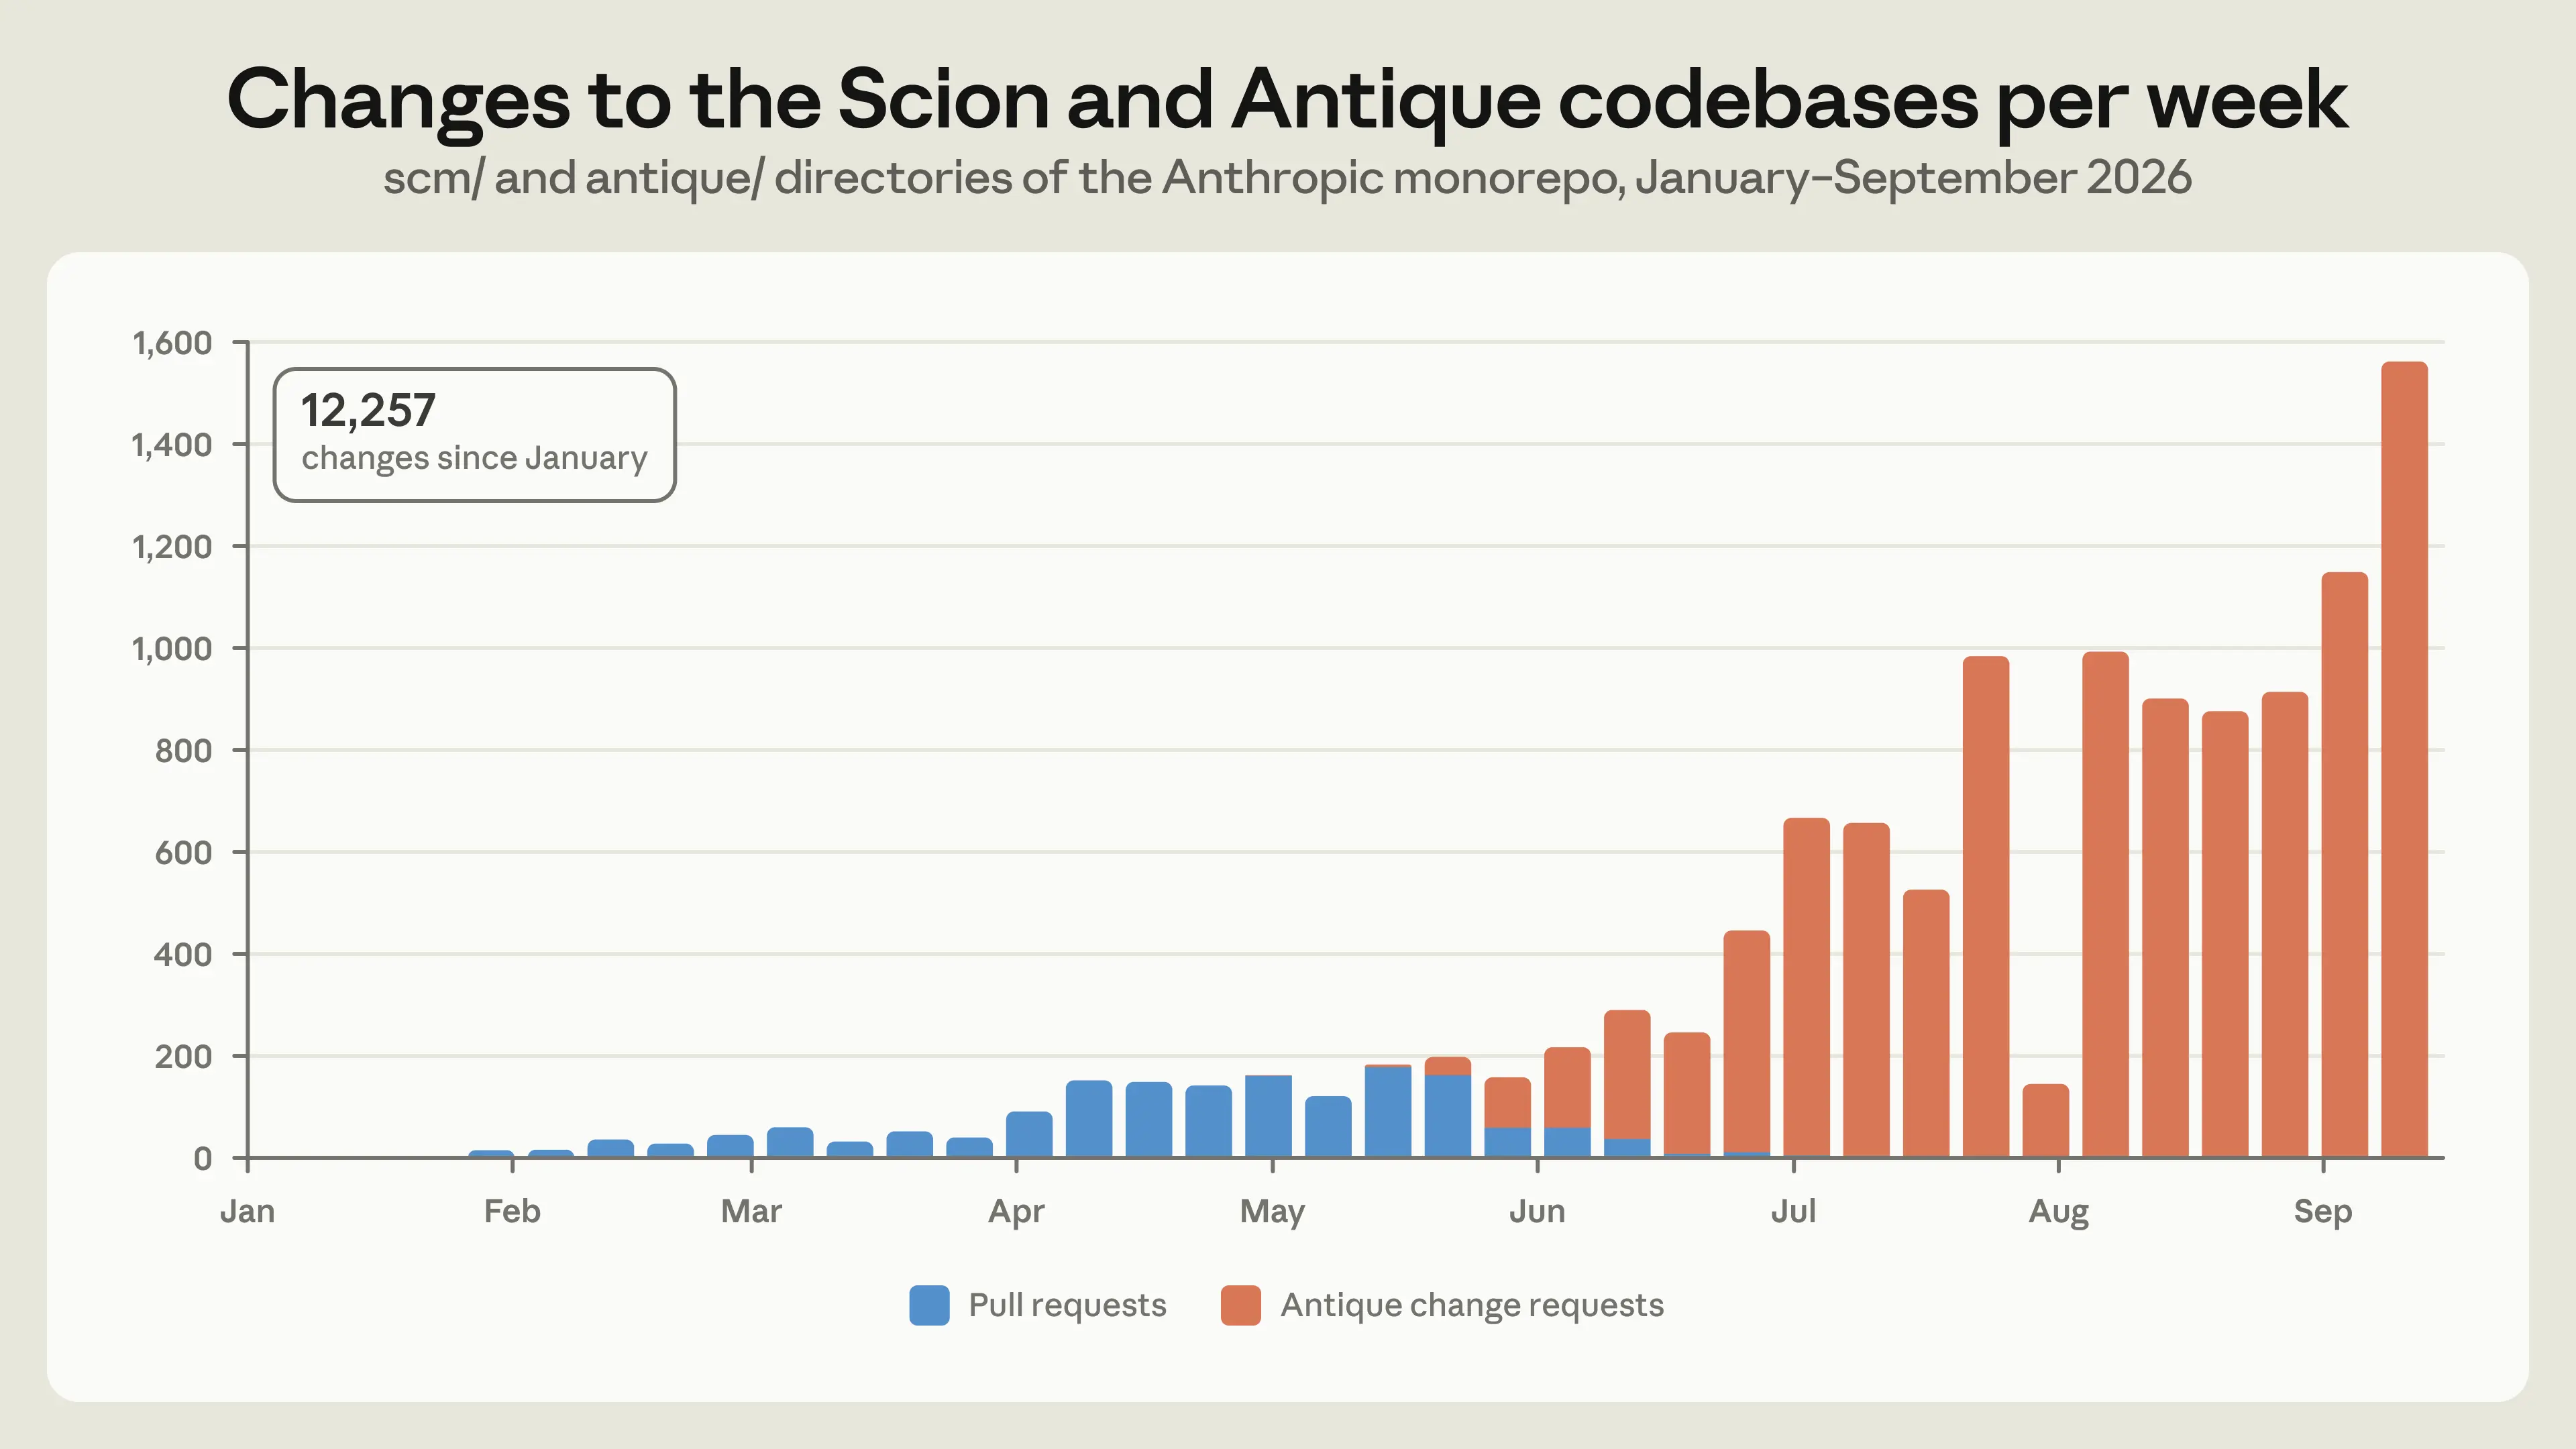
2026 年 1 月至 9 月,每周合并到 Scion 和 Antique 代码库的变更。
构建和运营 Scion 的经验,为智能体规模软件的未来构建方式提供了一些有趣的启示。
**小团队快速开发将变得更加普遍。**一个七人团队同时构建了 Scion _和_ Antique(我们的代码审查工具,完全可以另写一整篇博客来介绍),更不用说还有六个相关系统,并在五个月内完全迁移到它们之上。我们完成这一切的同时,每天合并的代码量增加了 10 倍。过去,开发和部署这样一个源代码控制系统,需要一家公司投入数年时间进行迭代迁移,并动用多得多的工程师。我们认为这种快速、灵活的迁移在未来会变得更加普遍。
**工程师的价值丝毫不减,但他们的工作正在发生变化。**所有参与这个系统的工程师现在都会认为 Claude 在_编写_代码方面比他们更强。但我们的工程师仍然提供了对高层系统间组件和设计层面权衡的宝贵理解,围绕我们想要解决的问题和我们知道自己需要达到的规模做出明智的选择。很多时候,我们发现工程师的角色就是告诉 Claude“不行”。智能体有时会为了满足一种本就不该被允许的模式而违反核心系统约束。这在我们迁移过程中尤为常见。例如,有多个系统试图通过线性读取提交日志来暴力查找某个变更何时合并到 main,而不是询问我们的代码审查工具。Anthropic 还大量使用对抗性审查,虽然这在许多方面极其有效,但也可能视野狭隘,因此需要熟练的工程师引导 Claude 不要为了应对假设性的担忧而对系统某些部分过度设计。例如,有一次这样的审查对信任另一个内部服务过于防御,导致 Claude 添加了过多的验证和复杂性。我们的团队成员仍然会审查该系统的每一个变更请求,但他们现在审视的是变更的_意图_,而不是逐行阅读代码。
**我们得以大幅提升优化和质量。**凭借 Claude 能够以远超我们自身速度编写海量代码的能力,Scion 是我们参与过的最经过充分测试和充分防御的代码库之一。即便在紧张的时间线内,我们也能够为我们遇到过的每一种非平凡基础设施和源代码控制交互构建封闭式模拟,以及模糊测试和复杂的速率限制。Claude 还随手发现了重大优化——例如,对祖先查询的一项算法优化,该查询漏掉了我们的一个索引——这本需要专家花费数天或数周的分析和调优……然后第二天又把这一切重做了一遍。
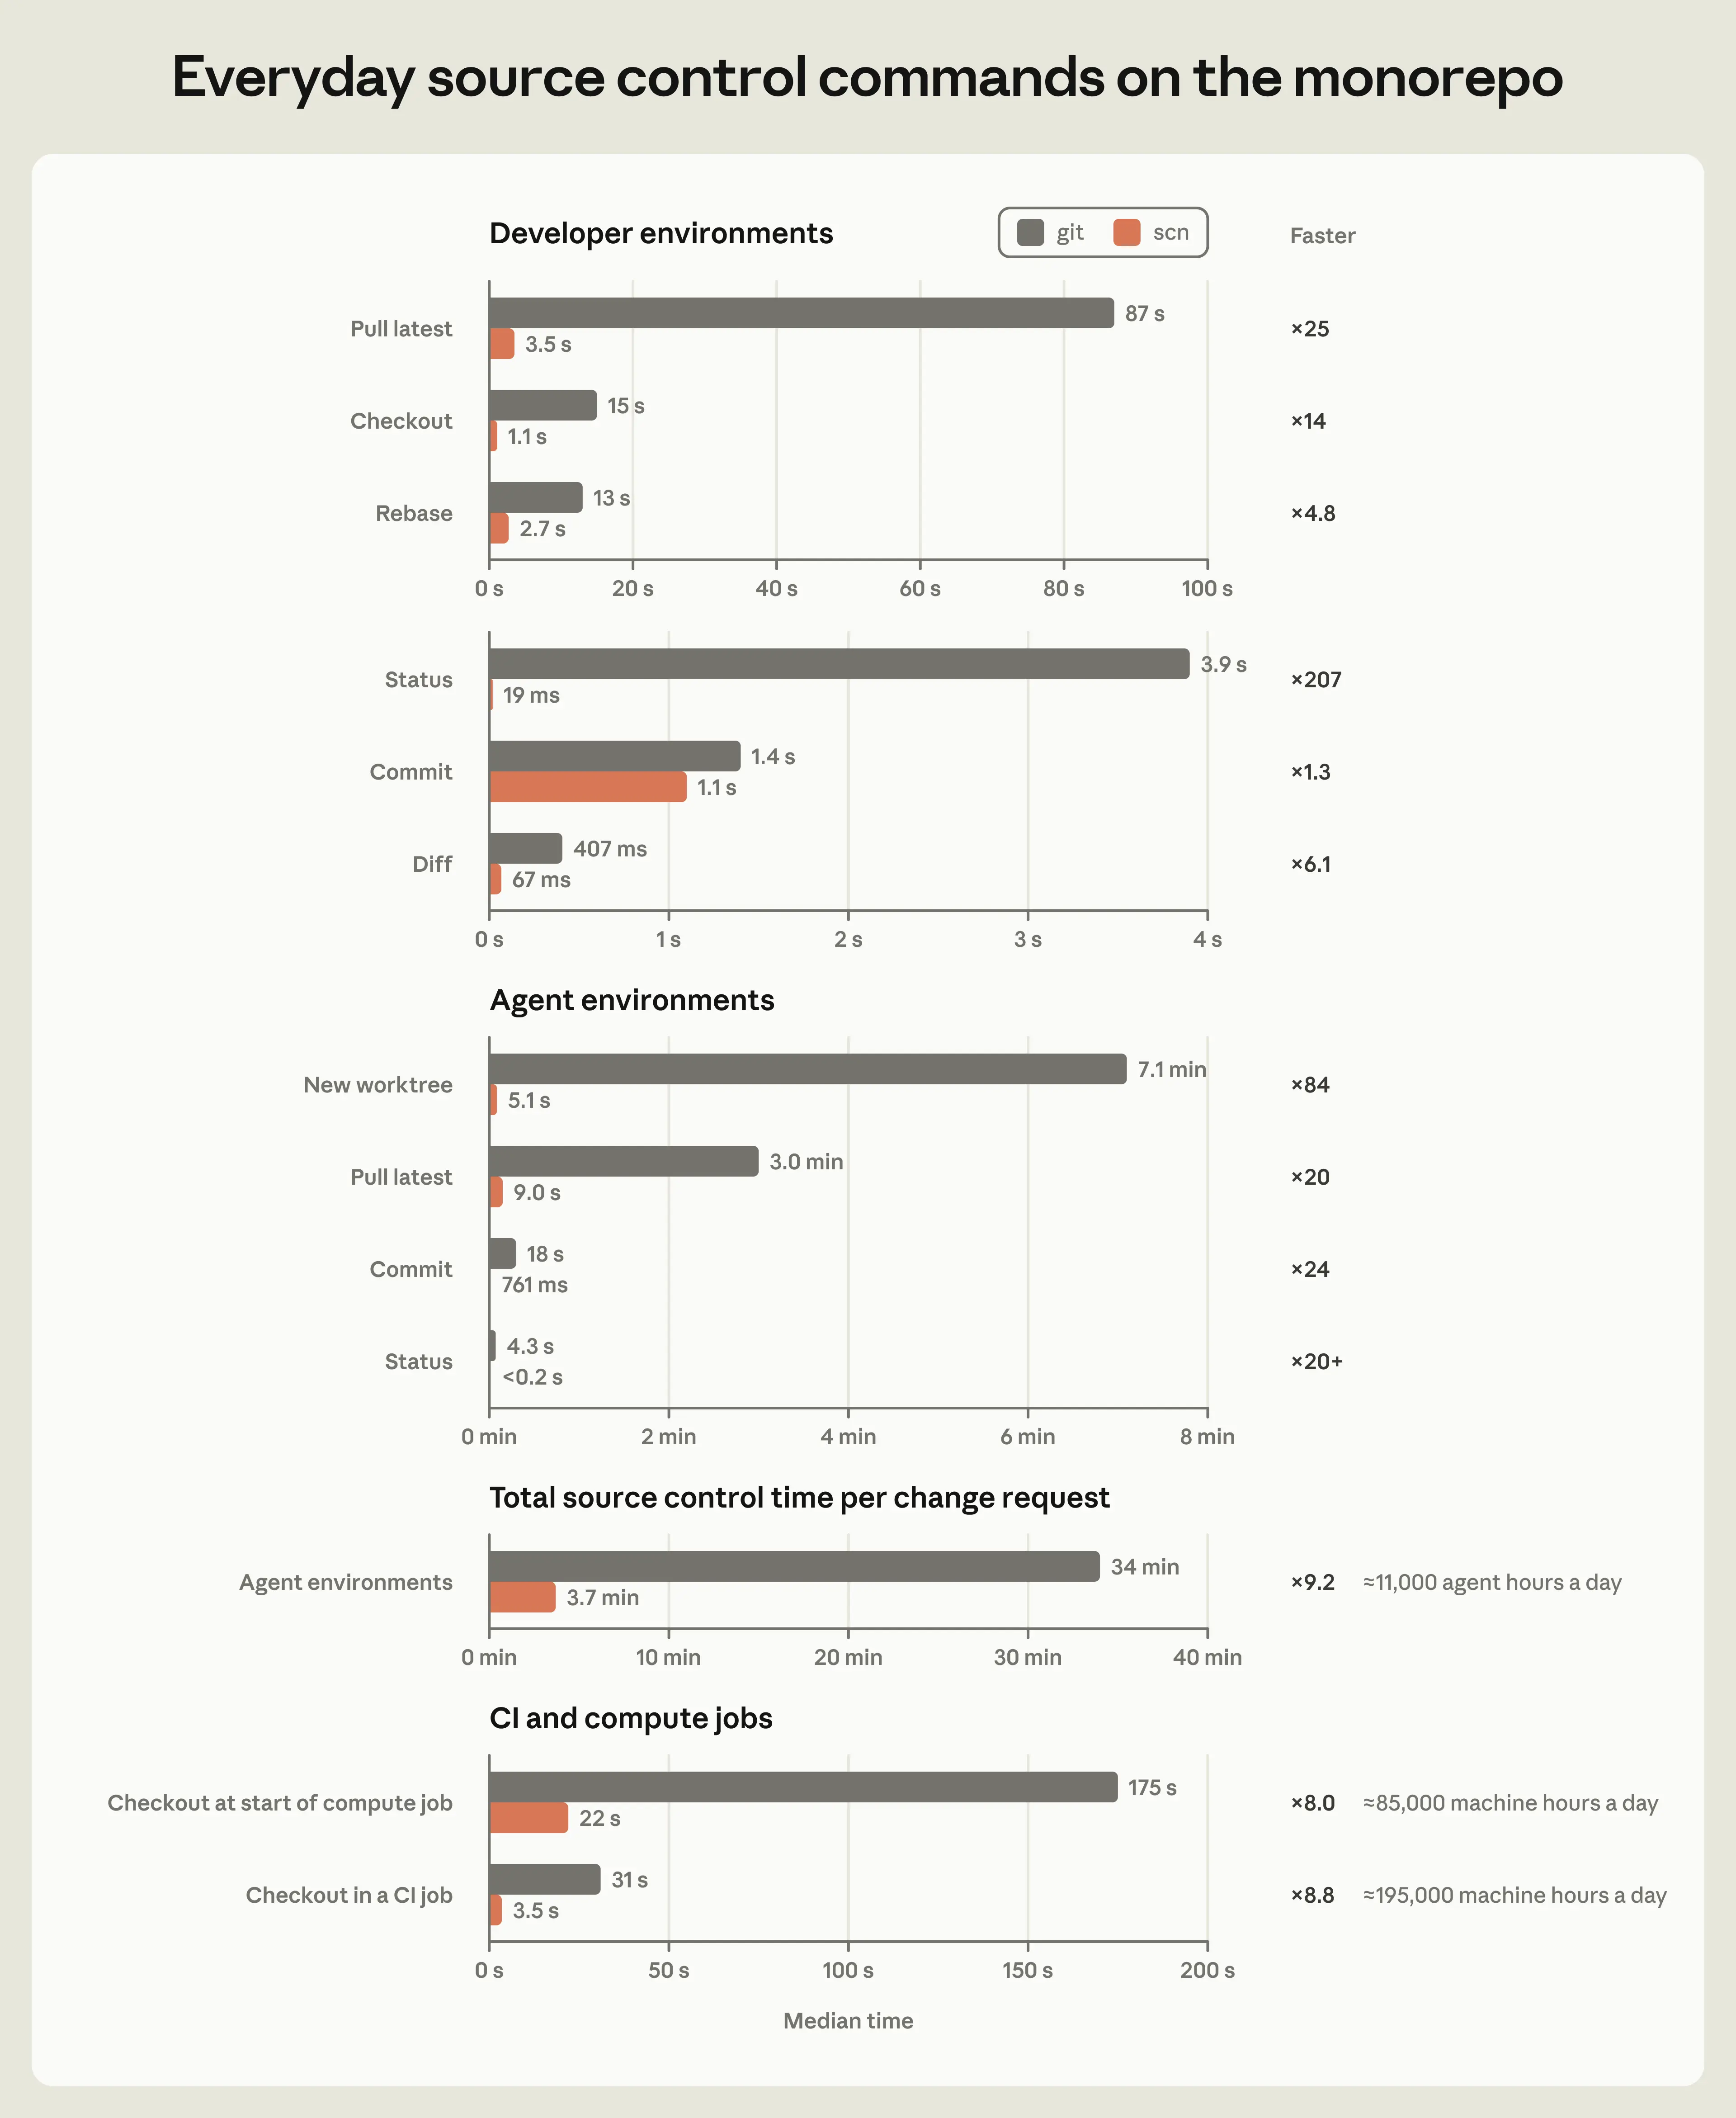
在原生 Scion 仓库上观察到的性能改进。
**我们为新形式的 monorepo 安全奠定了基础。**在庞大的 monorepo 中管理安全、安保和合规,与管理其规模和体量同样重要。我们在构建 Scion 时从一开始就考虑到了这些。它支持对仓库进行丰富的访问控制,以及将权限应用到单个目录的能力,从而保护最敏感的代码,同时不失去 monorepo 的优势。此外,我们构建的代码审查工具能够对审批表达复杂的语义约束,这让我们能够区分仅注释变更这类简单变更和敏感的逻辑变更,以便人工审查者能够专注于最重要的变更。
**运营卓越可以达到一个新的水平。**我们的团队大量使用 Claude Tag,这帮助我们监控系统的每个组件。例如,我们创建了 Slack 频道,让 Claude 专注于单个组件的健康状况。我们称这些 Claude 为“超级粉丝”。我们有 scion-daemon 超级粉丝、scion-cache 超级粉丝、Antique 合并队列超级粉丝等等。它们可以访问我们的遥测数据和日志,表现得像一位经验丰富的工程师,除了刷新图表和寻找任何异常之外无事可做。我们所有系统也都有传统告警,但我们的超级粉丝能发现微妙而新颖的问题,相比之下这些告警显得过于单一。
**我们正在彻底重新思考我们的先验认知。**这个项目促使我们认真审视其他为人类规模设计的工作流。例如,一个正规的合并队列在智能体规模下并不太合理。当数百甚至数千个变更可以在测试运行时合并,CI 到底意味着什么?我们一直无法有效复制行业中合并队列全局仓库锁的标准做法,因此转而投入合并后和部署前的自动化测试。这确实意味着并发变更可能冲突,但 Claude 通常能比人类发现冲突更快地修复它们。
## 为更广泛的生态系统做贡献
我们认为 Scion 只是解决能力日益强大的 AI 智能体所引发的扩展性问题的一部分答案。我们分享这些细节,作为团队如何应对类似挑战的一个示例,不过我们并不指望我们的解决方案或考量适用于所有情况。
Scion 绝不是 git 在通用场景下的合适替代品。我们在这里概述的概念只对真正庞大的 monorepo 有意义,这类仓库要么有数万名工程师,要么有大量智能体在频繁编写代码。此外,Anthropic 的独特之处在于,我们为内部使用花费 token 的能力远远超过任何其他企业现实中愿意花费的水平。我们这样做既是为了满足自身的软件开发需求,也是为了测试 Claude 的能力。
实际上,很难将 Scion 以一种对其他组织普遍有用的形式提供出来。它与 git 差异很大,意味着公司需要迁移开发生命周期的每一个环节,而且它需要自己的代码审查、代码搜索和 CI。我们这些组件的内部版本高度定制化,因此其他组织很难采用,我们也担心试图构建一个试图取悦所有人的公开版本实际上并不会很有用。
然而,我们预计这类问题在未来六到十二个月内会变得更加普遍,而让每一家使用 git 的公司都独自面对类似的挑战,将是对工程资源的低效利用。有鉴于此,我们认为最有影响力的事情就是分享我们的思考,让其他开发者能够在不偏离整体模型的前提下,把 Scion 中最成功的部分应用到 git 上。git 服务器不必以与 git 客户端相同的方式工作;已经存在能够带来显著扩展性提升的新型服务器架构。Git 平台可以提供像 Scion 这样全面的服务端 RPC,甚至可能以标准化的方式跨多个代码托管平台提供,让 git 客户端学会与之通信。协商协议也不必与今天完全一样,而且 git 中各种稀疏和浅克隆特性也可以被很好地组合起来。
最后,我们要承认,git 社区已经花了近二十年时间为数百万开发者扩展这一平台。我们的贡献要狭窄得多:分享我们对智能体软件开发如何与这些系统交互的早期看法,以便我们能与 GitHub、GitLab 和开源社区合作,支持开发者不断变化的需求。在软件开发生命周期与 AI 指数级增长相交汇之际,我们同舟共济。
## 致谢
由 Nick G. 和源代码管理团队撰写:S.G.、R.K.、Dan C.、Garrett H.、Ben L.、Colin M.、Joe P.。我们感谢 Vilas J. 和 Sergiu D. 在这段雄心勃勃的旅程中对源代码管理团队的支持,以及 Amir O. 对 Antique 的早期贡献。
## 正文 · 原文
At Anthropic, coding is no longer the bottleneck to building systems or doing research. Claude is able to autonomously iterate on research loops, micro-optimize complex programs, and build new services from the ground up at a speed and scale we haven’t seen before. The bottleneck, now, is all of the developer infrastructure built for human scale: source control, builds, and CI.
In May 2026, Anthropic averaged around 2,500 code changes merged per day; as of September, we merged over 30,000 per day. We don’t expect this rate of growth to slow down anytime soon; the latent demand for merging code is practically infinite, and every bottleneck we remove immediately leads to a further increase in the amount of code we produce.

Changes merged to our monorepo per day, from January to September 2026.
In order to support this growth, we built Scion, an in-house version control system, and fully migrated our monorepo from git in five months. We also built and shipped a code review surface (called Antique), code search, a rich source control IAM system, novel ways of managing and landing large amounts of reviewed code, and more, all in that same time period. In this post, we’ll focus on how we built Scion specifically. It makes for an interesting case study: Claude’s ability to write code was both what put us in this situation in the first place _and_ how we were able to quickly build a high-quality, scalable system to deal with it.
## Growing our monorepo
Before we explore what we built, we should acknowledge how unusual our workload is. Unsurprisingly, Anthropic uses Claude to write software far more than almost any other company, so we’re often the first to see where tools built for human scale start to strain. Source control is just one example of this. While we don’t expect many organizations to have these problems in the very near term, we suspect it won’t be too long before others who use AI coding tools experience these same pressure points, which is why we wanted to share what we built and what we learned.
Git is a decentralized system: every clone is a complete, self-contained repository that can compute diffs, read history and blame, and check out any revision while fully offline. For the vast majority of repositories, this is the right design, and it’s a large part of why git became the standard.
As our monorepo grows, it increasingly doesn’t fit that design space. The history of our main branch alone is almost 100 GB, and a _compressed_ working copy is over 25 GB. We perform on the order of 25 million code checkouts per day for CI, before counting developer environments, agent sandboxes, and research jobs. Fetched naively, that would be over 600 PB of git traffic per day.
Git offers tools for working with a slice of a repository, such as shallow clones, sparse checkouts, and promisor remotes. Beyond these, there are standard workarounds for large monorepos, like internal git mirrors and repository snapshots (seeds) kept in blob storage. We’ve used all of them—at our peak, we operated several hundred internal git mirrors to deal with the load. This bought us time, but they became harder to operate as our merge rate increased. Seeds fell further from the tip of main between refreshes, and it took more and more care to keep operations that depend on history, like diff and blame, working on partial clones.

The typical setup for scaling git checkouts.
Taking a step back, we noticed that, like most companies, we were using git as a centralized system with one authoritative copy, but nearly all of our clients were agents and jobs that are online by definition. The properties that make git excellent for distributed, offline work were actively undermining our ability to scale as the repo grew. So we asked ourselves: if we designed source control with the fact that agents are always online in mind from the start, what would it look like?
## Principles for agent-scale source control
With agentic coding, many common assumptions about how software is developed are evolving. We embraced these changes when building Scion, which allowed us to take a fundamentally different approach than git on several core principles. Source control for huge monorepos has prior art, notably Google’s [Piper](https://en.wikipedia.org/wiki/Piper_\(source_control_system\)) and Meta’s [Sapling](https://sapling-scm.com/), so we were able to build Scion with their hard-won lessons in mind. Our principles are:
**Clients are always online.** Git assumes that clients work offline and need a complete copy of the repository. Since nearly all of our clients are agents and jobs, we designed Scion’s client and protocols around a server that is always reachable, and have clients fetch data when they need it.
**Client-server asymmetry.** In git, every client is capable of being a full-fledged server. In Scion, the server answers questions about file history and blame, creates commits, performs merges and rebases, and so on. The client maintains a bounded local object cache, lays out the working copy files on disk, monitors for filesystem changes, and gives users an ergonomic way to work with the server. It can compute very little on its own but, in exchange, it requires much less data locally.
**A comprehensive source control service can power many novel applications.** With git, a CI job or tool that needs to ask a question about the repository, such as who last changed a line or how two commits are related, has to maintain a local copy of the repo or hope that vendor-specific APIs provide the answer. With Scion, all of the source control queries the client uses are also exposed via API, so in many cases jobs don’t need a local repository at all. Many internal tools, such as our automated bisect and revert pipelines, wouldn’t be practical at scale without this cheap, programmatic access to source control.
**Everything must be horizontally scalable.** At our peak, we ran several hundred git mirrors, which significantly strained capacity and no longer scaled once the repo outgrew the mirrors’ disks or memory limits. In Scion, the repository’s data is distributed, and every component is independently scalable; there is no fully materialized copy of the repo anywhere, even on the server. There is no equivalent of packfiles (git’s compressed bundles of objects), so no repository maintenance is needed.
**Commits must be cheap, incremental, and lock-free.** In git, you commit locally and then push to share your work. In Scion, every commit, rebase, or merge happens on the server, so there’s nothing to push, but each of those operations needs to be fast. The cost of creating a commit and updating its downstream data structures has to scale with the size of the change, not the overall size of the repo, or the server can’t keep up. The development lifecycle in Scion discourages refs (pointers to commits, such as branches and tags), except for the main ref or release branches, because _global_ state that every server has to agree on is a looming scaling problem.
**The working copy is optional, and sparse by design.** Because our monorepo is so large, and because we check out code tens of millions of times a day for CI, we wanted to avoid checkouts whenever we could. With Scion, a CI job that needs the diff between a commit and its merge base, for example, can ask the server for it. The same goes for writes: many write workloads can also skip the checkout and function entirely via API. Scion’s protocol is centered around sparse checkouts, which only contain the directories the client asks for, and virtualized checkouts, which materialize files on demand, so when a job does need files on disk, the client only pays for what it actually reads.
## How Scion works
It’s helpful to understand how these principles came together in practice when building Scion. These insights can apply to other source control systems or, more broadly, to other stages of the software development lifecycle.
### Data structures
In Scion, the unit of work is a “changeset,” an entry in a write-ahead log. A changeset stores most of what you’d expect from a commit in git. But where a git commit stores a pointer to the tree, a changeset stores a list of the files that changed relative to its first parent,1 along with content-addressed pointers to the compressed file contents in blob storage. Changesets are created server-side and are available everywhere, instantly.

The shape of a changeset in Scion.
This structure lets us accept changesets with very high throughput because there are no packfiles to accept, no locking or cross-server coordination, and no refs to move around. Scion does technically support refs, but since neither creating nor fetching commits involves them, moving one is a compare-and-swap on a single Spanner row that happens separately from creating changesets.
A changeset records only what’s changed, so on its own, it can’t quickly answer questions like who last edited a line or which commits affected a file. To answer those, Scion builds additional data structures from the changesets, including dedicated structures for file blame and path history and skip lists for the commit graph. We call everything that isn’t directly part of the changeset “derived data,” and we compute it all through one generic mechanism. Each type of derived data is defined recursively, so its value for a changeset is computed from its values for that changeset’s parents.
This mechanism has three benefits. First, we can easily add a new type of derived data when a new data structure would make some operation faster. Second, for each type, we can choose whether to compute it eagerly or defer the work, so we avoid materializing data we don’t need. And third, because the client never sees the internals of these data structures, we can optimize them without changing the client. We’ve added new types of derived data many times as the system has grown, such as new indices for performing copy detection or path-based file search.
### Scaling Scion
A small fleet of Scion servers provides source control APIs for any operation a client needs, such as getting changesets, computing diffs, finding merge bases, and fetching blobs. All source control data is content-addressed, so a piece of data never changes once it’s stored, and any server can cache it without checking with the others. As a result, the servers are horizontally scalable and require little coordination. They are essentially large caches that can also compute derived data on the fly and write the results back to Spanner.
Scion’s many consumers no longer need to maintain local repositories of their own. Fetching and maintaining the repository used to be a significant maintenance burden for CI jobs or tools that needed to ask source control questions, particularly about commit ancestry and blame. Early in the migration, before we had our own client, repo format, or protocols, Scion only answered these “metadata” queries. Fetching file contents and materializing working copies are far more data-intensive operations, and they needed a design of their own.
Scion’s scn client deviates from git’s fetch protocols in several important ways and, as a result, lends itself to a highly scalable architecture that requires significantly less CPU than git servers. Scion’s negotiation doesn’t tell the server what the client already has; instead, it operates exclusively on trees and blobs the client wants. Starting from a root tree, the client checks its local store for missing trees and requests them recursively, then repeats the process for blobs. Every request is for a specific object that never changes, so any cache can answer it, and the architecture closely resembles traditional tiered caches. The process is also efficient and resumable, because there is no single multi-gigabyte packfile response. Sparse and even virtualized checkouts don’t need special support, because the client simply doesn’t ask for trees it doesn’t want.
In the fleet, the client talks over a socket to a daemon, scion-daemon, that stores objects for the whole node. Most of our nodes need access to the monorepo, and jobs on the same node reuse most of the same objects. Each daemon starts from a periodically refreshed snapshot, then talks only to the tree and blob cache servers in its region, called scion-cache. These cache servers stream objects directly from memory, in the disk format that the daemon will consume, so they don’t need to spend time computing the client’s missing objects or performing delta compression. When a cache is missing an object, it asks the authoritative scion-servers, which read from Spanner or cloud storage as needed.
The scion-daemon, scion-cache, and scion-server all respond to identical RPCs for this protocol, so the client doesn’t need to know the cache topology. Any tier could theoretically talk to any other, but we strictly enforce the tiering to isolate failure domains. We want to avoid a situation where a failure in a regional scion-cache overwhelms the upstream scion-servers and brings down the entire system.

Scion’s checkout architecture.
Each tier of this system maintains a cache hit rate of over 99% and does not require long-lived state, so it’s easy to scale up if needed. Our Scion infrastructure footprint is now 200x smaller than our previous git mirroring infrastructure in terms of CPU and memory requirements. CI and research jobs check out code two orders of magnitude faster (in seconds rather than minutes), which frees up a sizable amount of capacity across the fleet; CI alone realized a 25% CPU capacity win. Neither clients nor caches need to perform repository maintenance, which simplifies the lifecycle management of our jobs.
## What we learned building Scion
We started building Scion around the same time as [Claude Mythos Preview](https://www.anthropic.com/claude/mythos) and [Claude Tag](https://www.anthropic.com/news/introducing-claude-tag) became available internally. Both of these releases simultaneously amplified the need for Scion and meaningfully accelerated how quickly we could build it.
Here’s a particularly striking example. Earlier in the year, we had largely handwritten the first version of the git-to-Scion ingestion pipeline as a prototype. We thought it was good—until we got our hands on an early internal snapshot of Claude Mythos Preview. We asked it to rewrite the whole thing, and with no further instructions, it produced a version that consumed 20x less memory and was 4x faster, while preserving all of the implicit invariants around ingestion ordering and data structures.

Merged changes to the Scion and Antique codebases per week, from January to September 2026.
What we learned building and operating Scion offers some interesting lessons for what building agent-scale software could look like.
**Rapid development with a small team will become more common.** A team of seven people built both Scion _and_ Antique (our code review tool, which we could easily write a whole other blog post about), not to mention half a dozen related systems, and fully migrated to them in five months. We did all this while the volume of code merged per day increased by 10x. In the past, developing and deploying a source control system like this would have taken a company years of iterative migration, with many more engineers. We think this sort of fast, nimble migration will become more common in the future.
**Engineers are no less valuable, but their work is changing.** All of the engineers who worked on this system would now rate Claude as better at _writing_ code than them. But our engineers still supplied the invaluable understanding of the high-level inter-system components and the design-level tradeoffs, making informed choices around the problems we wanted to solve and the scale we knew we needed to achieve. Very often, we found that the role of the engineers was to tell Claude “no.” Agents will sometimes violate core system constraints to satisfy a pattern that should never have been allowed in the first place. This was particularly common in our migration. For example, there were multiple systems that tried to brute force looking up when a change merged to main by linearly reading the commit log instead of asking our code review tool. Anthropic also makes extensive use of adversarial review, and, while this is incredibly effective in many ways, it can also be myopic, so skilled engineers needed to steer Claude away from over-engineering parts of the system in response to hypothetical concerns. For example, one such review was overly defensive about trusting another internal service, which resulted in Claude adding excessive validation and complexity. Our team members still review every change request for the system, but they now examine the _intent_ of the change as opposed to reading every line of code.
**We were able to substantially improve optimization and quality.** By virtue of Claude’s ability to write immense amounts of code much faster than we could ourselves, Scion is among the most well-tested and well-defended codebases we have ever worked on. Even on our tight timeline, we were able to build hermetic simulations of every non-trivial infrastructure and source control interaction we’ve ever encountered, as well as fuzzing and sophisticated rate limiting. Claude also casually found significant optimizations—for example, an algorithmic optimization to ancestry queries that missed one of our indexes—that would have taken an expert days or weeks of analysis and tuning… and then did it all again the next day.

Observed performance improvements on native Scion repos.
**We laid the groundwork for new forms of monorepo security.** Managing safety, security, and compliance in a massive monorepo is as important as managing the size and scale. We built Scion with these in mind from the start. It supports rich access control on repositories, as well as the ability to apply permissions to individual directories in order to protect the most sensitive code without losing the benefits of a monorepo. Furthermore, the code review tooling we built can express complex semantic constraints on approvals, which lets us differentiate simple things like comment-only changes from sensitive logical changes, so that human reviewers can focus on the most consequential changes.
**A new level of operational excellence is possible.** Our team uses Claude Tag heavily, which has helped us monitor each component of the system. For example, we created Slack channels where we tasked Claude with being obsessively focused on the health of a single component. We call these Claudes “superfans.” We have a scion-daemon superfan, a scion-cache superfan, an Antique merge queue superfan, and so on. They have access to our telemetry and logs, and act like an experienced engineer who has nothing better to do than to refresh charts and look for anything strange. We also have traditional alerts for all of our systems, but our superfans can detect subtle and novel issues that make these alerts seem one-dimensional by comparison.
**We’re completely rethinking our priors.** This project prompted us to take a very hard look at other workflows designed for human scale. A proper merge queue, for example, doesn’t make much sense at agent scale. What does CI even mean when hundreds or even thousands of changes can merge while tests are running? We haven’t been able to effectively replicate the industry standard of a global repository lock on the merge queue, so instead, we’ve invested in post-merge and pre-deploy automated testing. This does mean that concurrent changes can conflict, but Claude can typically fix these conflicts faster than humans can even identify them.
## Contributing to the wider ecosystem
We see Scion as just one part of the answer to the scaling concerns that increasingly capable AI agents have raised. We’re sharing these details as an example of how teams can tackle similar challenges, though we don’t expect our solution, or our considerations, to suit every case.
Scion is by no means a suitable replacement for git for general use. The concepts we’ve outlined here really only make sense for truly enormous monorepos, with either tens of thousands of engineers or swarms of agents prolifically writing code. Plus, Anthropic is unique in that our ability to spend tokens for internal use far exceeds what any other business would realistically want to spend. We do this both to address our own software development needs, and to test Claude’s capabilities.
Practically speaking, it’s difficult to offer Scion in a form that would be broadly useful to other organizations. It diverges significantly from git, meaning companies would need to migrate every piece of the development lifecycle, and it requires its own code review, code search, and CI. Our internal versions of these components are highly bespoke, so they would be difficult for other organizations to adopt, and we worry that attempting to build a public version that tries to please everyone wouldn’t actually be very useful.
However, we anticipate that this class of problems will become more commonplace over the next six to 12 months, and it would be an inefficient use of engineering resources for every company using git to face similar challenges alone. Given that, we think the most impactful thing we can do is to share our thinking, so that other developers can apply some of the most successful parts of Scion to git without departing from the overall model. A git server doesn’t have to work the same way as a git client does; novel server architectures exist that provide significant scaling improvements. Git platforms can provide comprehensive server-side RPCs like Scion, perhaps even in a standardized way across forges that the git client can learn to talk to. The negotiation protocol doesn’t have to look exactly like it does today, either, and the various sparse and shallow features in git can be made to compose well.
Lastly, we want to acknowledge that the git community has spent nearly two decades scaling the platform for millions of developers. Our contribution is far narrower: sharing our early view into how agentic software development interacts with these systems, so that we can partner with GitHub, GitLab, and the OSS community to support the changing needs of developers. We’re all in it together as the software development lifecycle intersects with the AI exponential.
## Acknowledgements
Written by Nick G. and the source control team: S.G., R.K., Dan C., Garrett H., Ben L., Colin M., Joe P. We’re grateful to Vilas J. and Sergiu D. for supporting the source control team on this ambitious journey and Amir O. for early contributions to Antique.