# Google DeepMind 发布开源轻量多模态嵌入模型 EmbeddingGemma 2
> 原标题:EmbeddingGemma 2: an open, lightweight multimodal embedding model
- 来源:Google DeepMind:Blog
- 发布时间:2026-10-06T19:57:04.000Z
- AIHOT:https://aihot.news/items/g1k2ragppm8j4apj75qu1k4ug
- 原文:https://deepmind.google/blog/embeddinggemma-2-an-open-lightweight-multimodal-embedding-model/
## 摘要
Google DeepMind 发布 EmbeddingGemma 2,基于 Gemma 4 架构,以 Apache 2.0 许可开源,将文本、代码、图像、视频和音频映射到统一嵌入空间。
## 推荐理由
官方发布给出参数量、内存占用、维度裁剪和基准分数等具体细节,读者可据此评估端侧多模态嵌入方案的可行性。
## 正文 · 中文译文
2026年10月6日
|
EmbeddingGemma 2 是设备端多模态嵌入能力最强的模型,可将文本、图像、音频和视频的组合原生映射到统一的嵌入空间。
* * *
Sahil Dua
Google DeepMind 研究工程师
Henrique Schechter Vera
Google DeepMind 研究工程师
* * *
收听文章
\[\[duration\]\] 分钟
此内容由 Google AI 生成。生成式 AI 仍处于实验阶段
我们去年推出了 [EmbeddingGemma](https://developers.googleblog.com/en/introducing-embeddinggemma/),旨在为高质量文本嵌入提供一种轻量级选择,帮助你的应用直接在消费级硬件上整理、搜索和连接信息。开发者社区的反馈远超我们的预期。凭借超过 2000 万次下载,开发者已用它打造更智能的设备端搜索工具和隐私优先的检索增强生成(RAG)流水线。
今天,我们推出 EmbeddingGemma 2**,**将能力从文本扩展至统一代码、图像、视频和音频的共享嵌入空间。EmbeddingGemma 2 基于 Gemma 4 架构构建,并以商业友好的 Apache 2.0 许可证发布,拥有 7.4 亿参数,非常适合设备端推理。它可以帮助你从语音备忘录中找到特定的视频片段,或根据文本查询搜索数小时的音频录音,所有这些都由一个原生的多模态模型处理。
EmbeddingGemma 2 采用与 Gemini Embedding 模型相同的技术构建,具备以下特点:
- **同尺寸中最佳:**在 MTEB(大规模文本嵌入基准)Code 和 MAEB(大规模音频嵌入基准)等基准测试中,于 10 亿参数以下的多模态嵌入模型中取得同尺寸领先分数,同时在文本、视觉和音频任务上匹配或超越许多更大的模型。
- **模块化设计:**纯文本工作负载仅需 270M 参数,并可选配视觉(170M)和音频(300M)编码器以实现完整的多模态支持。
- **存储高效:**借助 Matryoshka 表示学习(MRL),开发者可以将输出向量从 768 维动态截断至 512、256 或 128 维。这为本地向量数据库和内存使用带来最高 6 倍的存储缩减。
- **针对设备端性能优化:**可在紧张的资源限制下高效运行。经过量化后,在 Google Pixel 11 Pro 上,EmbeddingGemma 2 的纯文本权重仅需约 191MB 活动 RAM,完整多模态模型约需 567MB。
- **支持扩展上下文:**具备 8K token 上下文窗口(比 EmbeddingGemma 1 大 4 倍),可直接在本地硬件上处理长达 5.5 分钟的音频、29 张图像、58 个视频帧,或它们的交错组合。
## 在代码、视觉和音频方面实现顶级质量
EmbeddingGemma 2 延续了 EmbeddingGemma 强大的多语言文本性能,同时在代码性能上实现了 9.92 分的显著提升(在 MTEB Code 中,从 68.76 提升至 78.68),非常适合本地代码库索引、语义代码搜索和编码智能体检索。在图像、视频、文档和音频方面,它为 10 亿参数以下的模型树立了每参数质量的新标准,甚至超越了一些规模超过其两倍的专用模型。
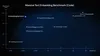
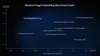
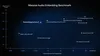
在 [EmbeddingGemma 2 模型卡](https://ai.google.dev/gemma/docs/embeddinggemma/model_card_2)中查看完整评估指标和模型信息。
## 实现完全在设备端的语义搜索、路由和检索
EmbeddingGemma 2 将强大的能力直接带到边缘硬件。在本地生成嵌入有助于确保数据隐私、降低流水线延迟,并赋能开发者构建完全离线运行的跨模态搜索与检索。
当与 Gemma 4 等生成式模型搭配使用时,EmbeddingGemma 2 可实现理解复杂多模态数据的端侧 RAG 流水线。由于 EmbeddingGemma 2 构建于 Gemma 4 之上,并共享其文本分词器和音频编码器,开发者可以在统一流水线中同时运行这两个模型,从而降低合并后的总内存占用。
要了解如何使用 LiteRT 构建端侧搜索和 RAG 系统,请阅读 [Google AI Edge 博客文章](http://developers.googleblog.com/google-ai-edge-with-embeddinggemma-2)。
## 开始使用 EmbeddingGemma 2
我们与以下合作伙伴密切合作,确保 EmbeddingGemma 2 在您构建的环境中开箱即用:
- **下载模型:**在 [Hugging Face](https://huggingface.co/google/embeddinggemma-2) 和 [Kaggle](https://www.kaggle.com/models/google/embeddinggemma-2) 上找到模型权重,Gemini Enterprise Agent Platform Model Garden 也将很快提供。访问 [Hugging Face 上的 LiteRT 社区](https://huggingface.co/litert-community)获取针对端侧优化的模型。
- **端侧部署:**使用 Google AI Edge [MediaPipe](https://developers.google.com/edge/mediapipe/solutions/decision/decision_maker) 开发跨平台应用,实现开箱即用的嵌入、检索与决策任务,或使用 [LiteRT](https://developers.google.com/edge/litert-lm) 进行自定义模型集成。使用 transformers.js 或 [WebGPU](https://huggingface.co/spaces/webml-community/embeddinggemma-2-webgpu) 为浏览器构建。
- **使用您喜爱的开发工具**:使用 transformers、sentence-transformers、[MLX](https://github.com/Blaizzy/mlx-vlm)、vLLM、[llama.cpp](https://huggingface.co/ggml-org/embeddinggemma-2-GGUF)、SGLang、[Ollama](http://ollama.com/library/embeddinggemma-2) 和 LMStudio 高效地提供模型服务。使用 [Qdrant](https://qdrant.tech/blog/embeddinggemma-2/) 存储您的嵌入向量。
- **微调:**遵循 [Unsloth](https://unsloth.ai/docs/models/embeddinggemma-2) 的指南,了解如何针对您的用例微调 EmbeddingGemma 2。
探索我们的[开发者指南](https://developers.googleblog.com/en/embeddinggemma-2-the-developer-guide/)、[文档](https://ai.google.dev/gemma/docs/embeddinggemma),以及[推理](https://ai.google.dev/gemma/docs/embeddinggemma/inference-embeddinggemma-with-sentence-transformers)和[微调](https://ai.google.dev/gemma/docs/embeddinggemma/fine-tuning-embeddinggemma-with-sentence-transformers)指南。
## 正文 · 原文
Oct 06, 2026
|
EmbeddingGemma 2 is the most capable model for on-device multimodal embeddings, natively mapping combinations of text, images, audio, and video into a unified embedding space.
* * *
Sahil Dua
Research Engineer, Google DeepMind
Henrique Schechter Vera
Research Engineer, Google DeepMind
* * *

Listen to article
\[\[duration\]\] minutes
This content is generated by Google AI. Generative AI is experimental
We introduced [EmbeddingGemma](https://developers.googleblog.com/en/introducing-embeddinggemma/) last year to provide a lightweight option for high-quality text embeddings, to help your apps organize, search, and connect information directly on consumer hardware. The developer community’s response blew past our expectations. With more than 20 million downloads, builders have used it to power smarter on-device search tools and privacy-first retrieval augmented generation (RAG) pipelines.
Today, we’re launching EmbeddingGemma 2**,** expanding beyond text to unify code, images, video, and audio in a shared embedding space. Built on the Gemma 4 architecture and released under a commercially permissive Apache 2.0 license, EmbeddingGemma 2 has 740 million parameters, making it optimal for on-device inference. It can help find a specific video clip from a voice memo, or search through hours of audio recordings based on a text query, all processed by a single, natively multimodal model.
Built from the same technology as Gemini Embedding models, EmbeddingGemma 2 is:
- **Best-in-class for its size:** Achieves leading scores among sub-1B multimodal embedders for its size across benchmarks like MTEB (Massive Text Embedding Benchmark) Code and MAEB (Massive Audio Embedding Benchmark), while matching or outperforming many larger models across text, vision, and audio tasks.
- **Modular by design:** Requires as little as 270M parameters for text-only workloads with optional vision (170M) and audio (300M) encoders for full multimodal support.
- **Storage-efficient:** Using Matryoshka Representation Learning (MRL), developers can dynamically truncate output vectors from 768 dimensions down to 512, 256, or 128 dimensions. This provides up to 6x storage reduction for local vector databases and memory usage.
- **Optimized for on-device performance:** Runs efficiently within tight resource constraints. With quantization, on a Google Pixel 11 Pro, EmbeddingGemma 2 requires as little as ~191MB active RAM for text-only weights and ~567MB for the full multimodal model.
- **Extended context ready:** Features an 8K token context window (4x larger than EmbeddingGemma 1), allowing it to process up to 5.5 minutes of audio, 29 images, 58 video frames, or interleaved combinations thereof directly on local hardware.
## Achieving top-tier quality for code, vision, and audio
EmbeddingGemma 2 matches the strong multilingual text performance of EmbeddingGemma while delivering a significant 9.92-point improvement on code performance (in MTEB Code, from 68.76 to 78.68), making it well-suited for local codebase indexing, semantic code search, and coding agent retrieval. Across image, video, documents, and audio, it sets a new standard in quality-per-parameter for sub-1B models and even outperforms some specialist models more than twice its size.



Find full evaluation metrics and model information in the [EmbeddingGemma 2 model card](https://ai.google.dev/gemma/docs/embeddinggemma/model_card_2).
## Enabling semantic search, routing, and retrieval, fully on-device
EmbeddingGemma 2 brings robust capabilities directly to edge hardware. Generating embeddings locally helps ensure data privacy, reduces pipeline latency, and empowers developers to build cross-modal search and retrieval that works entirely offline.
When paired with generative models such as Gemma 4, EmbeddingGemma 2 enables on-device RAG pipelines that understand complex multimodal data. Because EmbeddingGemma 2 is built on Gemma 4 and shares its text tokenizer and audio encoder, developers can run both models together in a unified pipeline with a lower combined total memory footprint.
To learn how to build on-device search and RAG systems with LiteRT, read the [Google AI Edge blog post](http://developers.googleblog.com/google-ai-edge-with-embeddinggemma-2).
## Getting started with EmbeddingGemma 2
We worked closely with the following partners to ensure EmbeddingGemma 2 works immediately where you build:
- **Download the models:** Find the model weights on [Hugging Face](https://huggingface.co/google/embeddinggemma-2) and [Kaggle](https://www.kaggle.com/models/google/embeddinggemma-2), with Gemini Enterprise Agent Platform Model Garden availability coming soon. Visit [LiteRT Community on Hugging Face](https://huggingface.co/litert-community) for models optimized for on-device.
- **On-device deployment:** Develop cross-platform apps with Google AI Edge [MediaPipe](https://developers.google.com/edge/mediapipe/solutions/decision/decision_maker) for turnkey embedding, retrieval & decision tasks or [LiteRT](https://developers.google.com/edge/litert-lm) for custom model integration. Build for the browser with transformers.js or [WebGPU](https://huggingface.co/spaces/webml-community/embeddinggemma-2-webgpu).
- **Use your favorite development tools**: Serve the model efficiently using transformers, sentence-transformers, [MLX](https://github.com/Blaizzy/mlx-vlm), vLLM, [llama.cpp](https://huggingface.co/ggml-org/embeddinggemma-2-GGUF), SGLang, [Ollama](http://ollama.com/library/embeddinggemma-2), and LMStudio. Store your embedding vectors with [Qdrant](https://qdrant.tech/blog/embeddinggemma-2/).
- **Fine-tuning:** Follow guidance by [Unsloth](https://unsloth.ai/docs/models/embeddinggemma-2) for how to fine-tune EmbeddingGemma 2 for your use cases.
Explore our [developer guide](https://developers.googleblog.com/en/embeddinggemma-2-the-developer-guide/), [documentation](https://ai.google.dev/gemma/docs/embeddinggemma), and guides for [inference](https://ai.google.dev/gemma/docs/embeddinggemma/inference-embeddinggemma-with-sentence-transformers) and [fine-tuning](https://ai.google.dev/gemma/docs/embeddinggemma/fine-tuning-embeddinggemma-with-sentence-transformers).