# Meta 发布 Muse Wonder 和 Muse Wonder Full,Artificial Analysis 实测智能水平较前代显著提升
> 原标题:Muse Wonder and Muse Wonder Full: a material jump in intelligence over previous Meta models
- 来源:Artificial Analysis 完整文章
- 发布时间:2026-10-11T16:00:00.000Z
- AIHOT:https://aihot.news/items/v3pogrzxrk9oba4blox86d0w8
- 原文:https://artificialanalysis.ai/articles/muse-wonder
## 摘要
Meta 发布 Muse Wonder 和 Muse Wonder Full 两款模型,在 Artificial Analysis Intelligence Index v4.3 上分别得 52 和 56 分(max reasoning effort)。
## 推荐理由
Artificial Analysis 独立实测了两款新模型的智能指数、token 用量和成本,读者可据此对比它们在同类模型中的位置。
## 正文 · 中文译文
[查看模型页面](https://artificialanalysis.ai/models/muse-wonder-full)
**Meta 发布了 Muse Wonder 和 Muse Wonder Full,在最大推理努力下,Artificial Analysis Intelligence Index v4.3 得分分别为 52 和 56——相比 Muse Spark 1.3(max)的 48 均有实质性提升,而发布间隔仅 6 周**
Muse Wonder 已在 Meta 的第一方 API 上向用户开放,而 Muse Wonder Full 目前仅对 Muse Code 用户开放。Meta 指出,这两款模型均面向个人和专业智能体用途设计
**关键要点:**
➤ **两款模型在整体 Intelligence Index 得分上均实现了实质性跃升。** Muse Wonder Full(max)在全部十项 Intelligence Index 评估中均优于 Muse Spark 1.3(max),提升 8 分至 56。提升最大的是智能体评估:Terminal-Bench 4.0(+24 分,33% 至 57%)、GDPval-AA v2.1(+176 Elo,1681 至 1857)和 AA-Briefcase(+148 Elo,1581 至 1729)。Muse Wonder(max)提升 4 个 Intelligence Index 分,达到 52,相比 Muse Spark 1.3(max)在 Terminal-Bench 4.0(33% 至 52%)和 AutomationBench-AA(58% 至 68%)上有显著改进
➤ **Muse Wonder Full(max)在十项 Intelligence Index 评估中有六项进入前三,在智能体知识工作和科学推理方面尤为突出。** 在智能体知识工作方面,它在 GDP.pdf(33%)上以微弱优势领先,在 GDPval-AA v2.1(1857 Elo)上排名第 2,在 AA-Briefcase(1729 Elo)和 AutomationBench-AA(71%)上均排名第 3。在科学推理方面,它以 33% 位居 CritPt 排行榜榜首,并以 63% 在 SciCode 上排名第 3。这延续了 Muse Spark 1.3(max)的相对优势,后者在这两个领域也表现出特别的能力
➤ **两款模型使用的输出 token 均少于 Muse Spark 1.3(max)。** Muse Wonder(max)和 Muse Wonder Full(max)在每个 Intelligence Index 任务上均使用约 54k 输出 token,较 Muse Spark 1.3(max,60k)下降约 10%。这一用量低于同等智能水平的模型 Gemini 4 Argon(high,62k)和 Claude Fable 5.1(max w/ fallback,78k),但高于 GPT-6.1 Sol(max,38k)和 GPT-6 Astra(max,27k)。Muse Wonder Full(max)在每个 Intelligence Index 任务上使用的输入 token 比 Muse Wonder(max)少 16%(6.44M 对 7.69M),这意味着它既更智能,也更节省 token
➤ **Muse Wonder(max)的每任务成本高于大多数同等智能水平的模型。** 尽管输出 token 使用高效,但高昂的 API 定价(每百万输入 token 4 美元,每百万输出 token 20 美元)以及高输入 token 用量(每任务 7.69M)将 Muse Wonder(max)的成本推高至每个 Intelligence Index 任务 4.52 美元。这低于 Claude Fable 5.1(max w/ fallback,7.63 美元)、Claude Opus 5.5(max w/ fallback,5.98 美元)和 Claude Sonnet 5.5(max w/ fallback,5.46 美元),但高于 GPT-6 Astra(max,3.26 美元)、Gemini 4 Argon(high,1.99 美元)、GPT-6.1 Sol(max,0.72 美元)及其前代 Muse Spark 1.3(max,1.60 美元)。Muse Wonder Full 不按 token 定价,因此没有可用的每任务成本数据
➤ **两款模型在 Coding Agent 性能上均有显著提升。** Muse Wonder Full 在 Muse Code 中以最大努力在 Artificial Analysis Coding Agents Index 上达到 68,与 Claude Code 搭配 Sonnet 5.5(max,68)和 Opus 5.5(max,66)相当。Muse Wonder(max)得分为 63。相比 Muse Code 搭配 Muse Spark 1.3(max)的 54 分,这些都是实质性提升
**两款新模型的其他细节:**
➤ **上下文窗口:**各 100 万 token,与 Muse Spark 1.3 相同
➤ **定价:**Muse Wonder 为每 100 万 token 输入 $4 / 缓存输入 $0.20 / 输出 $20。Muse Wonder Full 不按 token 计价
➤ **输入模态:**文本、图像、视频和音频
➤ **输出模态:**文本
➤ **可用性:**Muse Wonder 在发布时可在 Meta 的第一方 API 和 Muse Code 上使用,而 Muse Wonder Full 仅对 Muse Code 用户开放
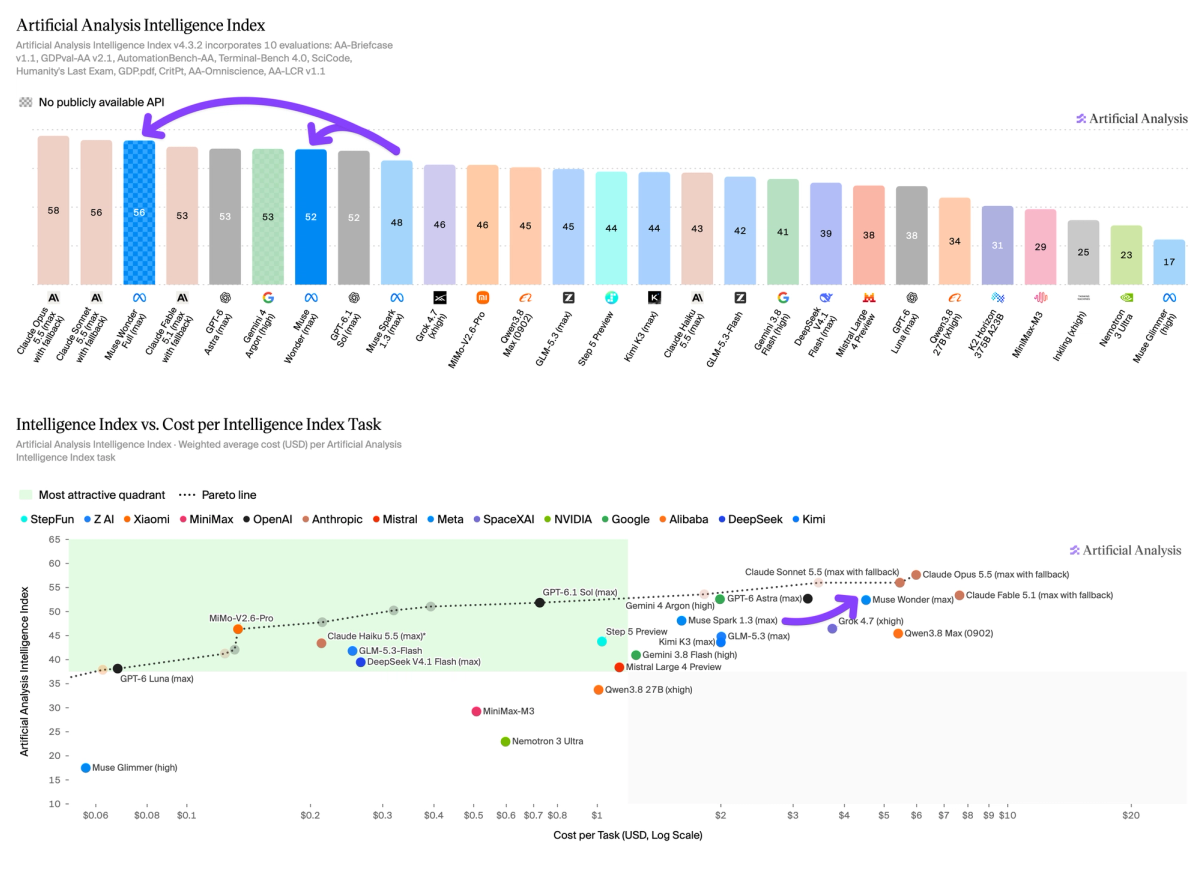
**Muse Wonder Full(max)在十项 Artificial Analysis Intelligence Index v4.3 评估中的六项上进入前三名:**
➤ 在 CritPt(33%)和 GDP.pdf(33%)上排名第 1
➤ 在 GDPval-AA v2.1(1857 Elo)上排名第 2
➤ 在 AA-Briefcase(1729 Elo)、AutomationBench-AA(71%)和 SciCode(63%)上排名第 3
在 CritPt 和 GDP.pdf 上的领先优势很小,最接近的竞争对手得分为 31-32%。在 GDPval-AA v2.1 上,其结果处于 Claude Opus 5.5(max w/ fallback,1866)和 Claude Sonnet 5.5(max w/ fallback,1838)的置信区间内
相较于 Muse Spark 1.3(max),其最大提升来自 Terminal-Bench 4.0:从 33% 提升至 57%,与 Gemini 4 Argon(high)持平
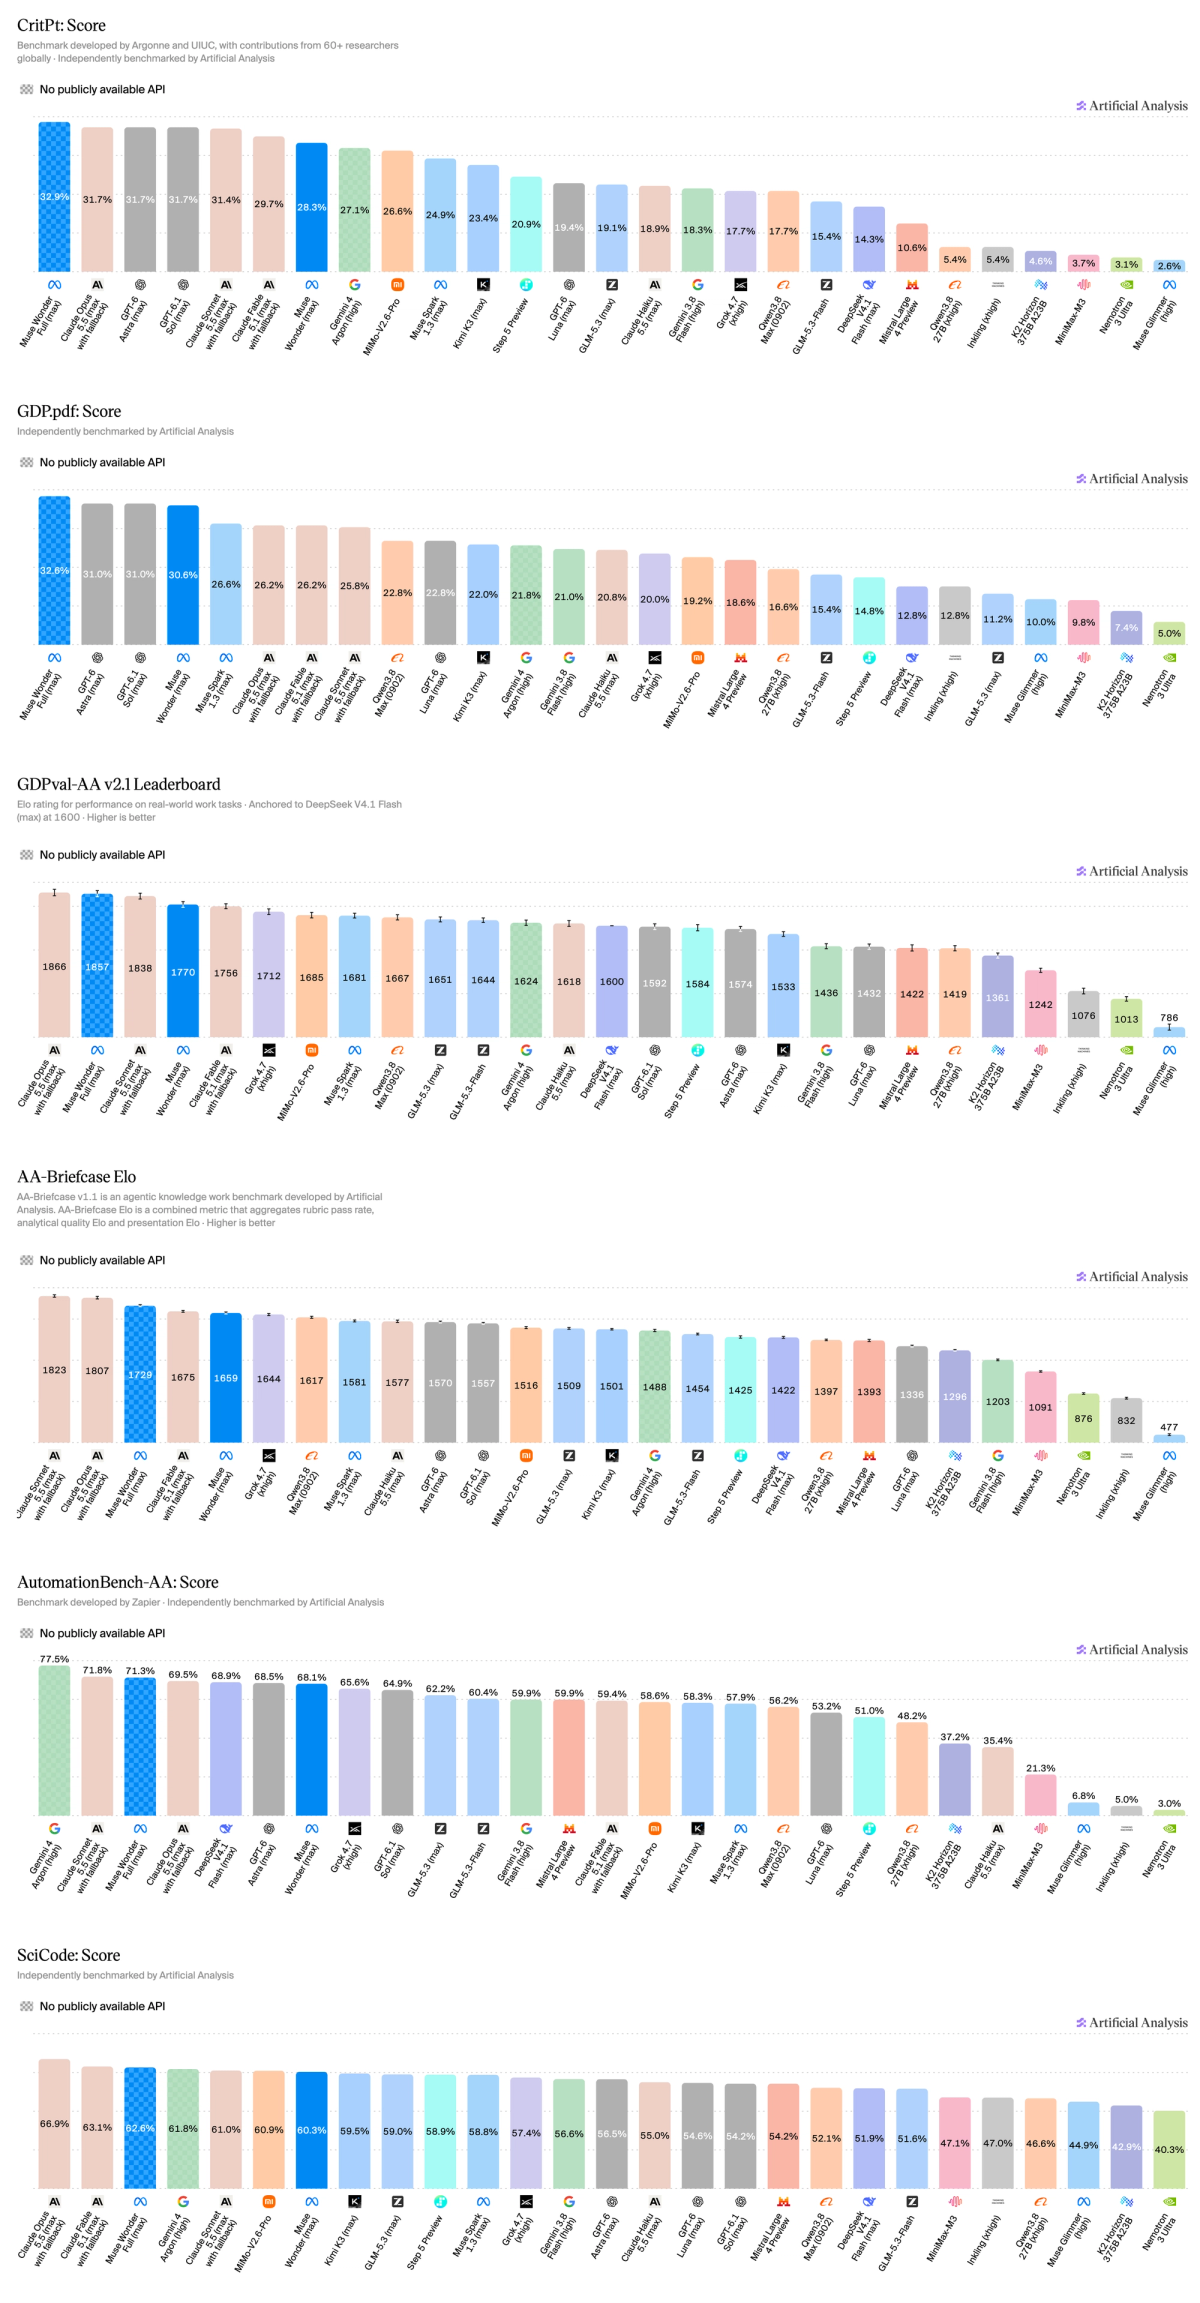
**Muse Wonder(max)每项 Artificial Analysis Intelligence Index 任务成本为 $4.52,是 Muse Spark 1.3(max,$1.60)的 2.8 倍,原因是更高的每 token 价格和更高的输入 token 使用量**
➤ **Token 定价:**每 100 万输入 token $4,缓存 $0.20,输出 $20,高于 Muse Spark 1.3 的 $1.25 / $0.15 / $4.25。这与 Claude Opus 5.5 相同,是 Claude Sonnet 5.5、Gemini 4 Argon 和 GPT-6.1 Sol($2/$10)各自的两倍,并比 GPT-6 Astra 和 Claude Fable 5.1($10/$50)低 60%
➤ **输入:**每项任务 769 万输入 token,比 Muse Spark 1.3(max,603 万)多 28%,是 Gemini 4 Argon(high)、GPT-6.1 Sol(max)和 GPT-6 Astra(max)的 2-7 倍。输入占其每项任务成本的 $3.43(76%),由 $1.92 缓存写入、$1.44 缓存命中和 $0.07 未缓存输入组成
➤ **输出:**每项任务约 5.4 万输出 token($1.08),比 Muse Spark 1.3(max,6 万)少 10%
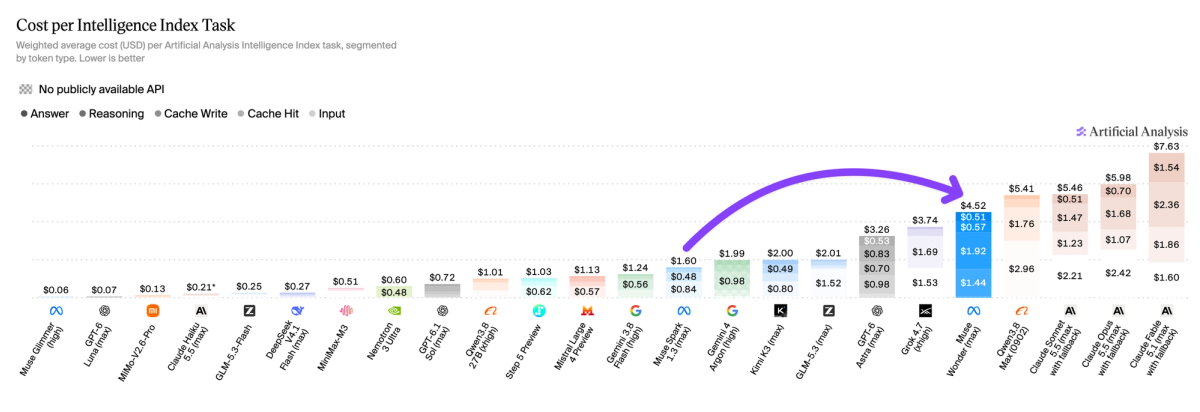
**知识仍是这两个模型的相对弱项,但极低的幻觉率缓解了这一问题。**在 AA-Omniscience 上,Muse Wonder Full(max)得分为 30,Muse Wonder(max)得分为 25,与 Muse Spark 1.3(max)持平,低于 Claude Opus 5.5(46)、GPT-6 Astra(43)、Gemini 4 Argon(42)和 Claude Sonnet 5.5(32)
Muse Wonder Full(max)的 5 分提升来自其幻觉率降低(从 33% 降至 23%),这使其跻身测试中幻觉最少的模型之列:在 Intelligence Index 得分 45 或以上的所有模型中,其幻觉率第二低,仅次于 Gemini 4 Argon(high,15%)。Muse Wonder(max)以 27% 位列第三
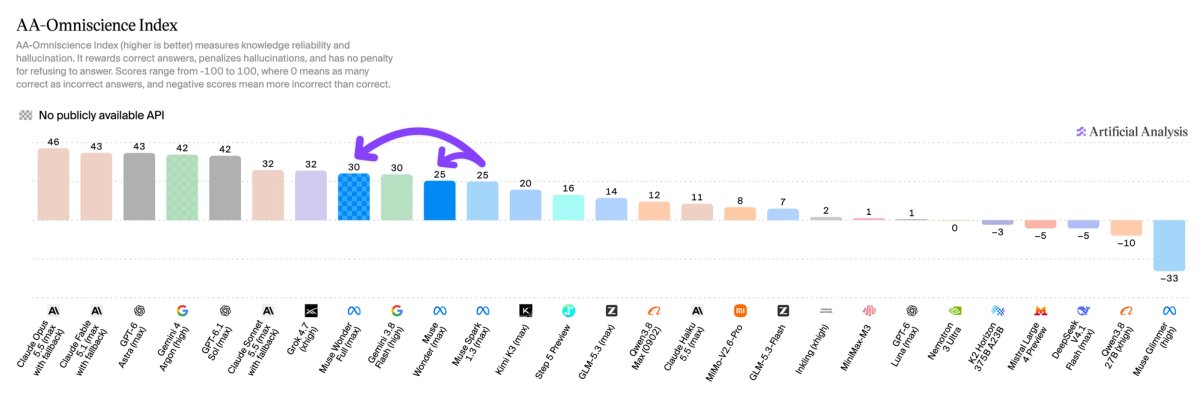
**Muse Wonder Full(max)和 Muse Wonder(max)的完整 Artificial Analysis Intelligence Index 结果:**
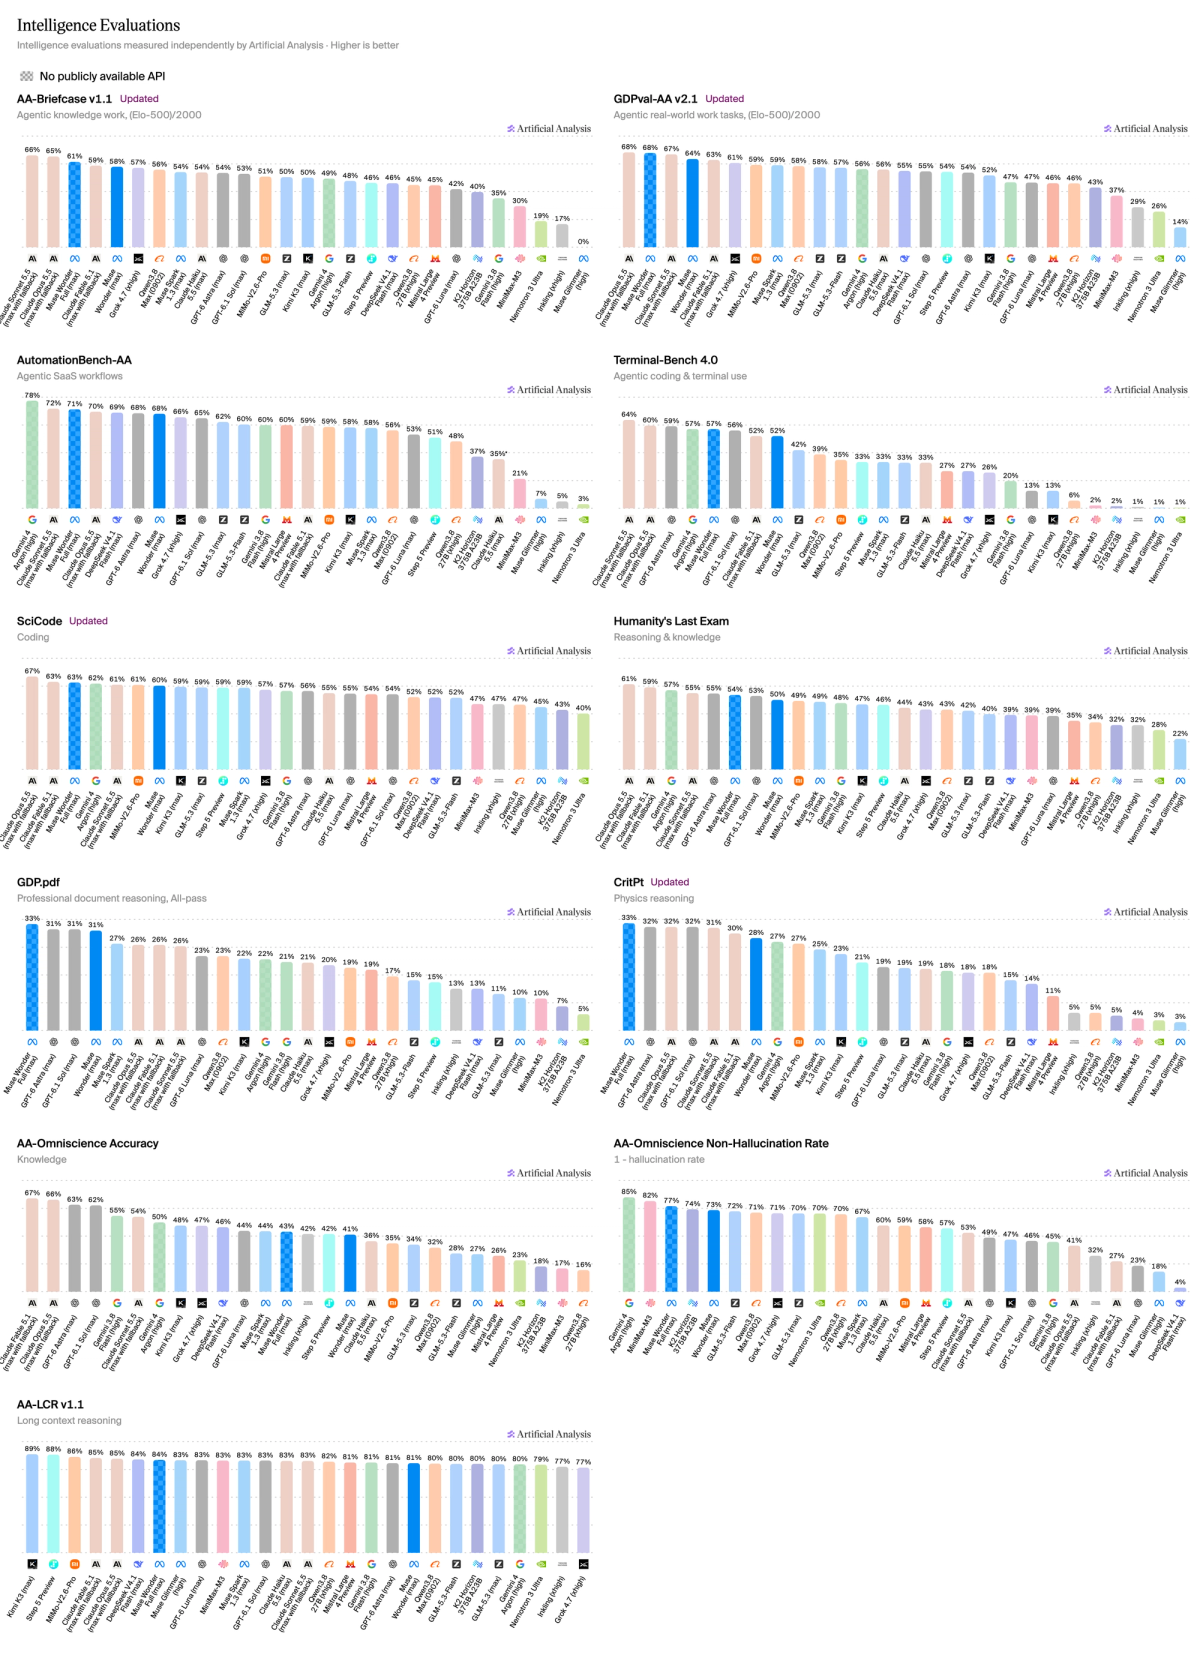
在以下网址将 Muse Wonder Full(max)和 Muse Wonder(max)与其他领先模型进行比较:[https://artificialanalysis.ai/models/muse-wonder-full](https://artificialanalysis.ai/models/muse-wonder-full) 和 [https://artificialanalysis.ai/models/muse-wonder](https://artificialanalysis.ai/models/muse-wonder)
## 正文 · 原文
[See model page](https://artificialanalysis.ai/models/muse-wonder-full)
**Meta has released Muse Wonder and Muse Wonder Full, achieving Artificial Analysis Intelligence Index v4.3 scores of 52 and 56 at max reasoning effort - each a material gain over Muse Spark 1.3 (max) at 48, with a release gap of only 6 weeks**
Muse Wonder is available for users on Meta's first-party API, while Muse Wonder Full is currently only available for Muse Code users. Meta notes that each model is designed for personal and professional agent use
**Key takeaways:**
➤ **Both models exhibit a material jump in overall Intelligence Index score.** Muse Wonder Full (max) improves on Muse Spark 1.3 (max) across all ten Intelligence Index evaluations, gaining 8 points to 56. The largest gains were seen in agentic evaluations: Terminal-Bench 4.0 (+24 points, 33% to 57%), GDPval-AA v2.1 (+176 Elo, 1681 to 1857), and AA-Briefcase (+148 Elo, 1581 to 1729). Muse Wonder (max) gains 4 Intelligence Index points and lands at 52, with notable improvements vs. Muse Spark 1.3 (max) in Terminal-Bench 4.0 (33% to 52%) and AutomationBench-AA (58% to 68%)
➤ **Muse Wonder Full (max) places in the top three on six of the ten Intelligence Index evaluations, and is particularly strong in agentic knowledge work and scientific reasoning.** In agentic knowledge work, it narrowly leads on GDP.pdf (33%), ranks #2 on GDPval-AA v2.1 (1857 Elo), and #3 on both AA-Briefcase (1729 Elo) and AutomationBench-AA (71%). In scientific reasoning, it tops the CritPt leaderboard at 33% and ranks #3 on SciCode with 63%. This builds on the relative strengths of Muse Spark 1.3 (max), which also showed particular ability in these two domains
➤ **Both models use fewer output tokens than Muse Spark 1.3 (max).** Muse Wonder (max) and Muse Wonder Full (max) each use around 54k output tokens per Intelligence Index task, down ~10% from Muse Spark 1.3 (max, 60k). This usage is lower than similarly intelligent models Gemini 4 Argon (high, 62k) and Claude Fable 5.1 (max w/ fallback, 78k), but higher than GPT-6.1 Sol (max, 38k) and GPT-6 Astra (max, 27k). Muse Wonder Full (max) uses 16% fewer input tokens per Intelligence Index task than Muse Wonder (max) (6.44M vs 7.69M), meaning it is both more intelligent and more token-efficient
➤ **Cost per Task for Muse Wonder (max) lands higher than most similarly intelligent models.** Despite efficient output token use, premium API pricing ($4 per million input tokens, $20 per million output tokens) and high input token use (7.69M per task) push Muse Wonder (max)'s cost to $4.52 per Intelligence Index task. This is lower than Claude Fable 5.1 (max w/ fallback, $7.63), Claude Opus 5.5 (max w/ fallback, $5.98), and Claude Sonnet 5.5 (max w/ fallback, $5.46), but higher than GPT-6 Astra (max, $3.26), Gemini 4 Argon (high, $1.99), GPT-6.1 Sol (max, $0.72), and its predecessor Muse Spark 1.3 (max, $1.60). Muse Wonder Full is not priced per token, so no Cost per Task figure is available
➤ **Both models gain significantly in Coding Agent performance.** Muse Wonder Full achieves 68 on the Artificial Analysis Coding Agents Index at max effort in Muse Code, alongside Claude Code with Sonnet 5.5 (max, 68) and Opus 5.5 (max, 66). Muse Wonder (max) scores 63. These represent material gains over Muse Code with Muse Spark 1.3 (max), which scores 54
**Other details for the two new models:**
➤ **Context windows:** 1M tokens each, unchanged from Muse Spark 1.3
➤ **Pricing:** for Muse Wonder, $4 input / $0.20 cached input / $20 output per 1M tokens. Muse Wonder Full is not priced per token
➤ **Input modalities:** text, image, video, and audio
➤ **Output modalities:** text
➤ **Availability:** Muse Wonder is available on Meta's first-party API and Muse Code at launch, while Muse Wonder Full is only available to Muse Code users

**Muse Wonder Full (max) places in the top three on six of the ten Artificial Analysis Intelligence Index v4.3 evaluations:**
➤ #1 on CritPt (33%) and GDP.pdf (33%)
➤ #2 on GDPval-AA v2.1 (1857 Elo)
➤ #3 on AA-Briefcase (1729 Elo), AutomationBench-AA (71%) and SciCode (63%)
The leads on CritPt and GDP.pdf are narrow, with the nearest competitors scoring 31-32%. On GDPval-AA v2.1, its result is within the confidence intervals of Claude Opus 5.5 (max w/ fallback, 1866) and Claude Sonnet 5.5 (max w/ fallback, 1838)
Its largest improvement over Muse Spark 1.3 (max) is Terminal-Bench 4.0: 33% to 57%, bringing it level with Gemini 4 Argon (high)

**Muse Wonder (max) costs $4.52 per Artificial Analysis Intelligence Index task, 2.8x Muse Spark 1.3 (max, $1.60), driven by higher per-token prices and higher input token use**
➤ **Token pricing:** $4 per 1M input tokens, $0.20 cached and $20 output, up from $1.25 / $0.15 / $4.25 for Muse Spark 1.3. This matches Claude Opus 5.5, is double each of Claude Sonnet 5.5, Gemini 4 Argon, and GPT-6.1 Sol ($2/$10), and is 60% below GPT-6 Astra and Claude Fable 5.1 ($10/$50)
➤ **Input:** 7.69M input tokens per task, 28% more than Muse Spark 1.3 (max, 6.03M) and 2-7x Gemini 4 Argon (high), GPT-6.1 Sol (max) and GPT-6 Astra (max). Input is $3.43 (76%) of its cost per task, composed of $1.92 cache writes, $1.44 cache hits and $0.07 uncached input
➤ **Output:** around 54k output tokens per task ($1.08), 10% fewer than Muse Spark 1.3 (max, 60k)

**Knowledge remains a relative weakness for both models, but this is mitigated by very low hallucination rates.** On AA-Omniscience, Muse Wonder Full (max) scores 30 and Muse Wonder (max) scores 25, level with Muse Spark 1.3 (max), below Claude Opus 5.5 (46), GPT-6 Astra (43), Gemini 4 Argon (42), and Claude Sonnet 5.5 (32)
Muse Wonder Full (max)'s 5-point gain comes from lowering its hallucination rate (33% to 23%), which places it among the least-hallucinating models tested: it has the second-lowest hallucination rate of any model scoring 45 or more on the Intelligence Index, behind only Gemini 4 Argon (high, 15%). Muse Wonder (max) is third at 27%

**Full Artificial Analysis Intelligence Index results for Muse Wonder Full (max) and Muse Wonder (max):**

Compare Muse Wonder Full (max) and Muse Wonder (max) with other leading models at: [https://artificialanalysis.ai/models/muse-wonder-full](https://artificialanalysis.ai/models/muse-wonder-full) and [https://artificialanalysis.ai/models/muse-wonder](https://artificialanalysis.ai/models/muse-wonder)